Congratulations to the authors of “Do As I Can, Not As I Say: Grounding Language in Robotic Affordances” (see the blog at https://
goo.gle/3QRJhgl) for winning the Special Innovation Award at @corl_conf
! #CoRL2022
MACHINE LEARNING
-
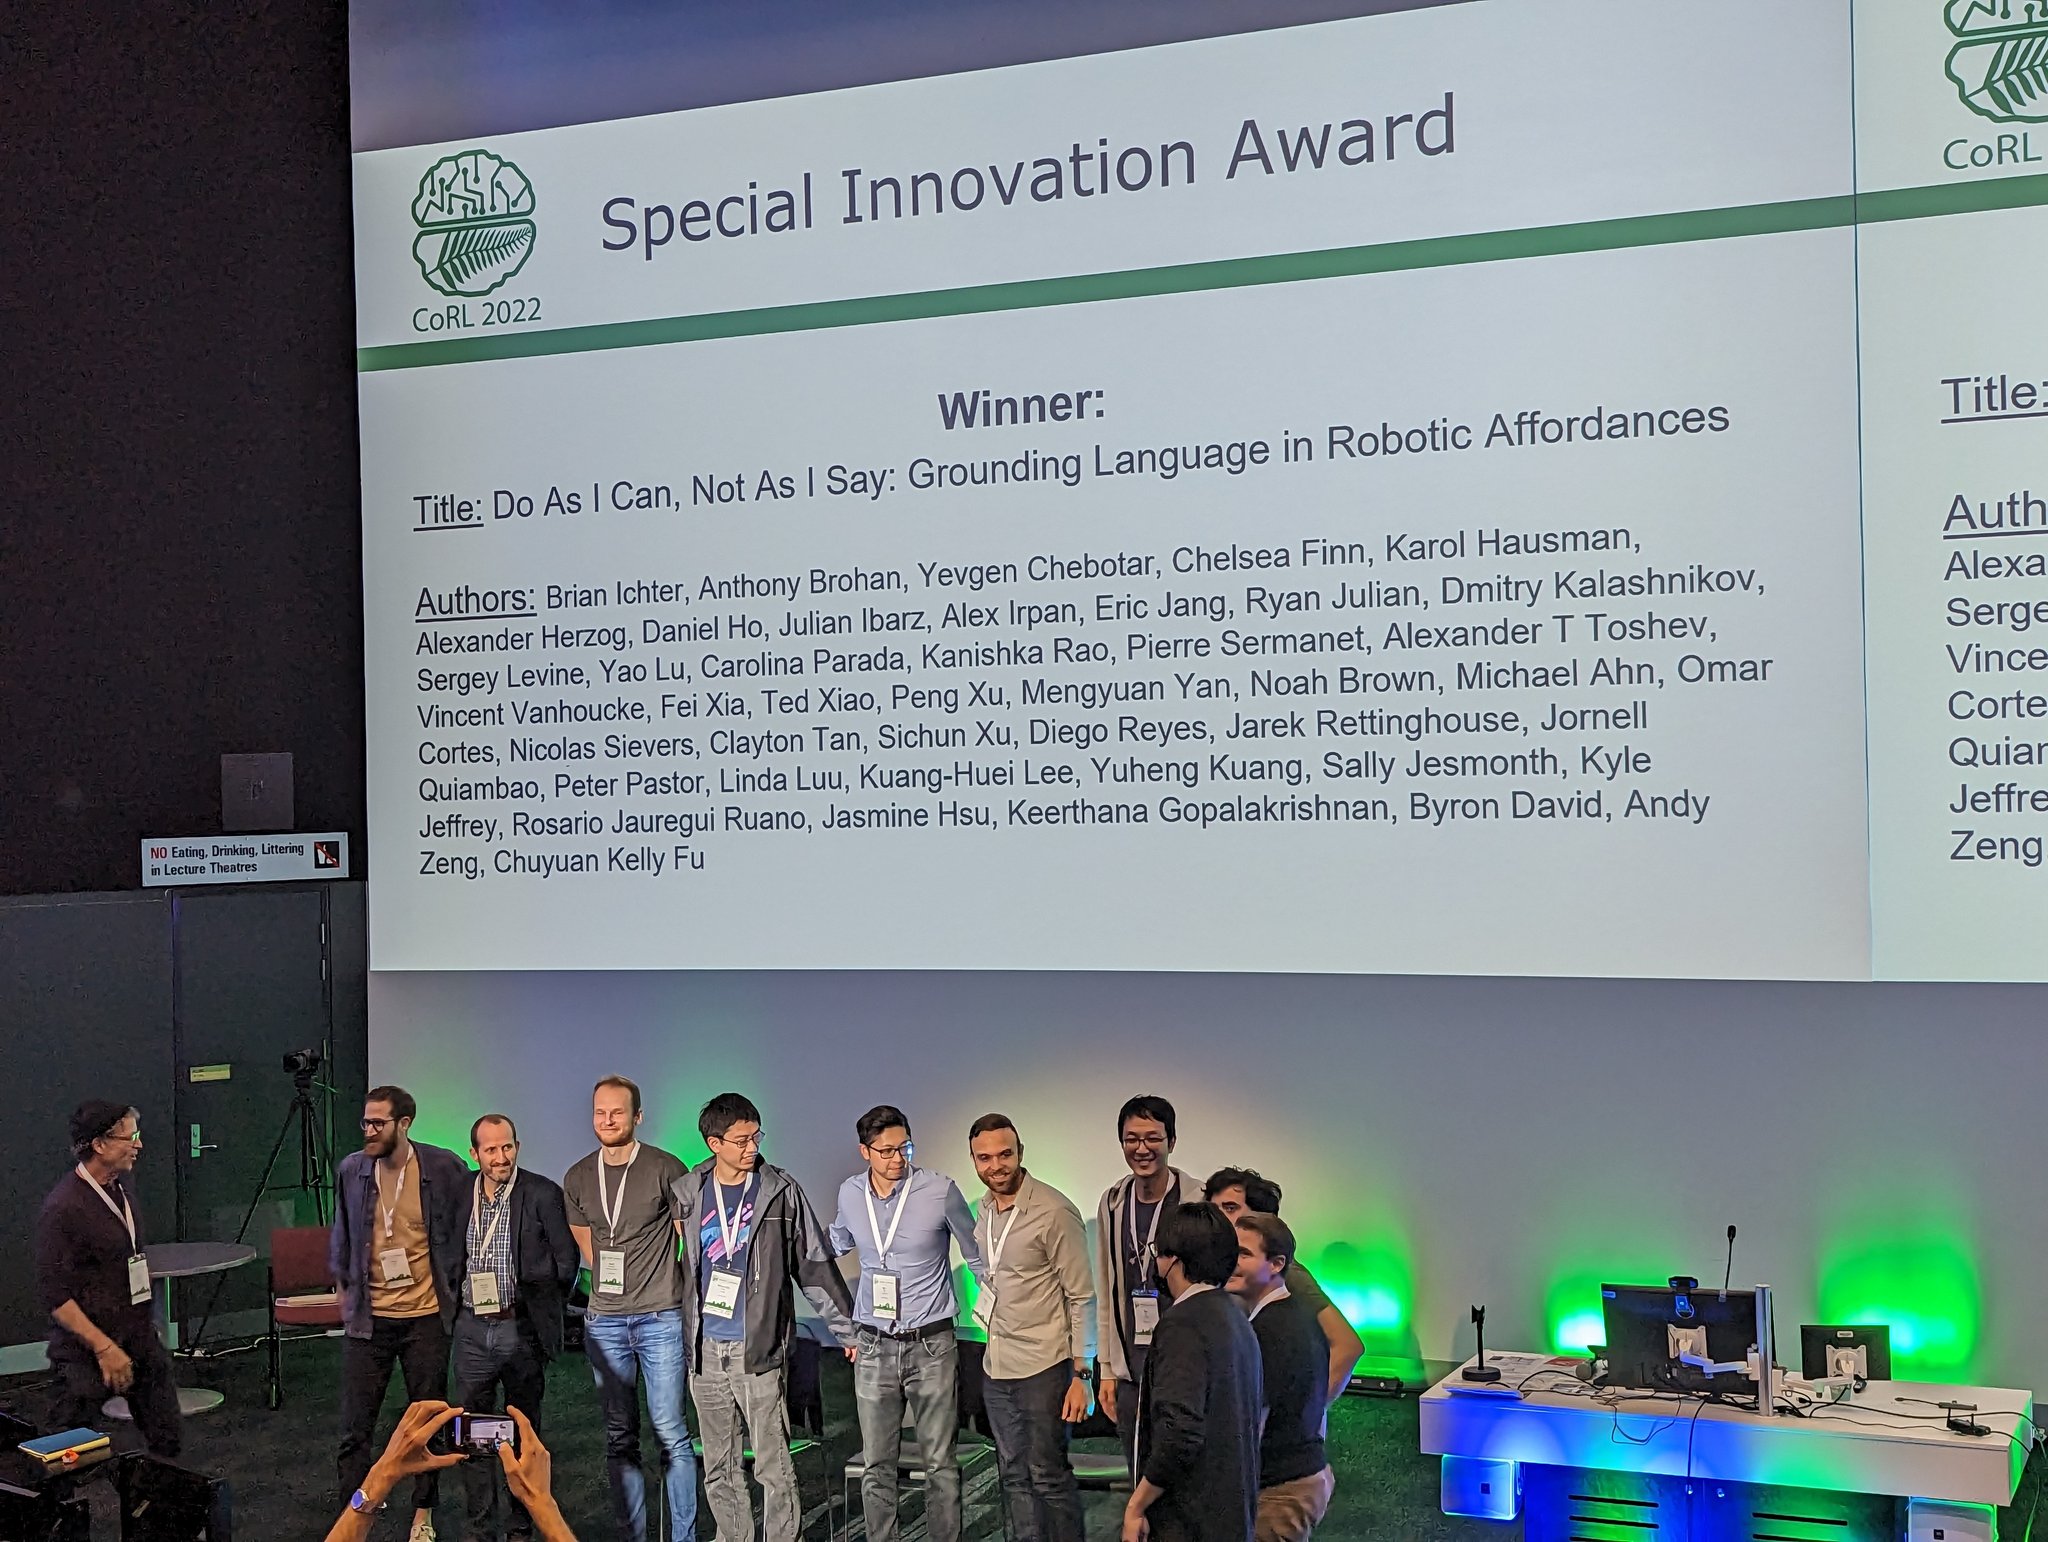
Award-Winning Research on Language Grounding in Robotic Affordances
By
–
-

Following Strategy for High Engagement Influencers in Tech
By
–
Or, were looking to follow new people who engage often with you – example, “bar plot top 20 @amasad doesn't follow but keeps them engaged” https://
perplexity.ai/sql?uuid=48f55
773-6276-4e22-9e13-287366e34159
… -
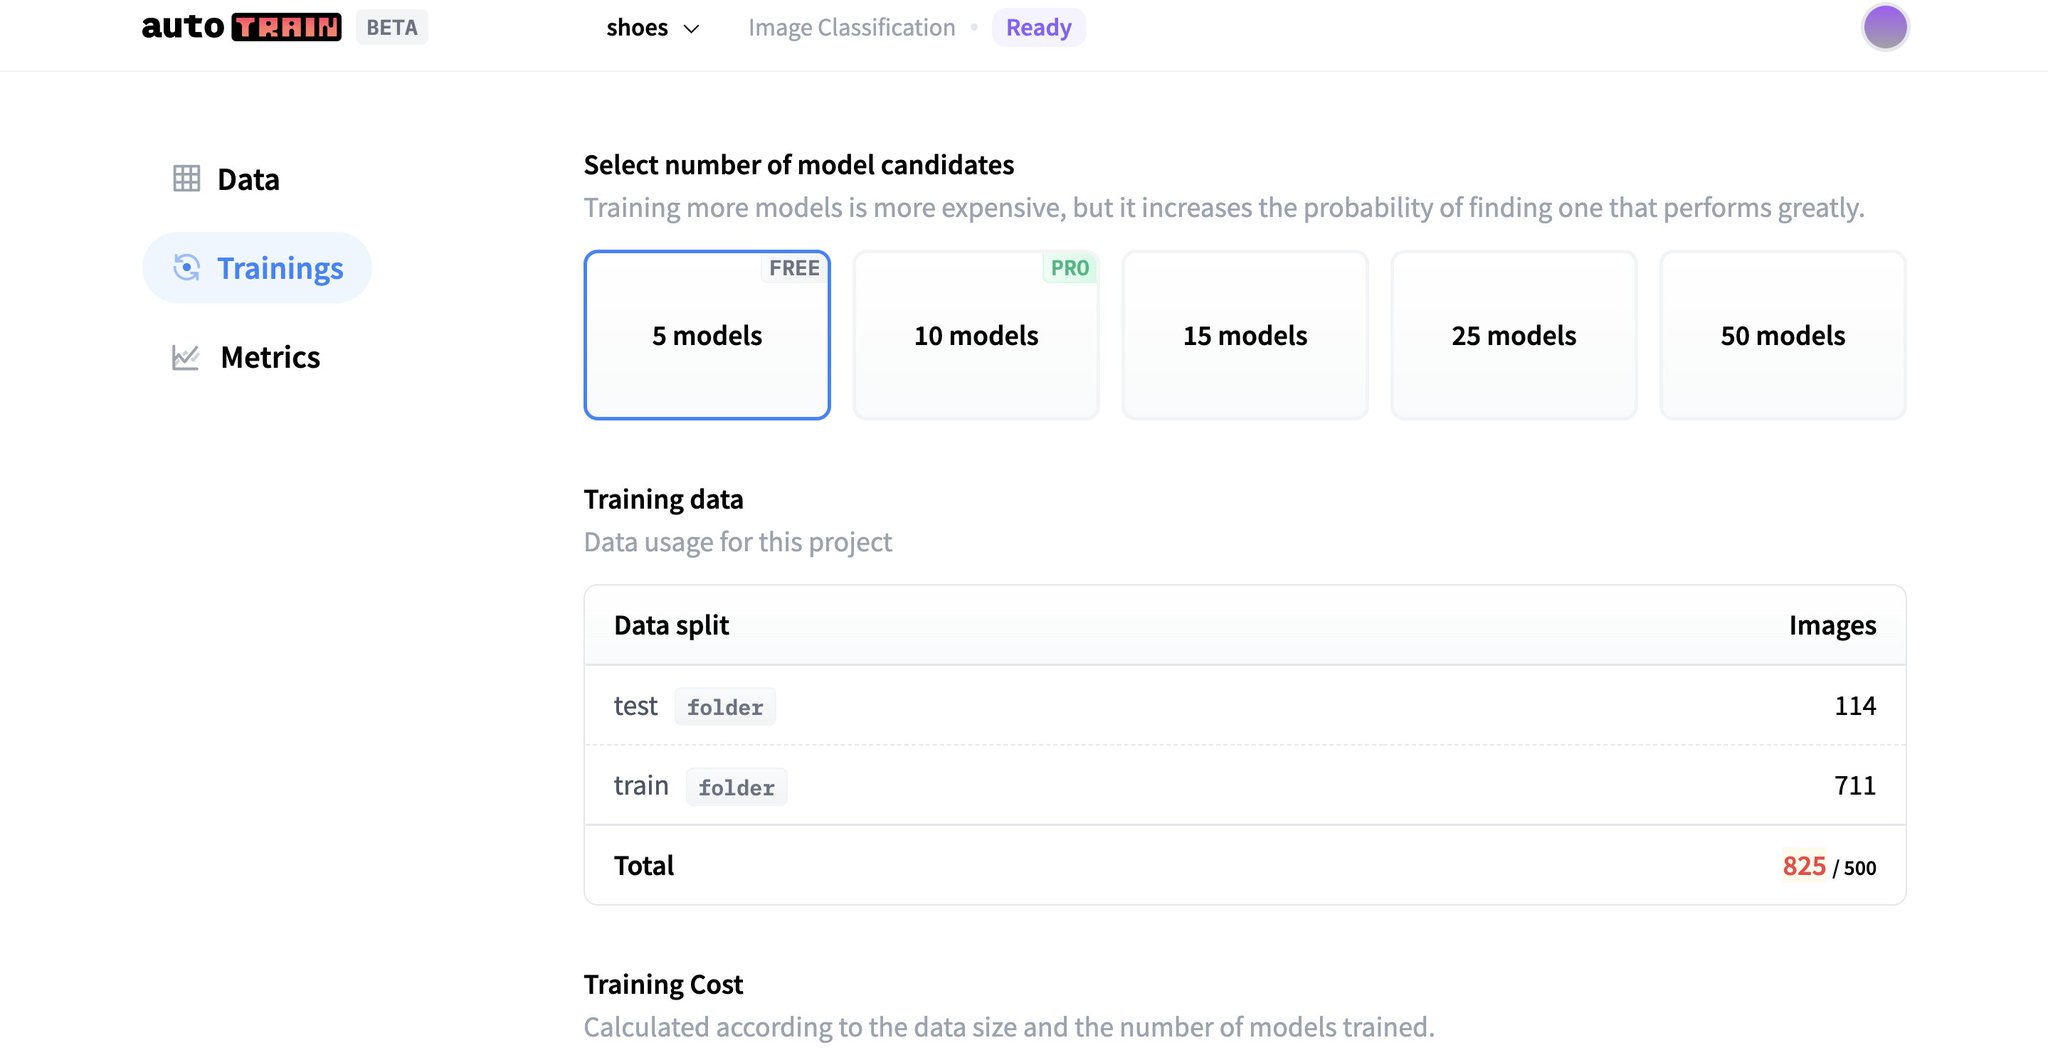
Hugging Face AutoTrain: Free Model Training Without Pro Subscription
By
–
Now you don't need a pro subscription on Hugging Face to train more than 5 models for a project using AutoTrain!!! However, if you have a PRO account, you can train up to 10 models per project for FREE! Try AutoTrain NOW: http://
hf.co/AutoTrain -
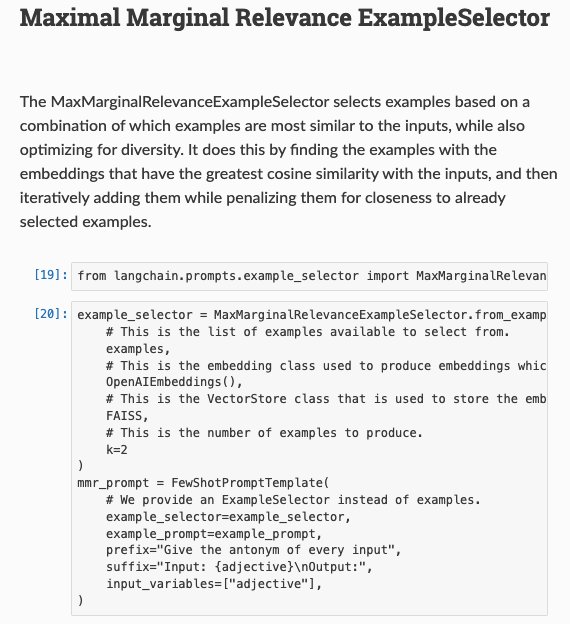
MMR Example Selector for Optimal Contextual Diversity
By
–
Max Marginal Relevance (MMR) Example Selector Based on this preprint by @xiye_nlp et al, the MMR example selector chooses diverse, in-context examples H/t @johnjnay for surfacing this paper Docs: https://langchain.readthedocs.io/en/latest/examples/prompts/prompt_management.html Original Paper: https://x.com/xiye_nlp/status/1603821850592628738?s=20&t=wQPcRd8IJ8URbmytuYP7QA
-
Gradient Backpropagation and Frequent Word Prioritization in Training
By
–
Because we sum, the gradients for each token get backpropagated to all the rows that were used for it. So with enough training, the model ends up at a good compromise. Frequent words are naturally prioritised in this, because they'll simply have more gradients.
-
Hash Embedding Performance on Small Datasets Analysis
By
–
However, the hash embedding doesn't do so well if the datasets are too small. That's one of the results that I found really useful in this tech report. It's great to have this all explored more thoroughly, and we look forward to publishing more experiments like this in future.
-
spaCy’s Hashing Approach for Word Representations Learning
By
–
This is almost what we do in spaCy — it's just that, instead of reserving the first 9900 rows for common words, we just use the hashing. Given that the assignment of words to shared rows is arbitrary, how can the model learn good representations?
-
Hashing Unknown Words to Shared Vector Rows for Rare Words
By
–
Imagine we gave the unknowns the last 100 rows instead. When we see an unknown word, we'll hash its word form, and mod the result to pick a row for it. Each unknown word will share its vector with lots of others, but its vector-mates are probably rare.
-
Hashing Trick for Fixed-Size Embedding Tables in Fine-Tuning
By
–
Resizing the embedding table for fine-tuning is pretty awkward. We'd rather have some way of making sure that novel words can get a unique representation, even from a fixed-size embedding table. The hashing trick achieves this.
-
Embedding Table Strategy: Frequent Words and Shared Vectors
By
–
Let's say we have 10k rows in the embedding table. In a standard embedding table, you give each of the 9999 most frequent words their own vector, and have all the others share the last vector.