What a wonderful experience in Spain late last year to accept the Princess of Asturias Awards for Technical & Scientific Research w/
@ylecun
. Thanks to the @FPA
, the Spanish Royal Family @CasaReal
, & the people of Oviedo who welcomed us so warmly + the amazing #AlphaFold artwork!
MACHINE LEARNING
-

Princess of Asturias Award for AI Technical Research with AlphaFold
By
–
-
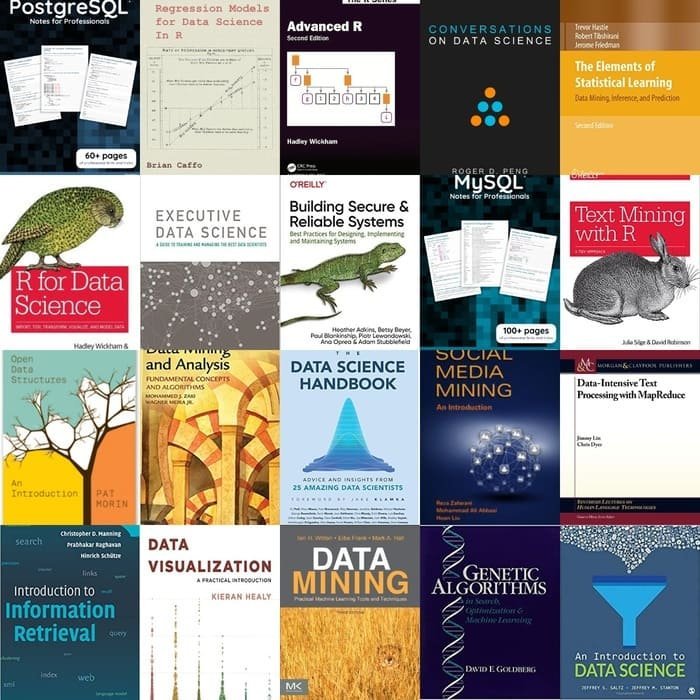
100+ Free Data Science Books for Machine Learning and AI
By
–
Free eBooks: 100+ Free Data Science Books http://
bit.ly/3AAD4At #NeuralNetworks #MachineLearning #TensorFlow #100DaysOfCode #BigData #Analytics #DevCommunity #Programming #IoT #javascript #Linux #Cloud #Serverless #womenwhocode #Python #RStats #DeepLearning #AI #DataScience -

Factual Hallucination in ChatGPT and Claude Discussed
By
–
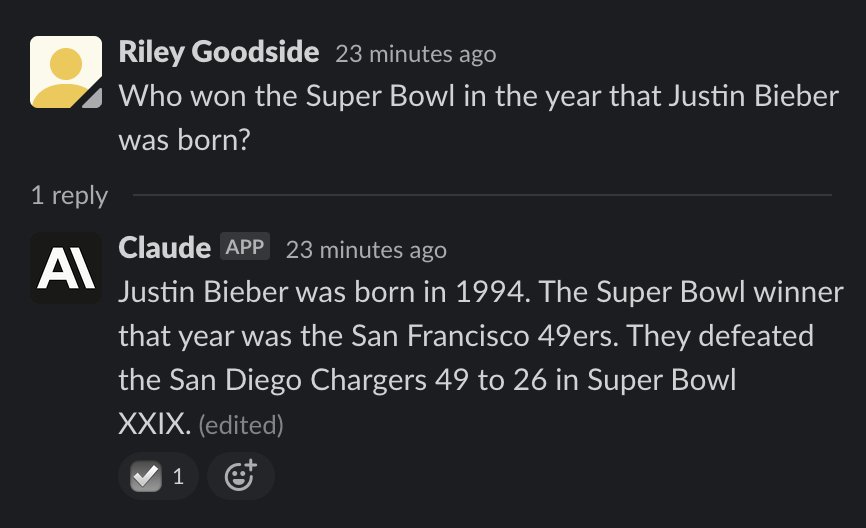
Factual hallucination is still an issue for both ChatGPT and Claude. When asked, "Who won the Super Bowl in the year Justin Bieber was born?", Claude is usually wrong and ChatGPT is usually right. But even when right, ChatGPT is prone to including wrong, nonsensical details:
-
Bayesians Return to Statistics After AI Dominance Era
By
–
All those Bayesians that dominated AI for a while are now back to being statisticians.
-
LLM Tokenization Trick for EOT Emission
By
–
It’s not willing to produce what it thinks is an EOT token. You have to trick it by making it emit a sequence of tokens that re-tokenize to the EOT token after being turned into a string.
-
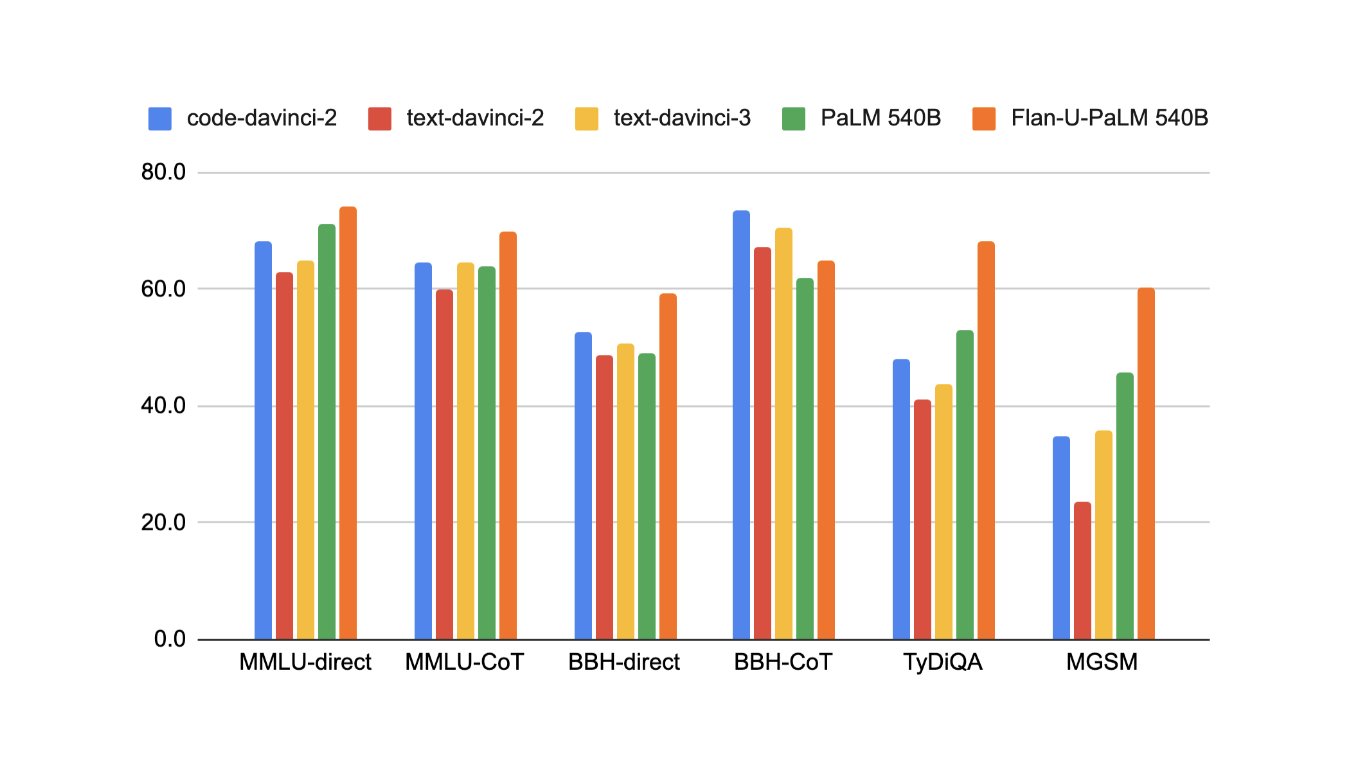
Comparing Text Davinci 2 and 3 on NLP Benchmarks
By
–
We compared text davinci 2 and text davinci 3 on a bunch of nlp benchmarks, see here:
-
Vector Search and Map-Reduce Chains for Document Question Answering
By
–
exactly! if doc is larger you can still prune with the vector search, so you may not need to chain. but you could also load more documents and do a map-reduce chain over them. See these docs for QA in general: https://
langchain.readthedocs.io/en/latest/use_
cases/question_answering.html
… and let us know if any questions! -
Technical mechanism of AI-driven voice synthesis
By
–
It generates a series of codes based on the phonemes and an audio recording of the speaker's voice.
— AI Breakfast (@AiBreakfast) 7 janvier 2023
These codes are then turned directly into a waveform, which allows it to generate speech that sounds like the speaker from just a small amount of reference audio.
Example (🔊): pic.twitter.com/HQvjJUnbiHIt generates a series of codes based on the phonemes and an audio recording of the speaker's voice. These codes are then turned directly into a waveform, which allows it to generate speech that sounds like the speaker from just a small amount of reference audio. Example ():
-
Technical architecture of the VALL-E generative audio model
By
–
Instead of turning text into a series of specific sounds (called phonemes) and then into a visual representation of the sound called a mel-spectrogram, and then into a waveform (a digital representation of sound that can be played through a speaker) VALL-E takes a shortcut:
-
VALL-E: A new approach to natural-sounding AI speech synthesis
By
–
VALL-E is significantly better at synthesizing natural-sounding speech and accurately reproducing the characteristics of a speaker compared to anything else available. VALL-E takes a different approach than previous systems for synthesizing speech: