More importantly, it can alert the AI systems themselves not to train on "synthetic data", which could help solve the recursive AI data problem (AI training itself on it's own output, AKA the machine learning version of eating your own vomit)
MACHINE LEARNING
-
Watermark tokens embedded with negligible impact on text quality.
By
–
Interestingly, the watermark tokens can be embedded with negligible impact on text quality.
-
Watermarking detects AI-generated text for readers and academia
By
–
These cryptic text signatures are indiscernible to the average reader, but reliably detectable by the algorithm. Watermarking can alert you when you're reading a web article that was AI generated (sorry, CNET) or be used in academia to detect "AI Plagiarism"
-
Watermark selects whitelist tokens and promotes them during sampling
By
–
The watermark works by selecting a randomized set of “whitelist” tokens before any text is generated, and then softly promoting use of those tokens during sampling. (a token can be a letter, word, numbers, punctuations or any other string that is useful for the specific task)
-

Watermarking AI text to detect ChatGPT-generated content
By
–
"Watermarking" AI-generated text. Researchers from University of Maryland propose a way to discretely embed (and detect) special tokens in order to accurately determine whether or not text was generated from something like ChatGPT. ↓
-
Domino MLOps Platform Expands Through TDSYNNEX Partnership
By
–
Domino has partnered with @TDSYNNEX to bring our #MLOps platform to thousands of channel partners and businesses, increasing the value of #ML and #AI investments and accelerating time-to-market. Learn more in this article by @RickWhiting1
: -
Emergence as Framework for Understanding Language Model Scaling
By
–
Overall, emergence is nice framework for viewing language models
– Emergent abilities cannot be predicted via scaling plots for small models
– Keep scaling, and we might see more emergent abilities 🙂 See our TMLR 2022 piece (w/ survey certification): -
U-shaped Scaling: Model Performance Recovery in Larger Language Models
By
–
Another newer example of emergence that I’m excited about is U-shaped scaling, where even if model performance goes down from small → medium models, it can go back up for large models. See our paper: https://
x.com/_jasonwei/stat
us/1588605909781319680
… Inverse scaling benchmark: -

Instruction Tuning as an Emergent Ability in Large Language Models
By
–
One of the most interesting emergent abilities IMO is instruction tuning. Anthropic and Flan-LaMDA suggest that zero-shot performance can improve from RLHF and NLP benchmark instruction tuning (although text-davinci usually loses to code-davinci). https://
arxiv.org/abs/2204.05862 -
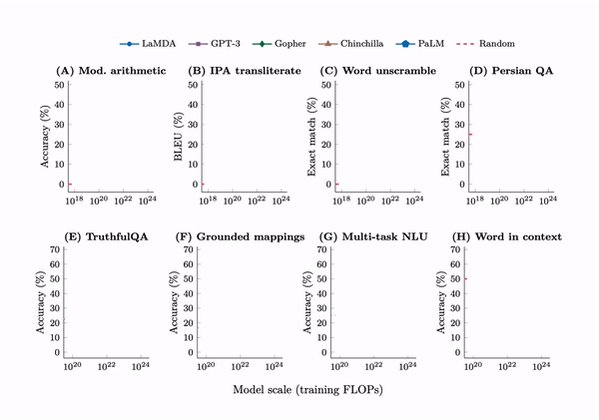
Emergent Abilities in Large Language Models Over Past Year
By
–
Throughout the past year, there have been hundreds of emergent abilities, which can only be observed in large-enough language models. I previously made a list of them (more than 100):https://t.co/QLfwNUeIBx
— Jason Wei (@_jasonwei) 25 janvier 2023Throughout the past year, there have been hundreds of emergent abilities, which can only be observed in large-enough language models. I previously made a list of them (more than 100):