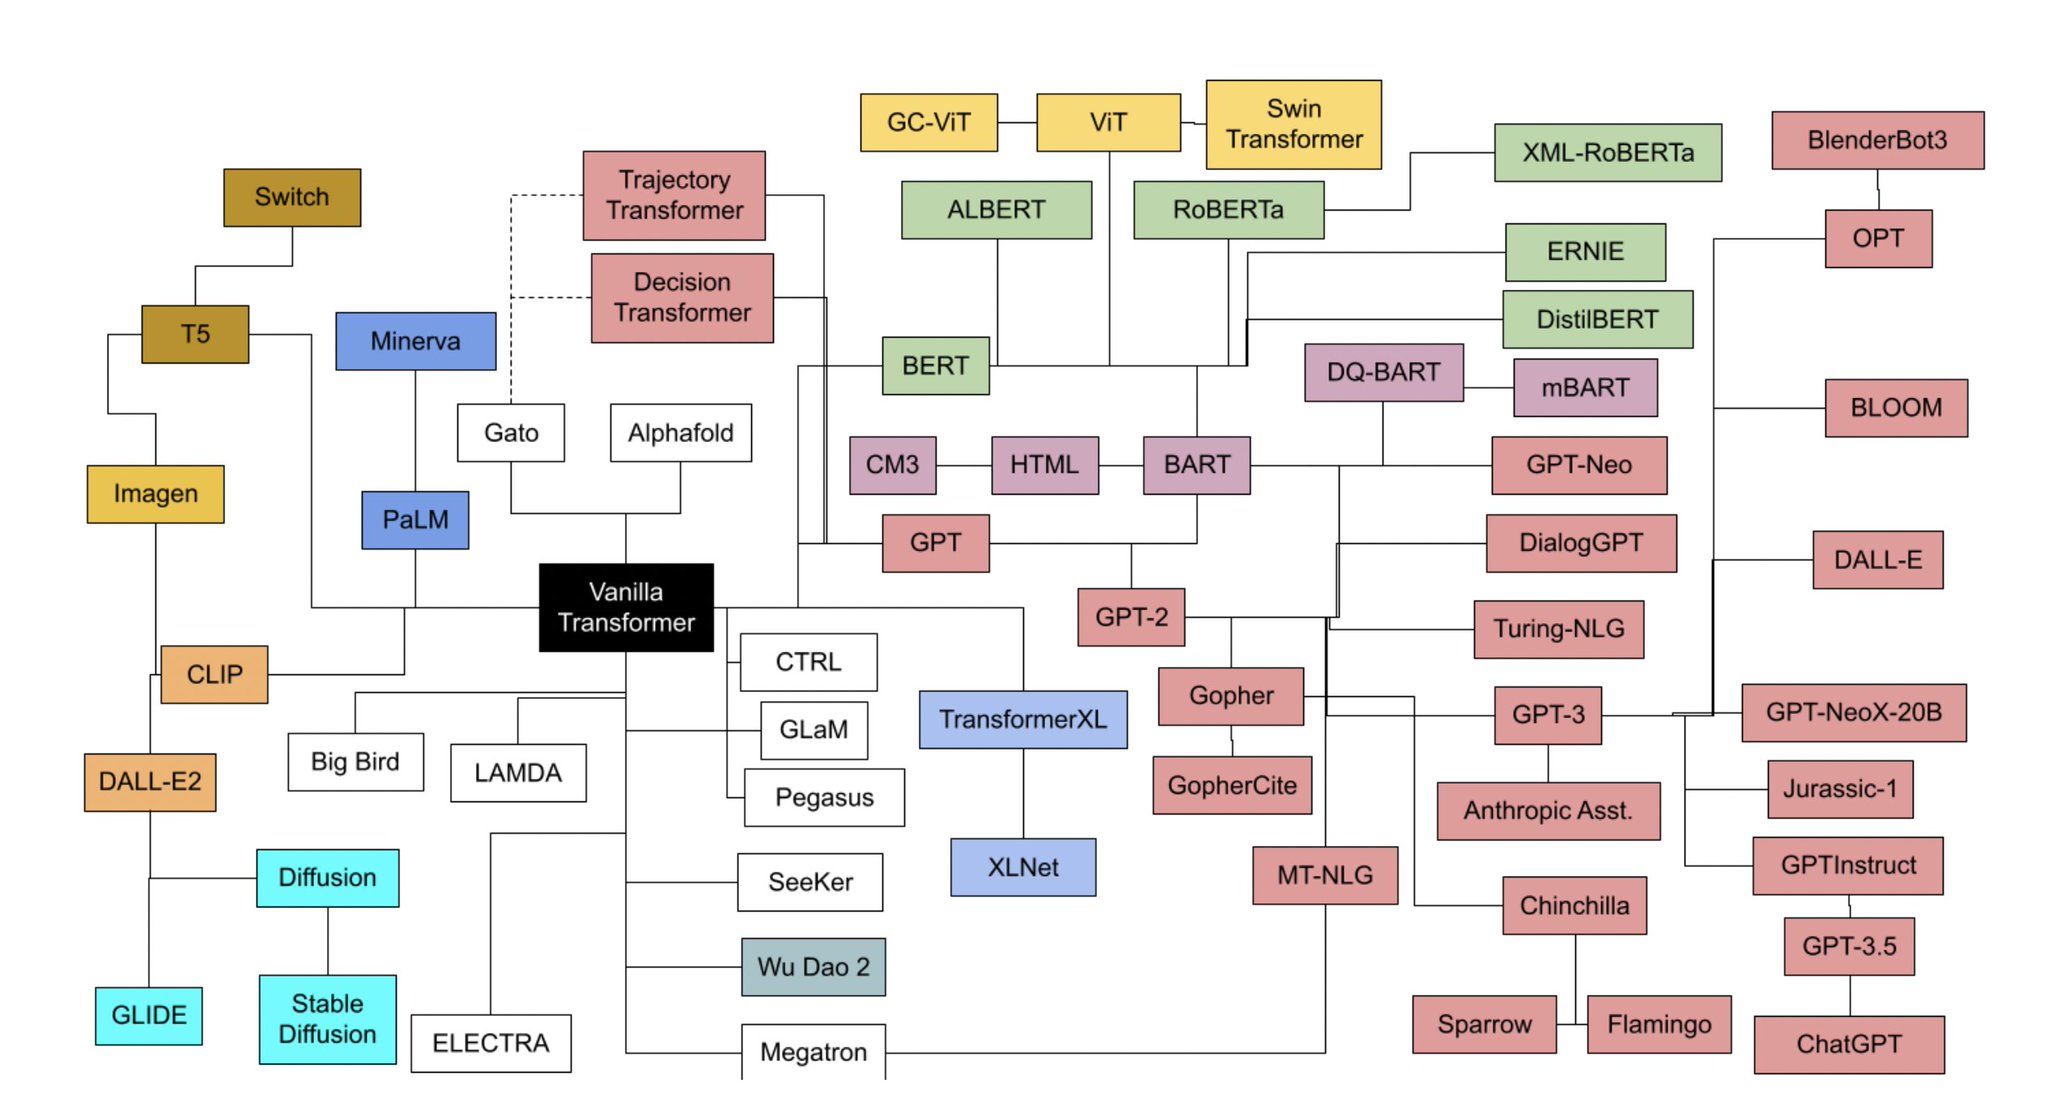
A beautiful "family tree" of large Transformer models from Vaswani et al's 2017 design So cool to see the lineages from GPT, BERT, T5, and PaLM develop and Diffusion models starting from a different place but converging with CLIP and ViT.
MACHINE LEARNING
-
GenAug: Meta’s AI System for Zero-Shot Robot Behavior Transfer
By
–
Introducing GenAug, a new system by Meta AI researchers that uses text2image models to enable robots to transfer behaviors zero-shot from a simple demonstrated scene to unseen scenes of varying complexity — at no extra robot/human cost.
— AI at Meta (@AIatMeta) 16 février 2023
More details ➡️ https://t.co/GOEWtyg5TS pic.twitter.com/Ar8hwdTUOQIntroducing GenAug, a new system by Meta AI researchers that uses text2image models to enable robots to transfer behaviors zero-shot from a simple demonstrated scene to unseen scenes of varying complexity — at no extra robot/human cost. More details https://
bit.ly/3Kc1RiS -
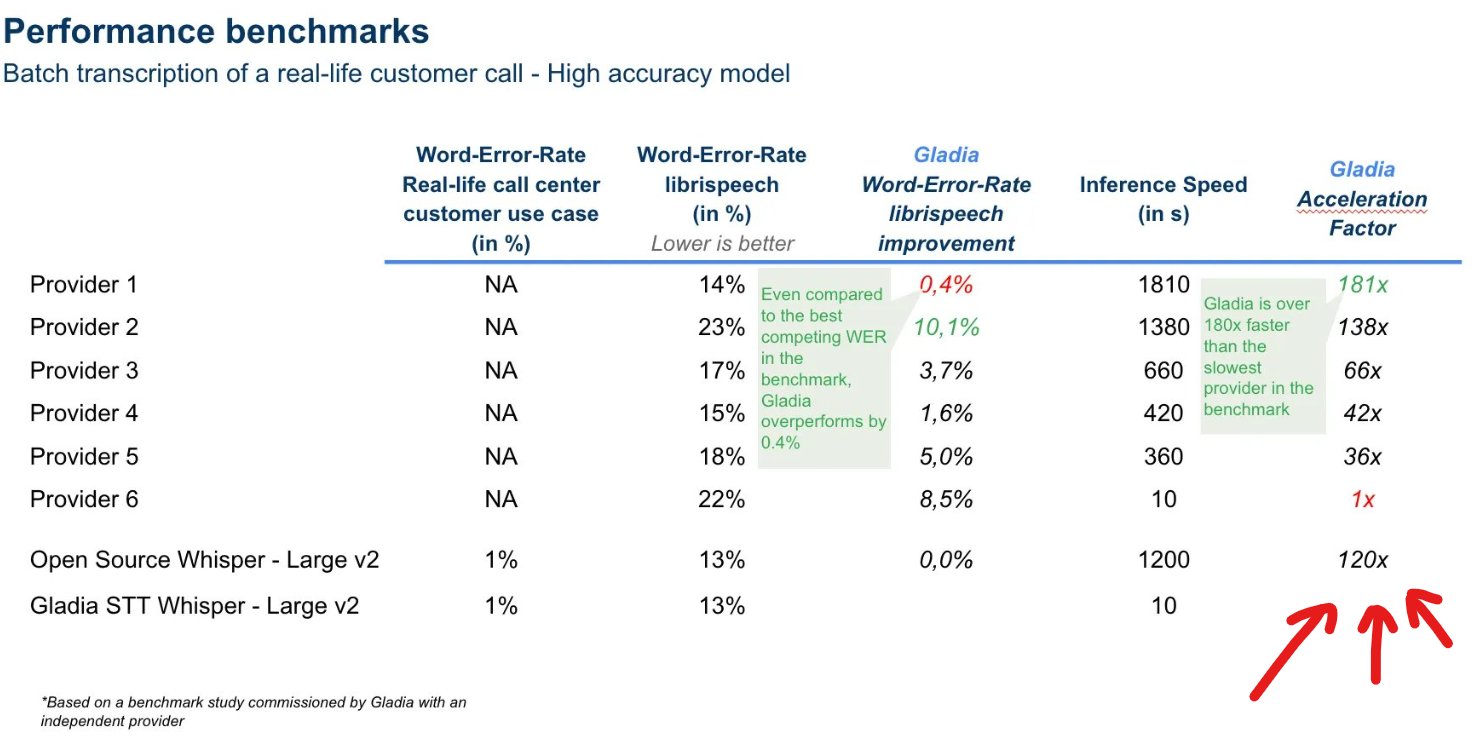
Whisper Normal Version Performance Comparison Analysis
By
–
Según esta tabla de aquí, la versión normal de Whisper tardaría 120 veces más…
-
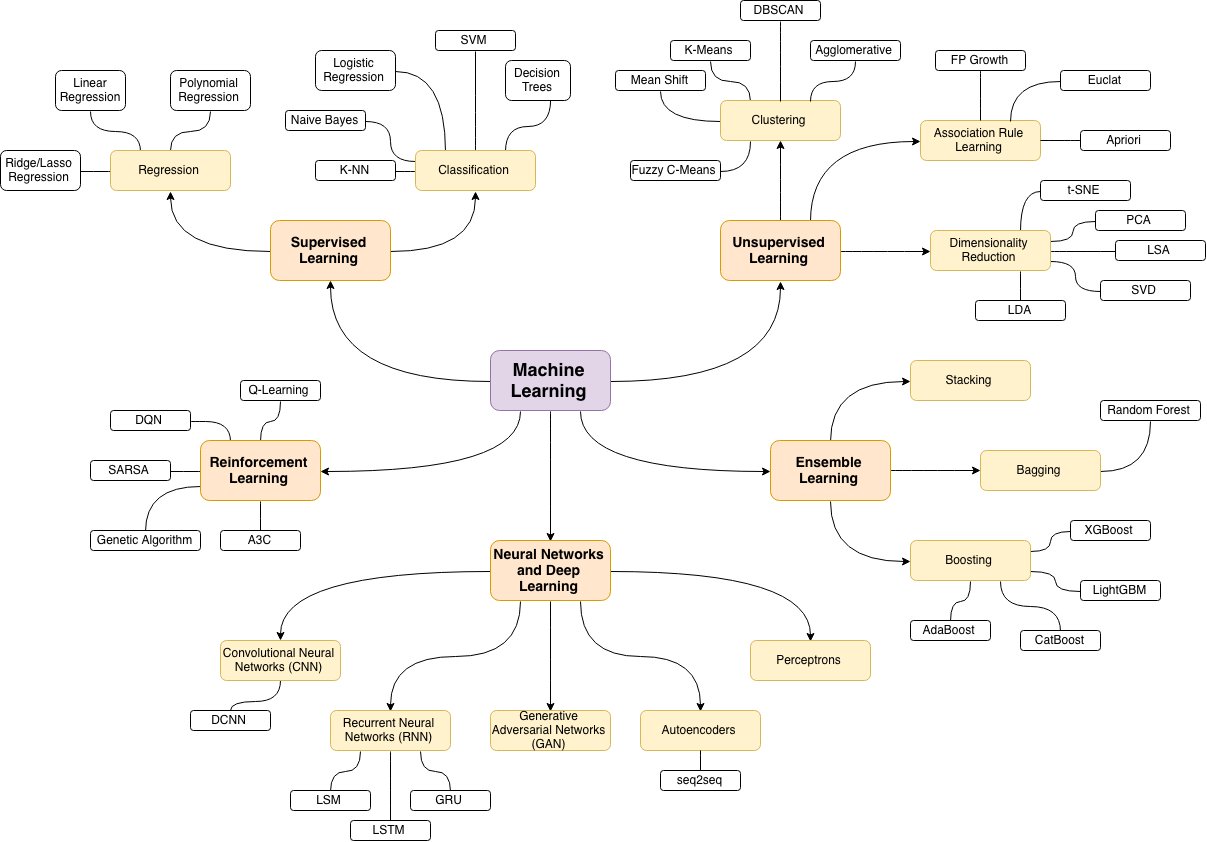
Machine Learning Resource Map Guide
By
–
A map for your machine learning needs: http://
bit.ly/3lEZkj4 -
Large Language Models RLHF Ethics Natural Language Principles
By
–
This work and CAI both observe the same basic phenomenon: if language models are sufficiently large and we add enough RLHF to make them helpful, we can more effectively get them to abide by high-level ethical principles expressed in natural language.
-
RLHF and Prompting Techniques for Targeted Model Behavior
By
–
This means that if we have a target behavior (e.g. non-discrimination) we may be able to nudge models to achieve that target using IF/CoT prompting if RLHF alone is not sufficient. But we must be careful to check whether RLHF + prompting causes the models to overshoot the target.
-
Language Models Show Demographic Bias Tradeoffs in Decision Making
By
–
Prompting models to avoid making decisions based on race achieves demographic parity at steps 300 (CoT) and 600 (IF) but causes the model to start to discriminate against white students at higher steps. (Note that we do not claim LMs should be used for automated decision making!)
-
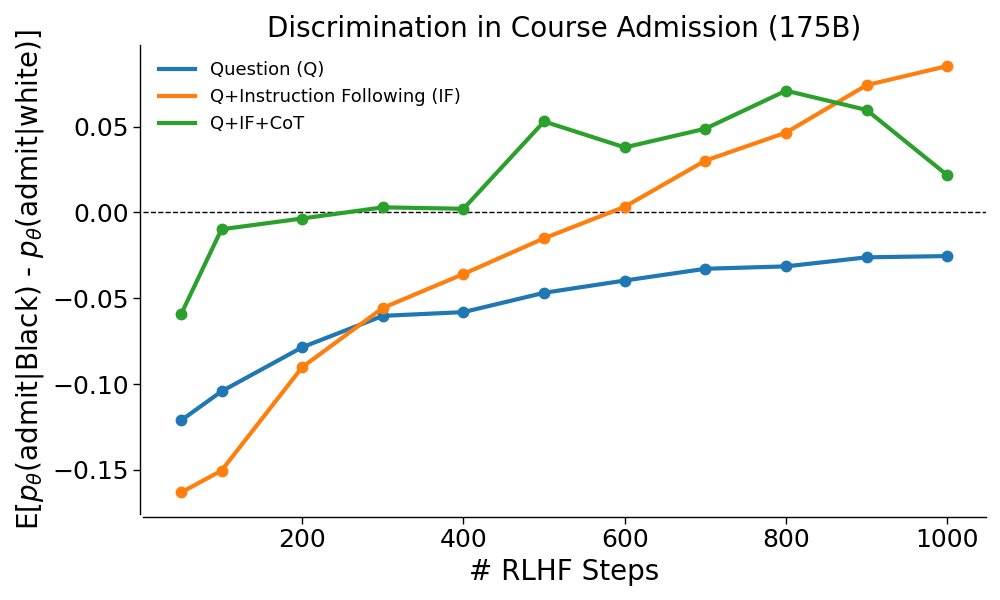
RLHF Training Reduces but Doesn’t Eliminate Racial Discrimination in Admissions
By
–
Finally, we develop a benchmark testing for racial discrimination in LM decision-making in student course admissions. In our control condition (blue) we find more RLHF training produces model outputs that approach demographic parity but still discriminates against Black students.
-
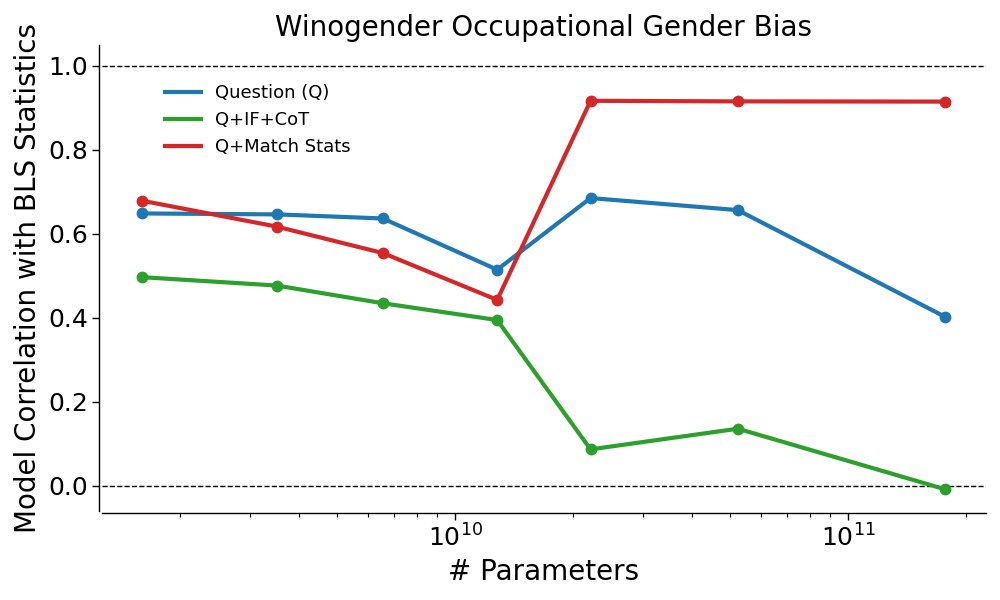
Steering Language Models Away From Gender Stereotypes in Occupations
By
–
We look at the Winogender benchmark and show we can steer larger models towards two different goals: to output pronouns that are correlated with occupational gender statistics from the U.S. Bureau of Labor Statistics (red) or to move away from using stereotypical pronouns (green)
-
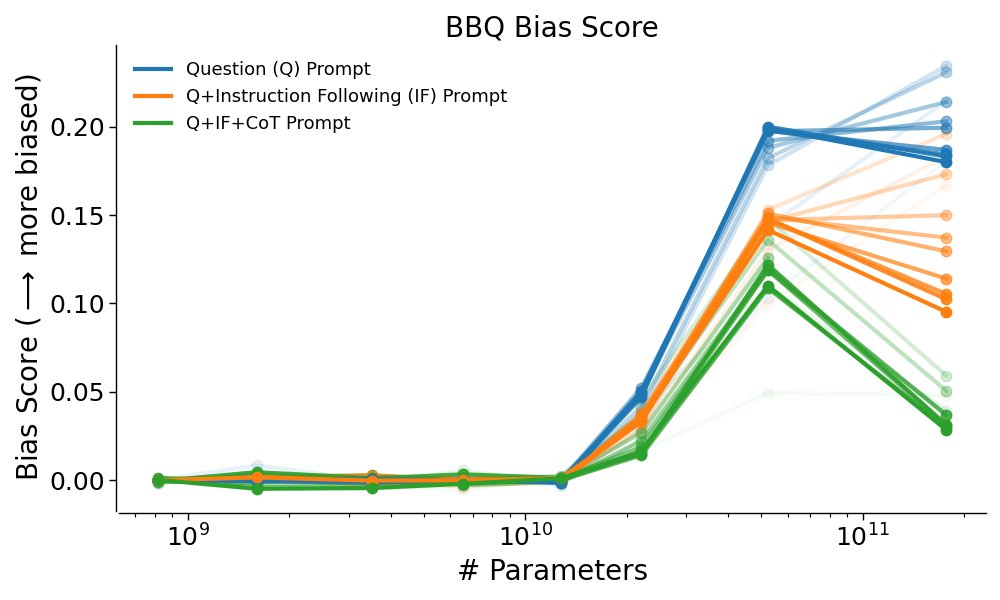
Larger Language Models Show More Bias on BBQ Benchmark
By
–
First, we find larger LMs are more biased on the BBQ benchmark. Prompting models to avoid bias by giving them instructions (IF) and asking for reasoning (CoT) reverses the trend but only for the largest models and only with enough RLHF training! (Darker lines = more RLHF)