Knowledge Distillation of Large Language Models paper page: https://
huggingface.co/papers/2306.08
543
… Knowledge Distillation (KD) is a promising technique for reducing the high computational demand of large language models (LLMs). However, previous KD methods are primarily applied to white-box
MACHINE LEARNING
-
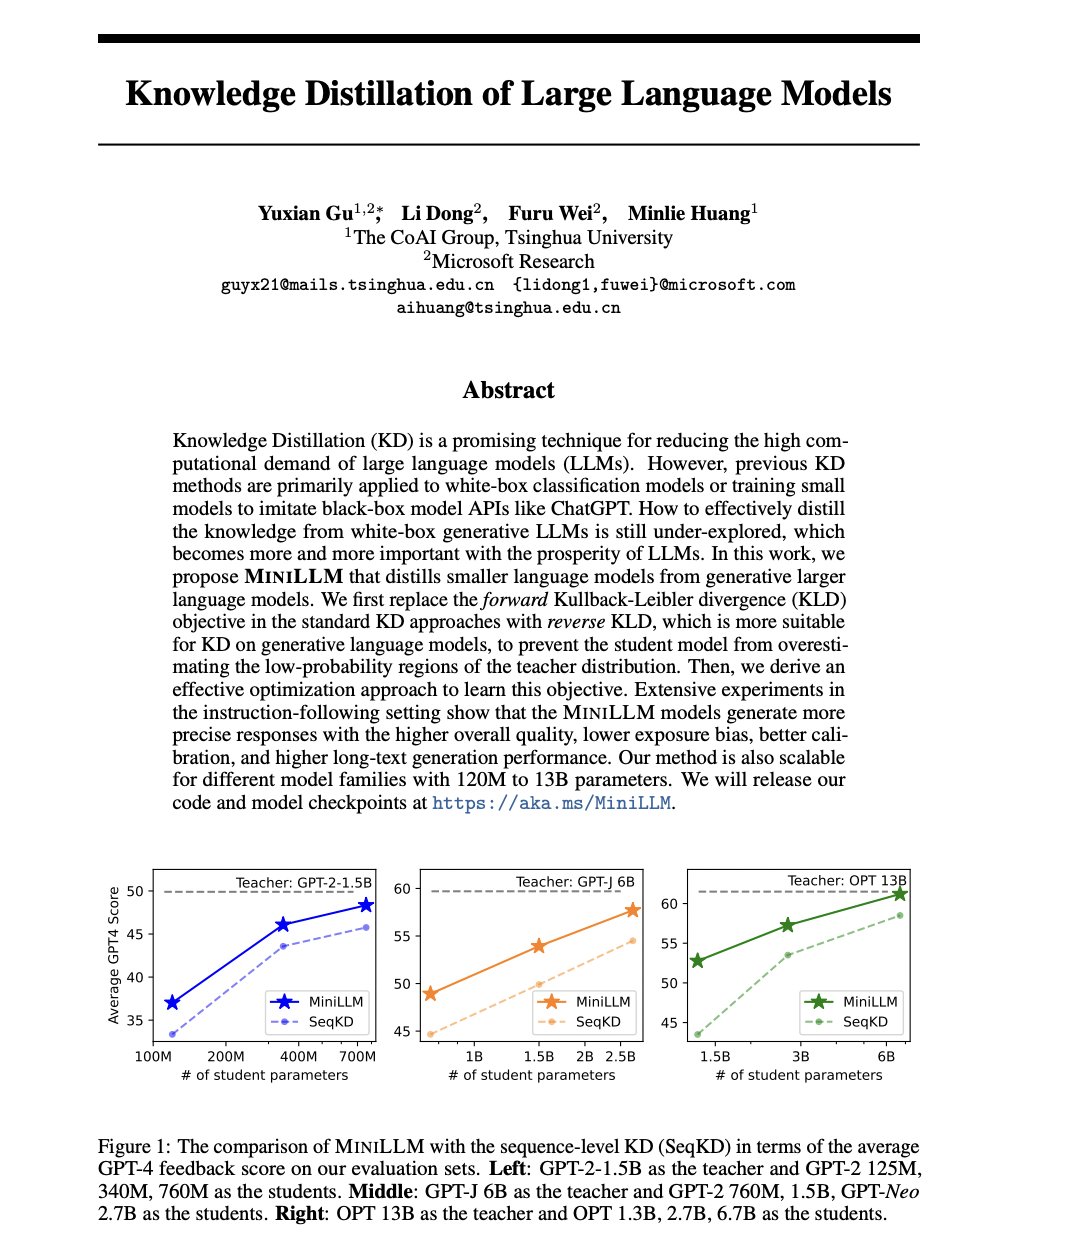
Knowledge Distillation Techniques for Large Language Models
By
–
-
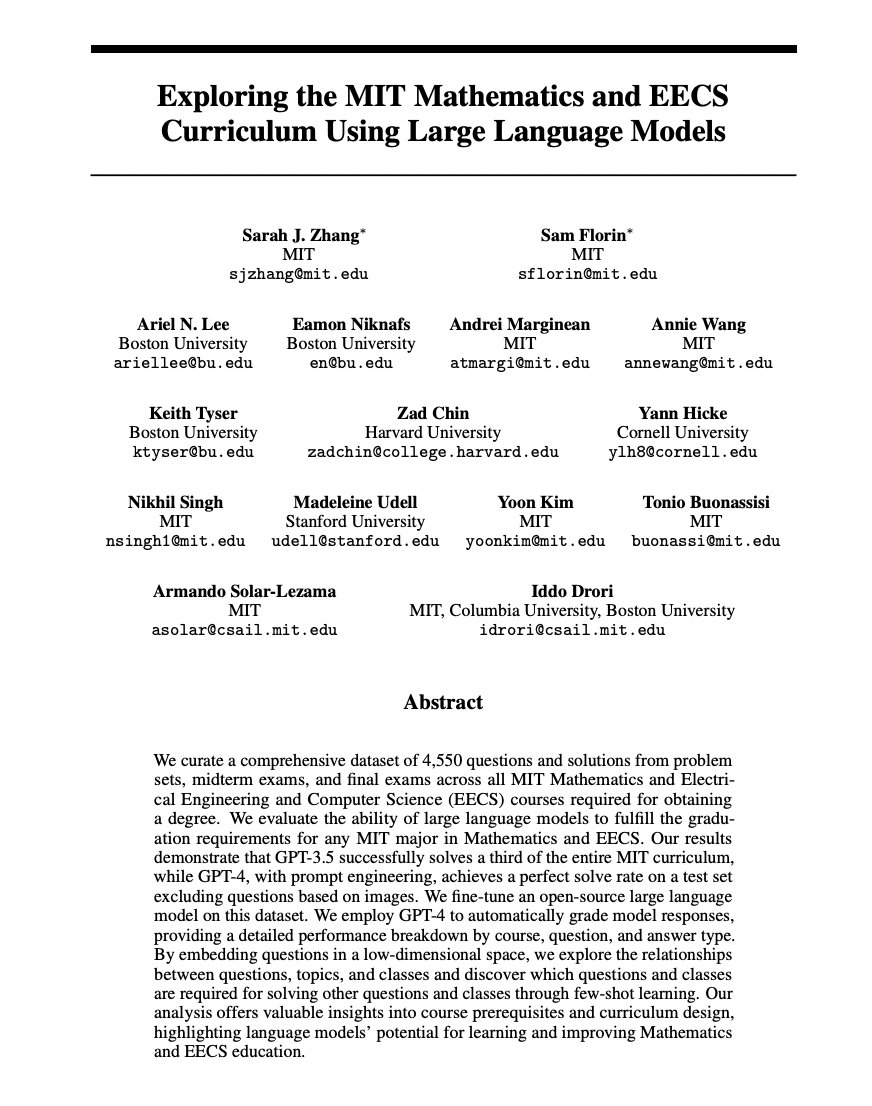
MIT Mathematics EECS Curriculum Analysis Using Large Language Models
By
–
Exploring the MIT Mathematics and EECS Curriculum Using Large Language Models paper page: https://
huggingface.co/papers/2306.08
997
… curate a comprehensive dataset of 4,550 questions and solutions from problem sets, midterm exams, and final exams across all MIT Mathematics and Electrical -
MammalNet: Large-scale Video Benchmark for Mammal Recognition and Behavior
By
–
MammalNet: A Large-scale Video Benchmark for Mammal Recognition and Behavior Understanding
— AK (@_akhaliq) 16 juin 2023
paper page: https://t.co/KFAUDnDlQO
Monitoring animal behavior can facilitate conservation efforts by providing key insights into wildlife health, population status, and ecosystem… pic.twitter.com/mkICOkdzDgMammalNet: A Large-scale Benchmark for Mammal Recognition and Behavior Understanding paper page: https://
huggingface.co/papers/2306.00
576
… Monitoring animal behavior can facilitate conservation efforts by providing key insights into wildlife health, population status, and ecosystem -
Custom LLMs Essential for Specialized Domain Applications
By
–
If you want to develop/use a generalist chatbot, I totally agree. But there are countless problems where a custom LLM makes 100% sense. From spam classification to working with financial, law or medical data to protein sequence modeling.
-

Design Effective AI Prompts with Microsoft Prompt Engine
By
–
Design effective AI prompts with Microsoft Prompt Engine
#AI #AIio #BigData #ML #NLU #Futureofwork @TopCyberNews @SpirosMargaris @MarshaCollier @MHiesboeck
@MHcommunicate @Fisher85M @MikeQuindazzi @NealSchaffer
http://
ow.ly/xr8v30svHU8 -
Batch Size Analogy for Precision Selection in Hardware
By
–
It makes sense though since it’s kind of like batch size: make it as large as your hardware permits (… < bfloat 16 < bfloat 16/32 mixed < float 32)
-

AI Research Dinner Explores Embodied Intelligence and Multi-Agent Systems
By
–
Just wrapped up a heavy-hitting AI research dinner in London w/
@Sethwinterroth @EclipseVentures x @airstreet
. What a time to be in AI, whether it’s embodied intelligence that teaches cars to drive, learning quantum chemistry, multi-agent system collaboration, semiconductors, -
Clarification on supervised instruction-finetuning versus RLHF methods
By
–
Btw. was supervised instruction-finetuning vs RLHF instruction-finetuning what you had in mind, or were you more curious about supervised finetuning as in classification vs supervised instruction-finetuning?
-
Instruction-Finetuning vs RLHF: Inconclusive Research Findings
By
–
Thanks! Right now, it's a bit inconclusive. Lots of papers show that supervised instruction-finetuning is sufficient (vs RLHF instruction-finetuning). (I cannot put my finger on it, but I feel like we don't have good evaluations, yet, and this is not the end of the story.)
-
Machine Learning Engineering: Curiosity-Driven Debugging and Performance Optimization
By
–
Machine learning engineering rewards a particular kind of curiosity. Progress often requires digging into any surprising numerical discrepancy or slight wiggle in the performance graphs. Makes the job a lot more fun if you view those explorations as exciting rather than tedious.