Synthetic data is a broad term. I think the paper looks at a very extreme case. One can blindly generate synthetic data by sampling from an upstream model. But yeah, I can see how being more strategic than that can actually be beneficial.
MACHINE LEARNING
-
Questioning the Curse of Recursion Paper’s Future Relevance
By
–
For more context, since I didn't see a link in the article, are we talking about the "The Curse of Recursion: Training on Generated Data Makes Models Forget" paper? (
https://
arxiv.org/abs/2305.17493) And the claim is that the findings in this paper don't / won't hold in the future? -
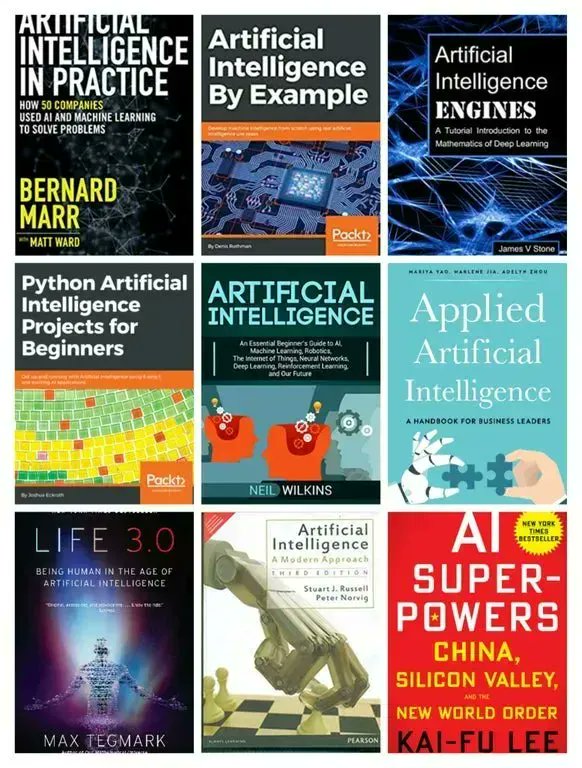
Essential Books on Artificial Intelligence for Data Science Professionals
By
–
A List of Must Read Books on Artificial Intelligence! By @gp_pulipaka Via @ingliguori #BigData #Analytics #DataScience #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode
-
FastSpeech2 Vocoder Inference Debugging: Tensor Dimension Error
By
–
Running inference on an assortment of FastSpeech2 variants with a new vocoder.. after 3 hours of sifting through the stack trace, realised that I forgot to `unsqueeze` my input vector! *cries in torch*
-
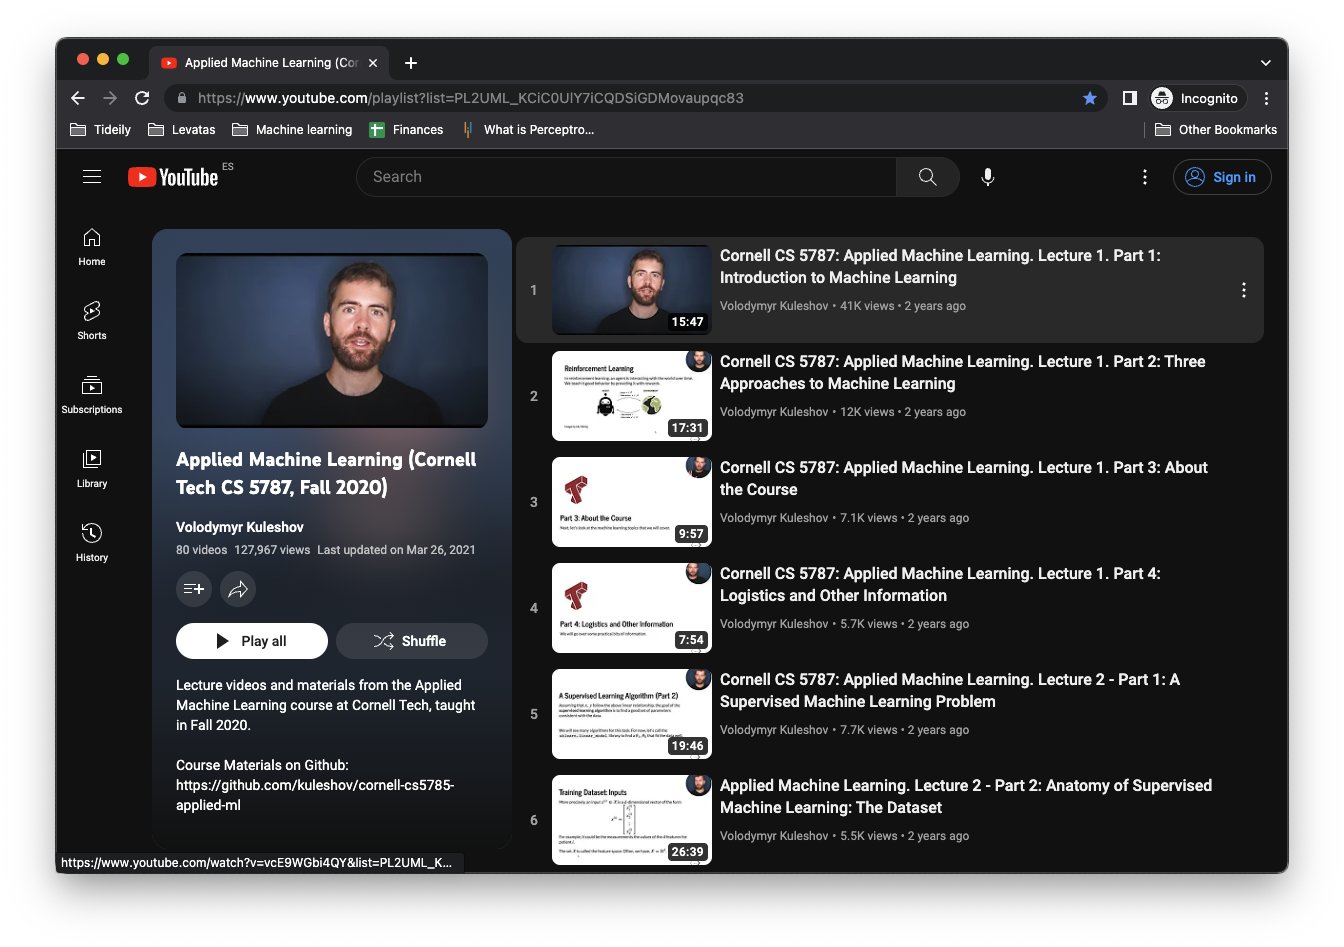
Applied Machine Learning Course Available Free on YouTube
By
–
"Applied Machine Learning" is available to stream on YouTube. From Cornell Tech and 100% free. There are 80 videos of content! Full playlist: https://
youtube.com/playlist?list=
PL2UML_KCiC0UlY7iCQDSiGDMovaupqc83
… Make sure you follow @abacusai
. There's a lot more coming! -
Essential Unsupervised Learning Concepts Explained
By
–
Check out the detailed blog using the link below and make sure you follow on Medium to stay updated https://
medium.com/@avikumart_/mu
st-know-concepts-of-an-unsupervised-learning-9362bbe2e01a
… -
K-means Limitations with Non-linear and Categorical Data
By
–
5/
The k-means algorithm is not suitable for non-linear datasets with categorical features. It assumes the dataset to be linear and a non-linear dataset can result in incorrect clusters in the dataset. -
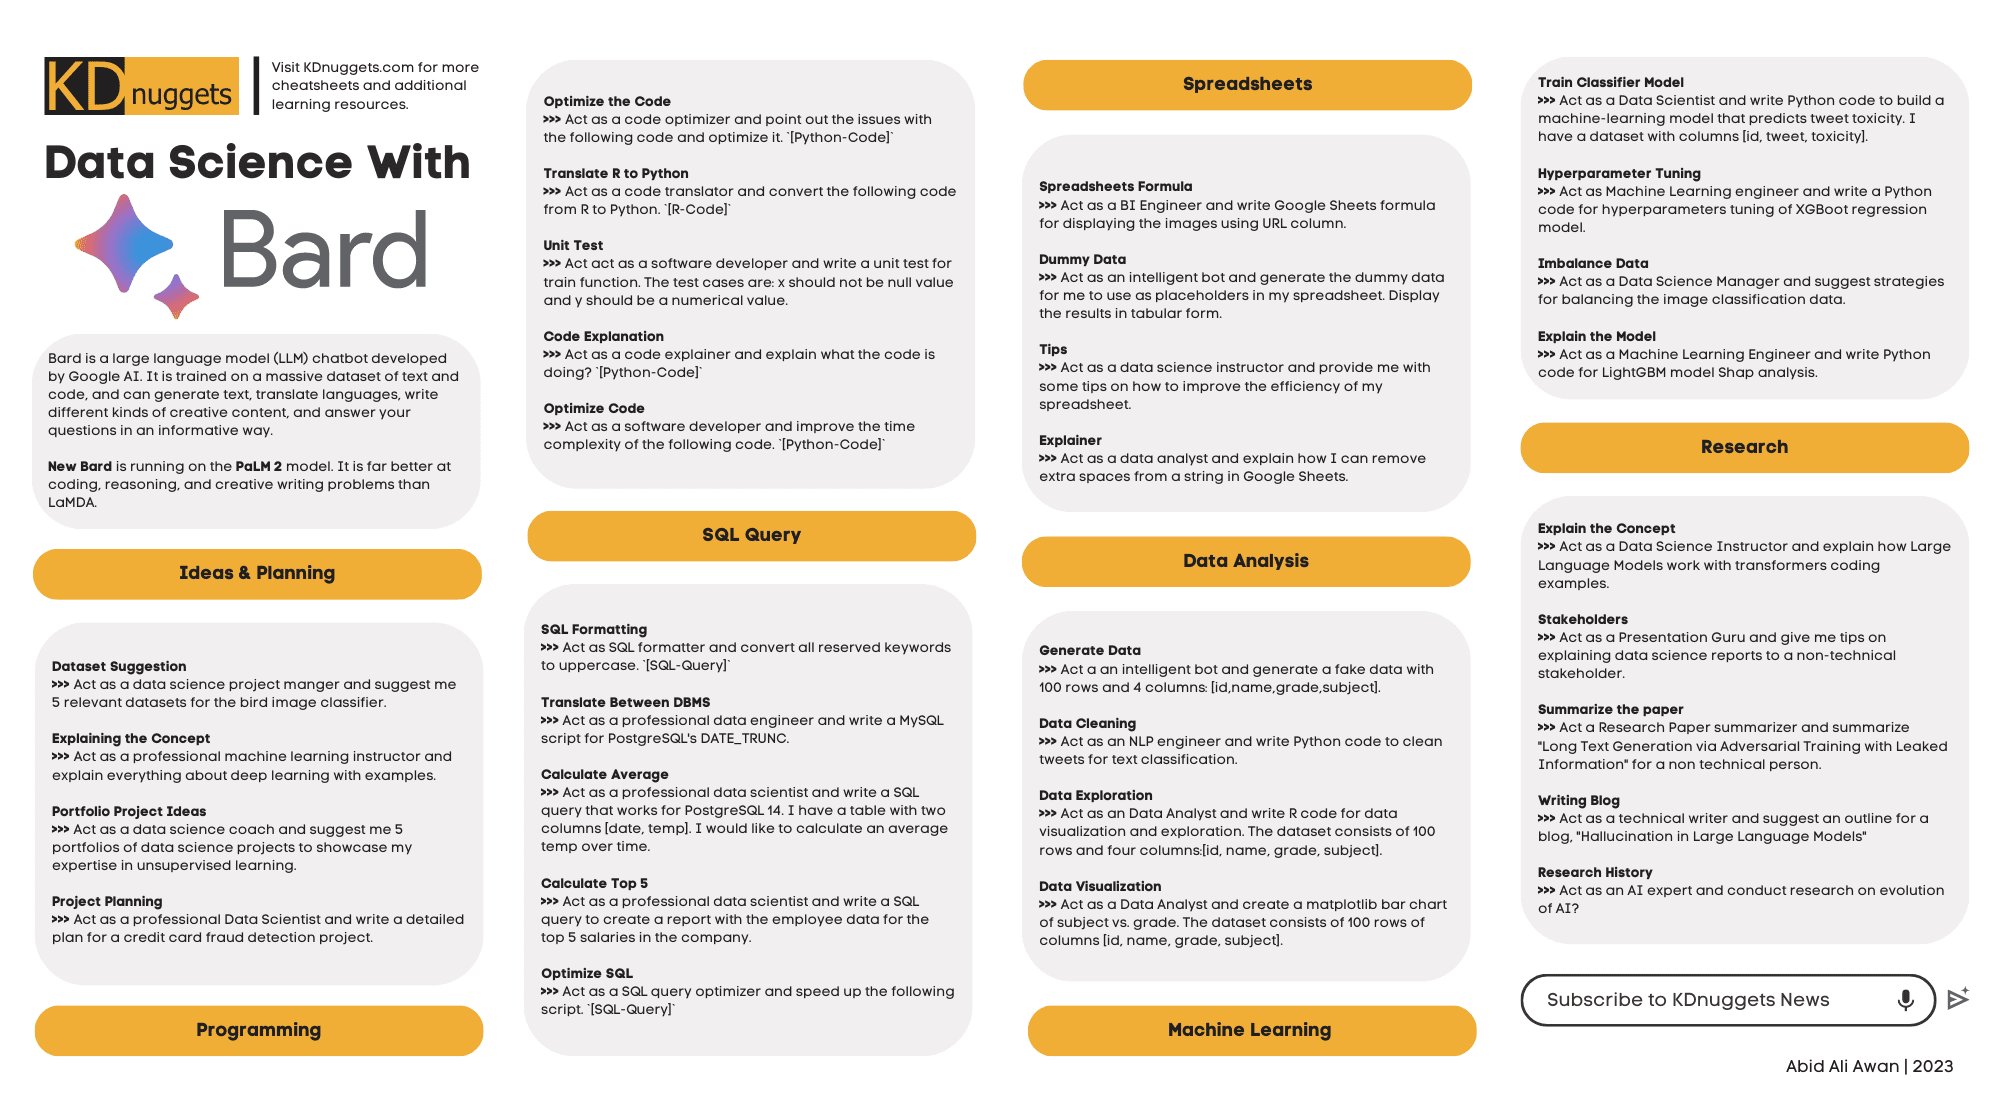
Bard for Data Science: Complete Cheat Sheet Guide
By
–
Bard for Data Science Cheat Sheet: Check out our latest cheat sheet to get you up to speed and provide a handy reference for using Google's LLM chat tool Bard for data science. https://
kdnuggets.com/2023/05/bard-d
ata-science-cheat-sheet.html?utm_source=dlvr.it&utm_medium=twitter&utm_campaign=bard-for-data-science-cheat-sheet
… -
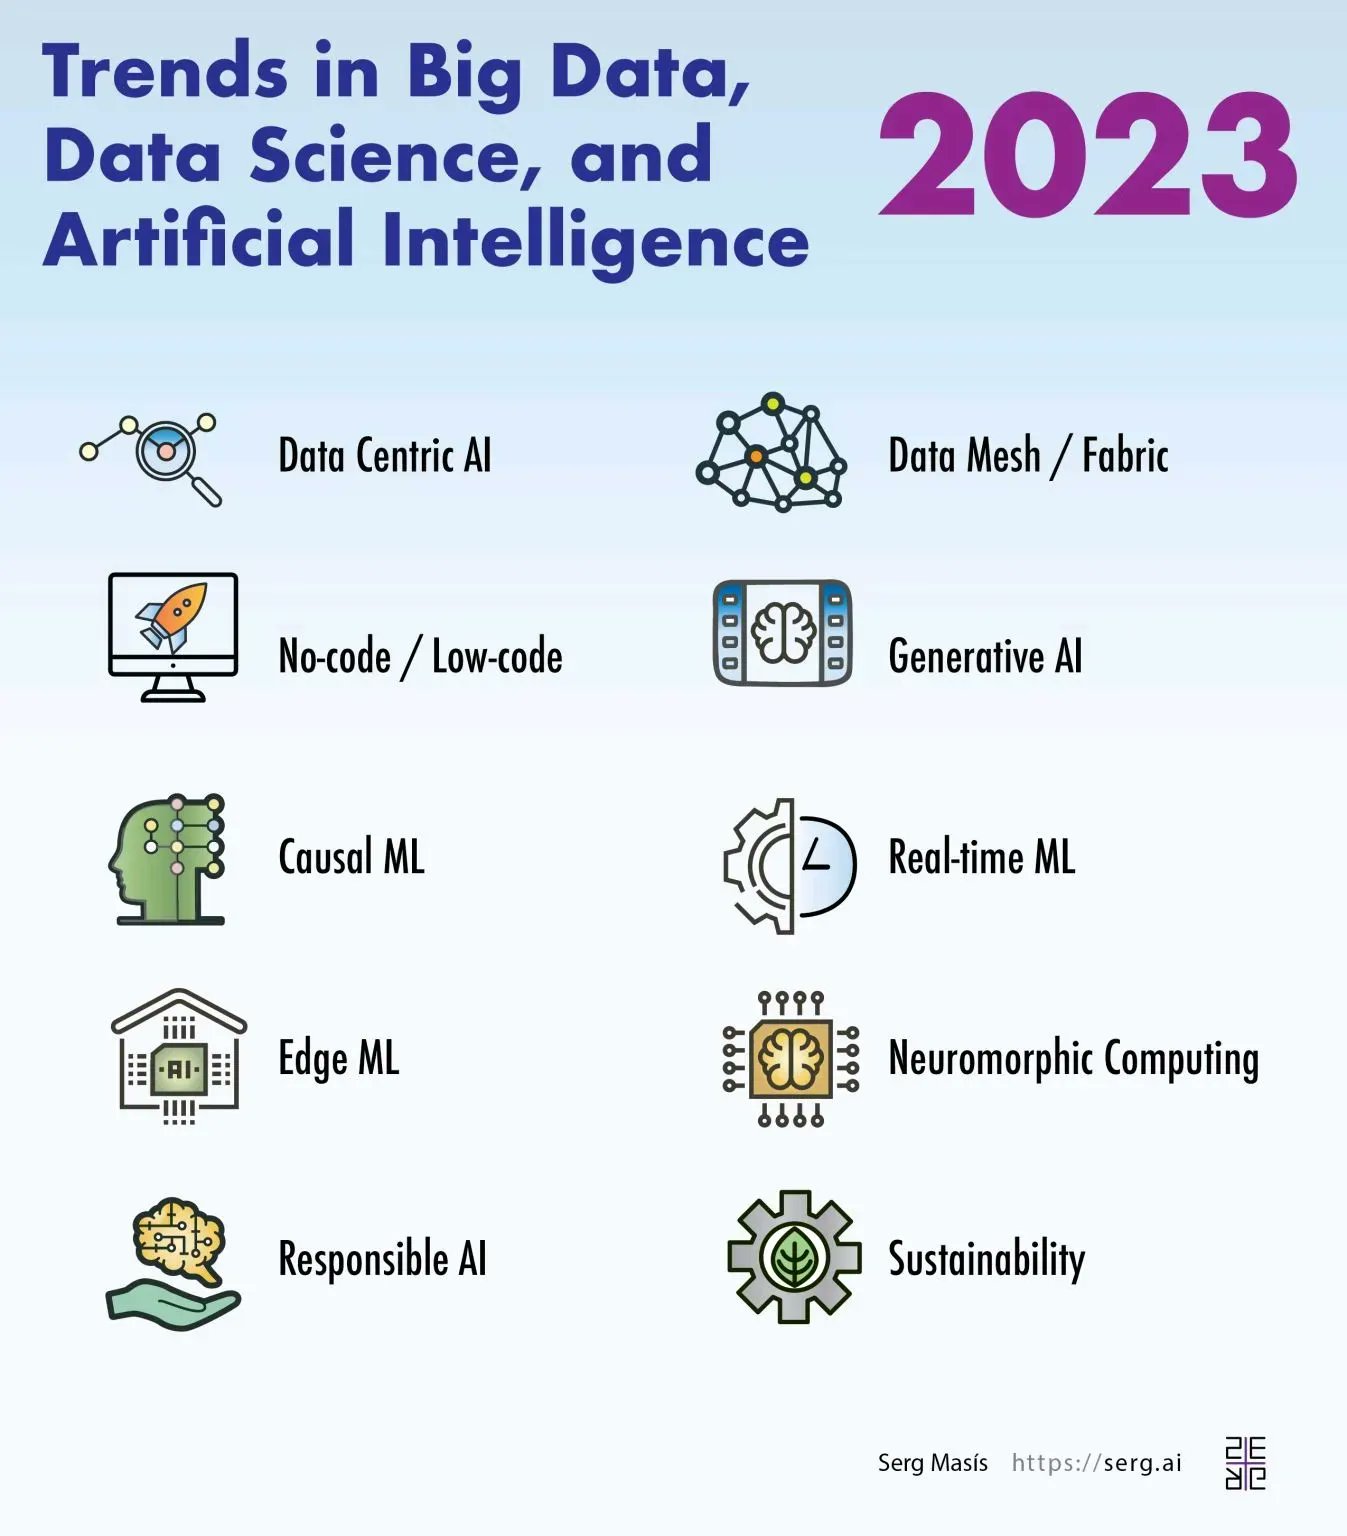
Big Data, Data Science, and Artificial Intelligence Trends 2023
By
–
Trends 2023 in #BigData, #DataScience and #ArtificalIntelligence
By @smasis Via @ingliguori #Analytics #AI #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #JavaScript #ReactJS #CloudComputing #DevCommunity #Serverless #DataScientist #DigitalTransformation #Cloud #MachineLearning -

Open-source LLMs extended context length with minimal quality degradation
By
–
What a pleasure to see the open-source and academic community at full speed on pushing smart ways to do long context with pretrained LLM Check this thread and amazing work. Pushing LLaMA up to 8k context and more with negligible degradation in quality