Improving Language Plasticity via Pretraining with Active Forgetting paper page: https://
huggingface.co/papers/2307.01
163
… Pretrained language models (PLMs) are today the primary model for natural language processing. Despite their impressive downstream performance, it can be difficult to apply
MACHINE LEARNING
-
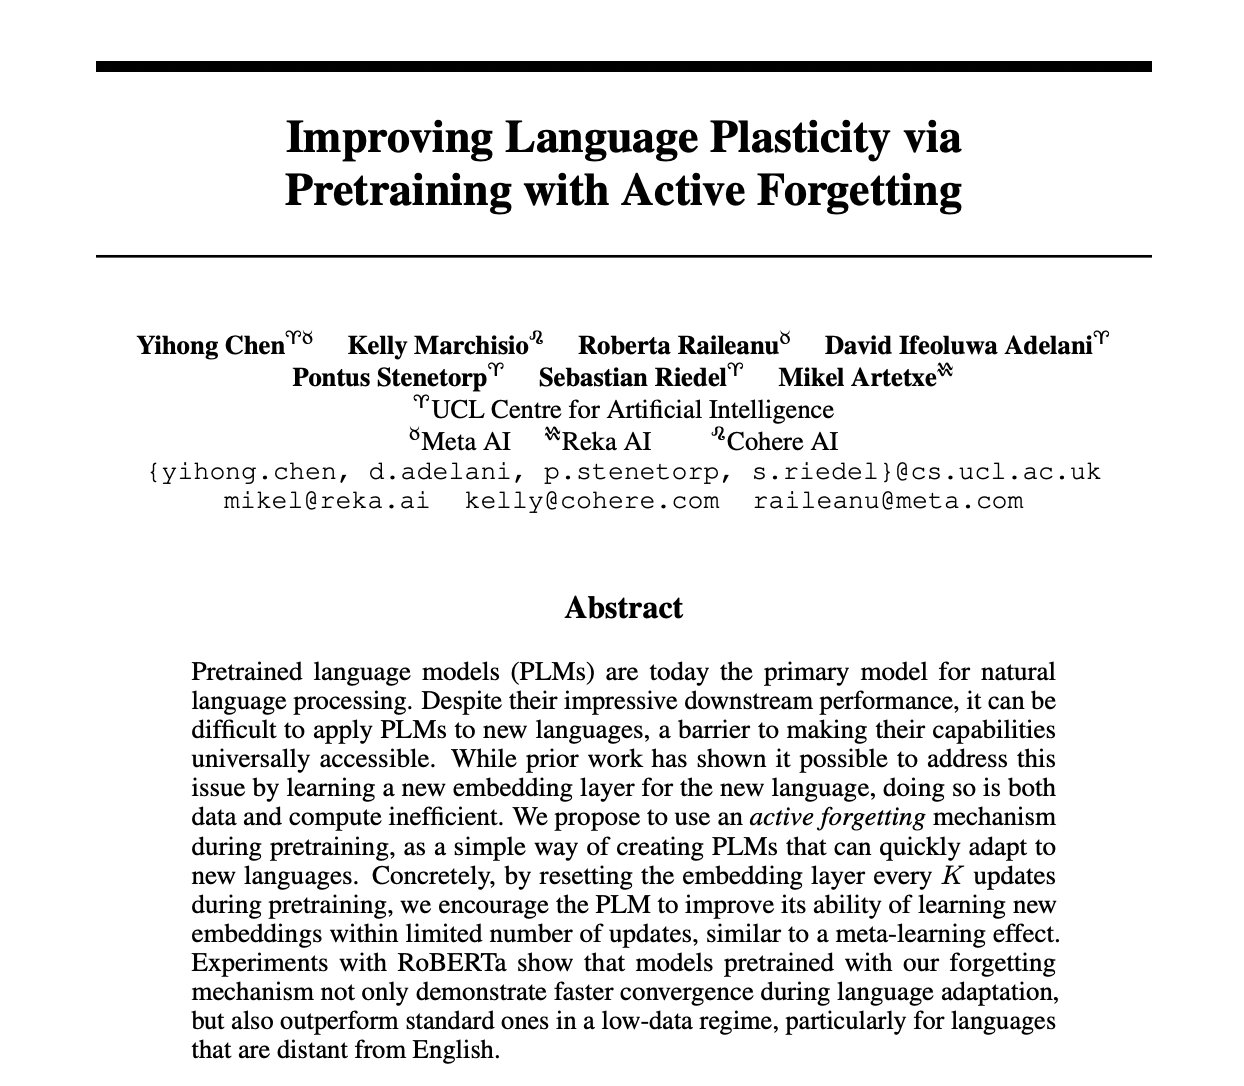
Improving Language Plasticity via Pretraining with Active Forgetting
By
–
-

Your Guide to AI: June 2023
By
–
Your guide to AI: June 2023 https://
bit.ly/3JfgReE #AI #MachineLearning #DeepLearning #LLMs #DataScience -
Why Transformers and Self-Attention Over Convolutional or RNN Layers
By
–
Sure. But why specifically for transformer layers and self-attention, not say convolutional or RNN layers?
-
Multiquery Attention Challenges with LoRA Porting Between Models
By
–
That’s absolutely true and a good point. I remember multiquery attention struggles when trying to port LoRA from LLaMA to Falcon.
-
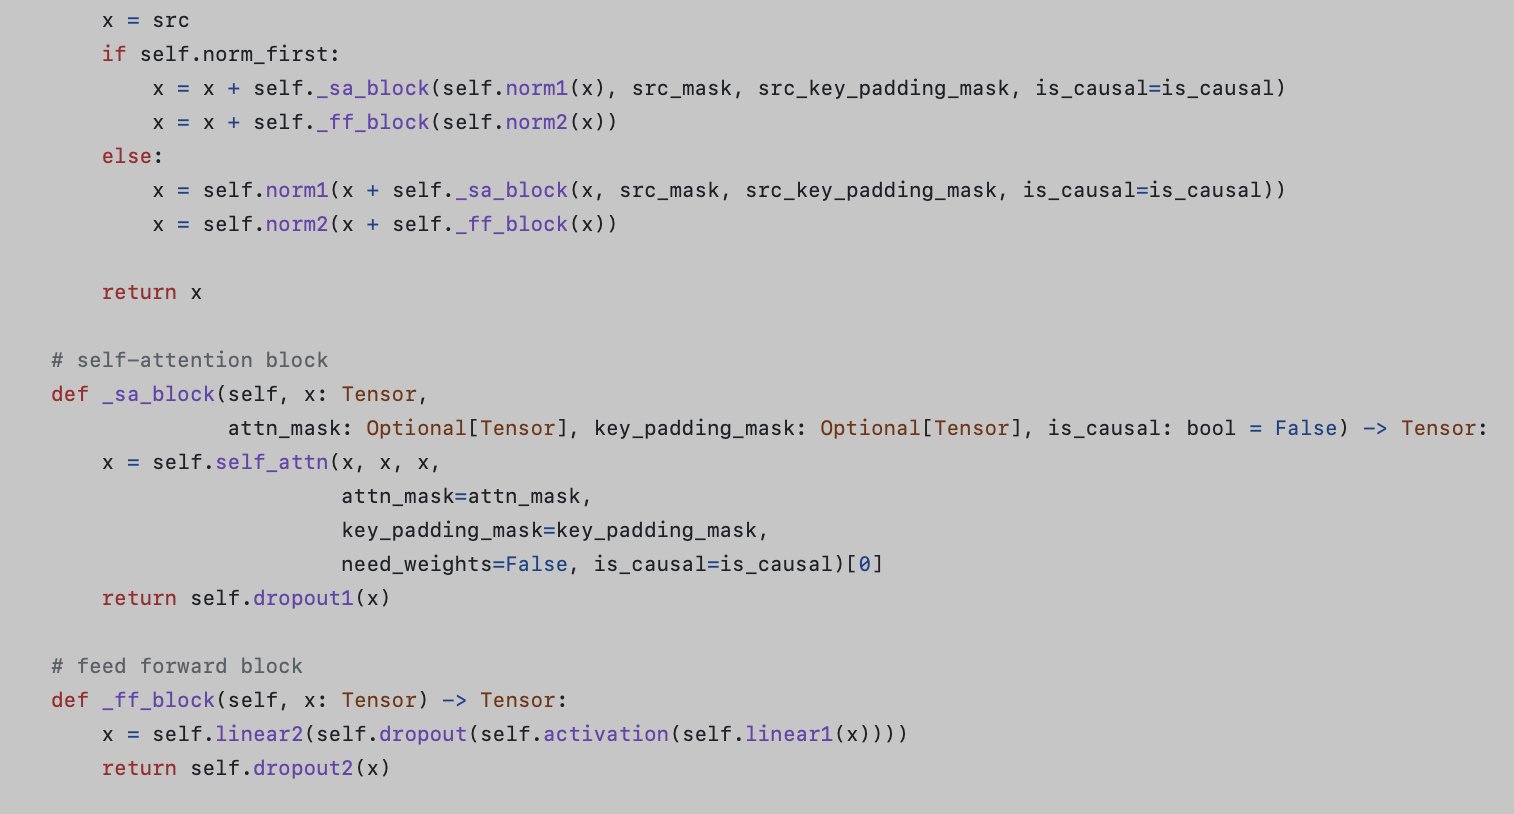
TransformerEncoderLayer Abstraction Compared to Conv2D and RNN
By
–
Ok, fair. But if you look at the TransformerEncoderLayer class, for example, I don't think it's more abstract than nn.Conv2D or nn.RNN, for example. For some reason people just like implementing Transformer layers from scratch way more than convolutional or recurrent layers .
-
Everyone’s Using nn.Linear and Similar Neural Network Layers
By
–
But everyone's using nn.Linear etc.
-
PyTorch Transformer Classes Predate Most Online Tutorials
By
–
Interesting! I'd say the nn.TransformerEncoderLayer and nn.TransformerDecoderLayer classes etc. actually precede most tutorials out there. Chicken-egg problem maybe
-
Quadratic AI Training Costs: How Engineers Build Bigger Models Affordably
By
–
Did you know that the cost of training an AI model increases approximately quadratically as you increase the number of tokens and the model size? ML engineers are still building bigger models without breaking the bank. pic.twitter.com/tB7EiintQl
— Replit ⠕ (@Replit) 3 juillet 2023Did you know that the cost of training an AI model increases approximately quadratically as you increase the number of tokens and the model size? ML engineers are still building bigger models without breaking the bank.
-
Using nn.Linear and nanoGPT for Educational Implementation
By
–
Given that you are using nn.Linear, also looking at nanoGPT . (Although here, I guess the reimplementation serves educational purposes)
-
Why Do Developers Avoid PyTorch’s Built-in Transformer Layers?
By
–
Yeah, I always wonder what's up with that. The various Transformer layers in PyTorch have been around since ~2020, but everyone seems to be (still) rolling their own, https://
pytorch.org/docs/stable/nn
.html#transformer-layers
… Are the implementations somehow bad or inefficient? Genuine question.