Thanks for writing & sharing your latest article on MPT. Really well written and has just the right level of detail .
One question though. You wrote > "The entire training framework is based upon PyTorch’s Fully Sharded Data Parallel (FSDP) package and uses no pipeline or
MACHINE LEARNING
-
Appreciation for MPT Article and FSDP Implementation Question
By
–
-
OpenFlamingo v2: Advanced Multimodal Models Released
By
–
Research blog post: OpenFlamingo v2: Next-level models and enhanced training setup! The paper by @anas_awadalla and @irena_gao
, with compute support from Stability AI, details five trained OpenFlamingo models across the 3B, 4B, and 9B scales. #StabilityAI Read more: -
India’s AI Strategy: Government and Tech Leaders Collaborate
By
–
@WHO @_DigitalIndia @GoI_MeitY @nasscom @NeGD_GoI #ai #AImodel #MachineLearning #INDIAai
-
MIT Researchers Develop AI Dataset for Automatic Chart Captioning
By
–
Exciting news from @MIT
! Researchers develop a dataset to improve automatic captioning systems for chart subtitles. By training AI models, they aim to enhance the quality of data visualization. Learn more about the future of online reporting: https://
rb.gy/m21ft -
India’s AI Initiative: Government and Tech Leaders Push ML Development
By
–
@jeevprabnivash @OpenAI @_DigitalIndia @GoI_MeitY @nasscom @NeGD_GoI #ai #AImodel #MachineLearning #INDIAai
-
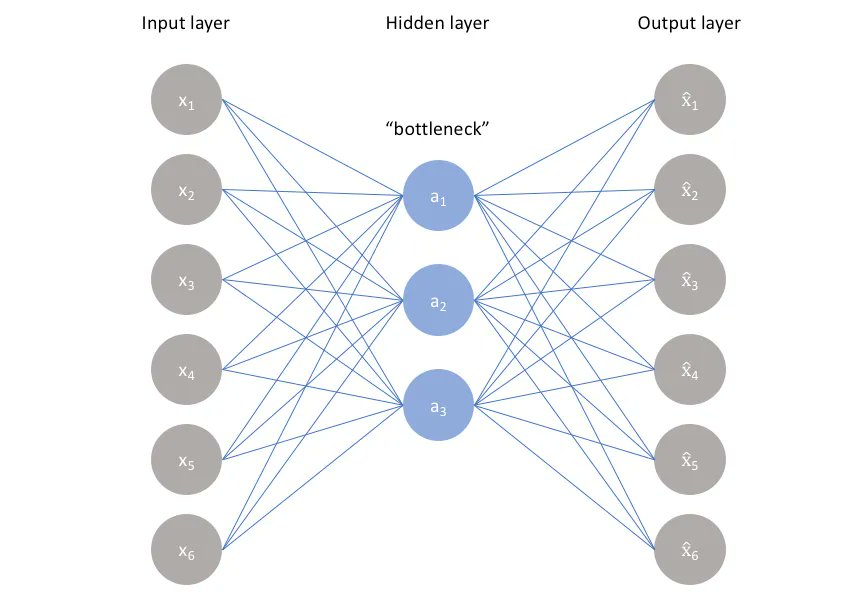
Introduction to Autoencoders in Deep Learning
By
–
Introduction to autoencoders. https://
bit.ly/3oco9su #AI #MachineLearning #DeepLearning #LLMs #DataScience -
AI Tool Enhances Surgeon Performance and Clinical Outcomes
By
–
AI Offers Tool to Improve Surgeon Performance
#AI #AIio #BigData #ML #NLU #Futureofwork http://
ow.ly/EYZ830svSfl -

AI Tool Enhances Surgeon Performance and Clinical Outcomes
By
–
AI Offers Tool to Improve Surgeon Performance
#AI #AIio #BigData #ML #NLU #Futureofwork @TopCyberNews @SpirosMargaris @MarshaCollier @MHiesboeck
@MHcommunicate @Fisher85M @MikeQuindazzi @NealSchaffer
http://
ow.ly/XwWT30svStH -
Beyond Homogeneous Transformers: Loss Functions and Inference Optimization
By
–
i think your position comes from a fundamentally incomplete estimation of the parts of the graph that are not a homogeneous transformer — the loss function, the beam search, things like activation checkpointing that isnt simply autodiff, token fusion style tricks. caffe style