The New “Hybrid Work” is “AI + Humans”
#AI #AIio #BigData #ML #NLU #Futureofwork @Kevin_Jackson @sallyeaves @schmarzo @kdnuggets @akwyz @BrettKing @TechNative @MiaD http://
ow.ly/mw6f30swzJB
MACHINE LEARNING
-
The New Hybrid Work: AI and Humans Collaboration
By
–
-
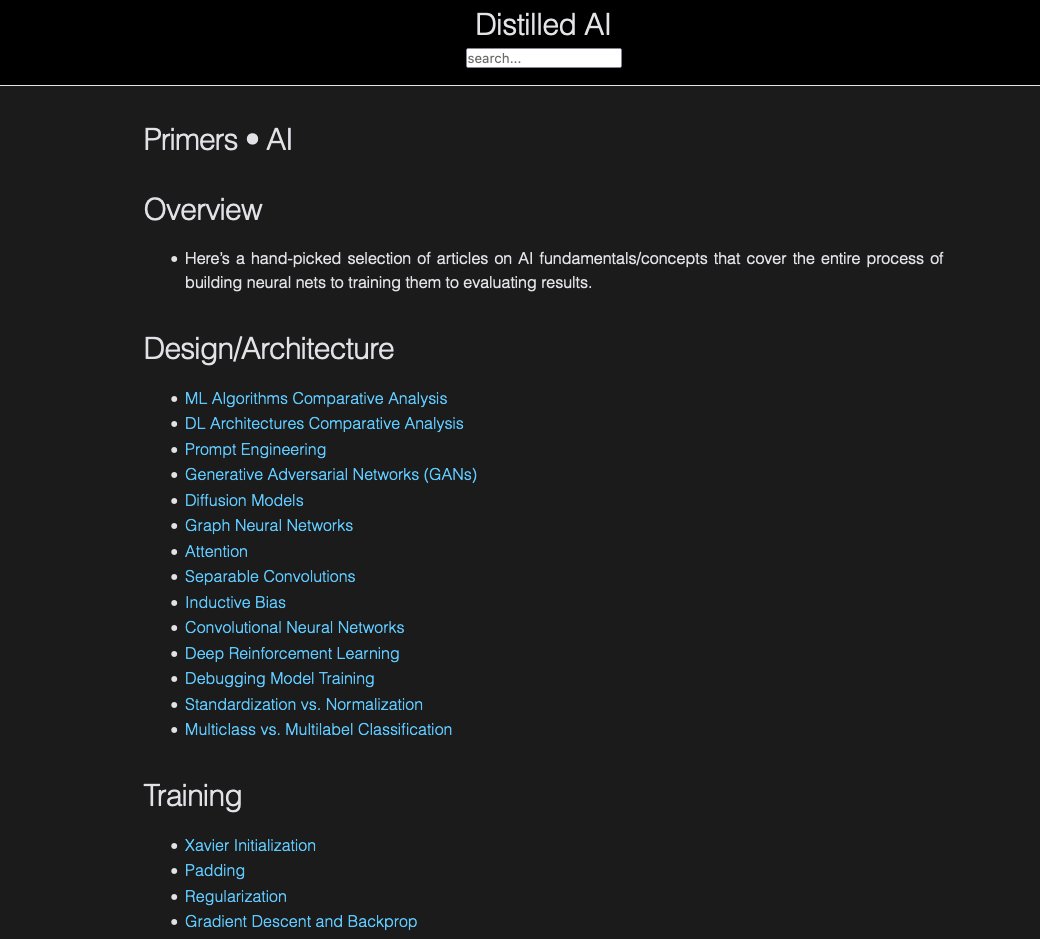
AI Primers and Guides on Diverse Machine Learning Topics
By
–
Really like these primers/guides on nearly any topic you can think of in AI. From model architectures, training techniques, speech, vision, NLP, multimodal, evaluation, etc… https://
aman.ai/primers/ai/ -

Digital Health Startups Transforming Healthcare System Through Innovation
By
–
How Digital Health Startups Can Help Revise The Healthcare System
#AI #AIio #BigData #ML #NLU #Futureofwork @nigelwalsh @pbouillaud @PatrickGunz_CH @pierrepinna @RebekahRadice @Ronald_vanLoon @sbmeunier
@Shirastweet http://
ow.ly/1IBV30swzJz -
AlphaFold Database Celebrates Two Years, 200M Protein Structures
By
–
It's 2 years since we launched the #AlphaFold Protein Structure Database with @emblebi
. Since then we’ve predicted 200M+ protein structures & it's been used by over 1M researchers to advance disease understanding, accelerate drug discovery & much more eg: -

Brain2Music: Reconstructing Music from Human Brain Activity
By
–
Brain2Music: Reconstructing Music from Human Brain Activity https://
bit.ly/43D2Xuc https://
bit.ly/3Ovu1at -
Optimized LLM Training Framework Reduces Host Memory Overhead
By
–
If you use an optimized #LLM training framework like https://
pbase.ai/3DHqnE5, you can get the host memory overhead back down to a more reasonable 7 * 4 = 28 GiB of host memory even when training on multiple GPUs. -
Loading Model Weights into GPU Memory with Ray Object Store
By
–
How did we do it? By loading the model weights into memory once before training begins and inserting them as numpy arrays into the #Ray object store, we can then zero-copy read the weights directly from shared memory into each GPU worker process.
-
Ludwig simplifies distributed computing with Ray backend integration
By
–
Doing this yourself would normally be a fair bit of cumbersome code, but in Ludwig you get it for free just by running with Ray as the backend runtime. Try it out for yourself: https://
pbase.ai/3qfet19 -
Loading Pretrained Checkpoints: Multi-GPU Memory Challenge
By
–
Before you even get to multi-GPU training with model parallel frameworks like #Deepspeed, you need to load the pretrained checkpoint into memory. To make matters worse for machines with multiple GPUs, you need to load the checkpoint into host memory once for each GPU in your job!
-
Llama2 7B Model Training Memory Requirements on Multiple GPUs
By
–
Now training your 7B parameter #Llama2 model in float32 with 8 GPUs requires 7 * 4 * 8 = 224 GiB of host memory just to load it onto the GPUs.