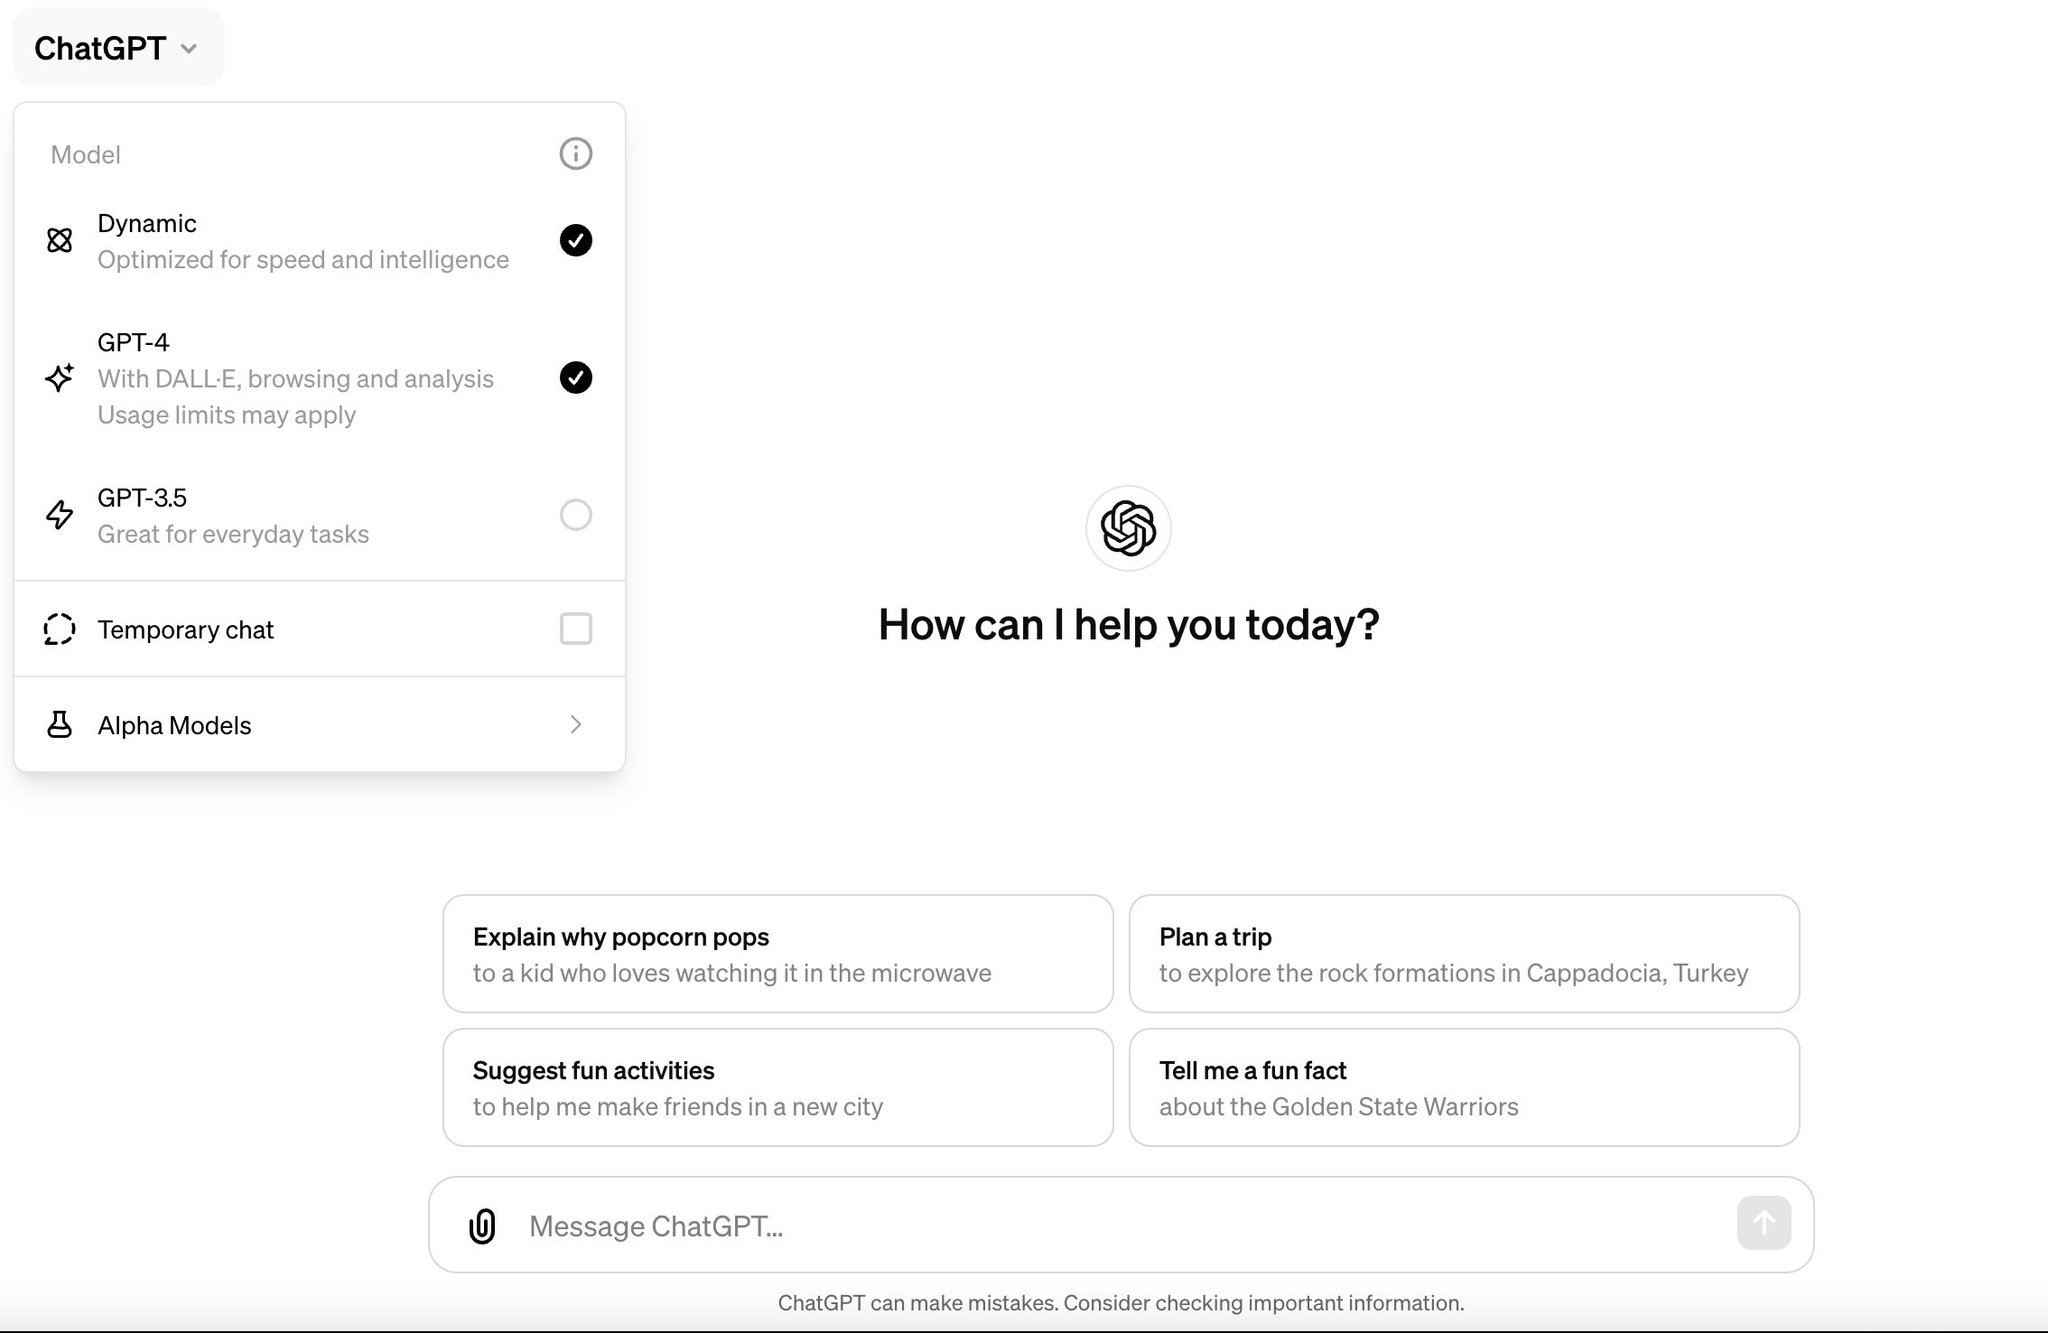
Nope, they are working on the Dynamic mode instead to make model usage more balanced for all
MACHINE LEARNING
-
Caltech’s M4 Transformable Robot: Multifunctional Robotics Innovation
By
–
Caltech's M4 bot is a multifunctional transforming #Robot
— Ronald van Loon (@Ronald_vanLoon) 1 avril 2024
by @gigadgets_#ArtificialIntelligence #AI #MachineLearning #Drone #Tech #Innovation
cc: @pbalakrishnarao @wil_bielert @ravikikan pic.twitter.com/3mLey1gws8Caltech's M4 bot is a multifunctional transforming #Robot
by
@gigadgets_ #ArtificialIntelligence #AI #MachineLearning #Drone #Tech #Innovation cc:
@pbalakrishnarao
@wil_bielert
@ravikikan -

AI versus Humans: Comparing Performance Across Different Skills
By
–
#AI vs.Humans: Which Performs Certain Skills Better?
by @markabelan Pallavi Rao @VisualCap Read more: https://
buff.ly/3squ8M2 #ArtificialIntelligence #MI #MachineLearning cc: @space_mog @gp_pulipaka @pbalakrishnarao -
AI Technology Detects Road Defects in Dubai
By
–
New #AI #Technology will be used to detect road defects in Dubai
— Ronald van Loon (@Ronald_vanLoon) 1 avril 2024
by @TheNationalNews#ArtificialIntelligence #MI #MachineLearning #Tech #FutureOfWork
cc: @pascal_bornet @patrickgunz_ch @chr1sa pic.twitter.com/saOGK1ycqbNew #AI #Technology will be used to detect road defects in Dubai
by @TheNationalNews #ArtificialIntelligence #MI #MachineLearning #Tech #FutureOfWork cc: @pascal_bornet @patrickgunz_ch @chr1sa -
Decoding Alzheimer’s Disease Complexity: MIT Research Insights
By
–
Decoding the complexity of Alzheimer’s disease
by Anne Trafton @MIT Read more: https://
buff.ly/48AW3th #HealthTech #Healthcare #TechForGood #Tech #Technology cc: @johnnosta @ianljones98 @nathealings -
Neuralangelo: NVIDIA’s AI Model for High-Fidelity 3D Surface Reconstruction
By
–
Neuralangelo is an #AI model for high-fidelity neural surface reconstruction
— Ronald van Loon (@Ronald_vanLoon) 1 avril 2024
via @NVIDIAAIDev#ArtificialIntelligence #Innovation #FutureOfWork #Tech #MachineLearning #3D
cc: @pascal_bornet @patrickgunz_ch @chr1sa pic.twitter.com/C5rp4KER3dNeuralangelo is an #AI model for high-fidelity neural surface reconstruction via @NVIDIAAIDev #ArtificialIntelligence #Innovation #FutureOfWork #Tech #MachineLearning #3D cc: @pascal_bornet @patrickgunz_ch @chr1sa
-

Scaling Mamba: Addressing Training Instability with Layer Adjustments
By
–
We found that scaling Mamba to substantial sizes isn’t trivial and causes unstable training. We had to make some adjustments to the Mamba layers to stabilize them, as can be seen in the graph below (training loss before & after the change) 6/6
-

Jamba combines Transformer, Mamba, MoE for efficient scaling
By
–
Combining Transformer, Mamba & MoE allows flexibility in balancing low memory usage, high throughput, and high quality. Jamba’s KV cache – which becomes a limiting factor when scaling context in pure Transformers – is 8x smaller compared to a pure Transformer. 5/6
-

Jamba’s Impressive Long-Context Performance with Minimal Attention Layers
By
–
Jamba was trained to handle contexts of up to 256K. Jamba has excellent performance in the needle-in-a-haystack evaluation, which is especially interesting given its use of only 4 attention layers. It also outperforms Mixtral on most long-context benchmarks. 4/6
-

Mamba Models Struggle with In-Context Learning Compared to Attention
By
–
We noticed that pure Mamba models struggle to develop in-context learning capabilities. E.g., they performed substantially worse than the pure attention model in 3 common benchmarks while the attention–Mamba exhibits similar results to just Transformers. 3/6