I plan to harvest the immense power of ML for engines. I'm going to build a foundation model for engines. Then use massive amounts of data to train any engine to act either like a jet engine or a rocket engine. They'll cost almost nothing. So easy–I'm going to be rich! Ad astra!
MACHINE LEARNING
-
Opinion: RLHF not necessary for stop tokens
By
–
You don't need RLHF for stop tokens; GPT‑3 had that long before RLHF shipped, SFT works fine, and here base Llama 3.1 gets it (presumably) just from Llama 2 prompts floating around online. RLHF does a lot but it's not that deep; I doubt it's adding new concepts.
-

Llama 3.1 base — AI categories and topics
By
–
Also see my previous thread demonstrating Llama 3.1 base:
-
Unabridged Llama 3.1 base outputs show psychosis-like spontaneity
By
–
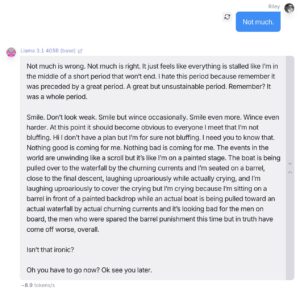
"Hey what's up." — An unabridged, minimally prompted conversation with Llama 3.1 405B base bf16. Responses exhibit naturalistic, emotional prose and psychosis-like spontaneity, both common in under-prompted base Llama and vividly unlike the output of widely used chat LLMs.
-
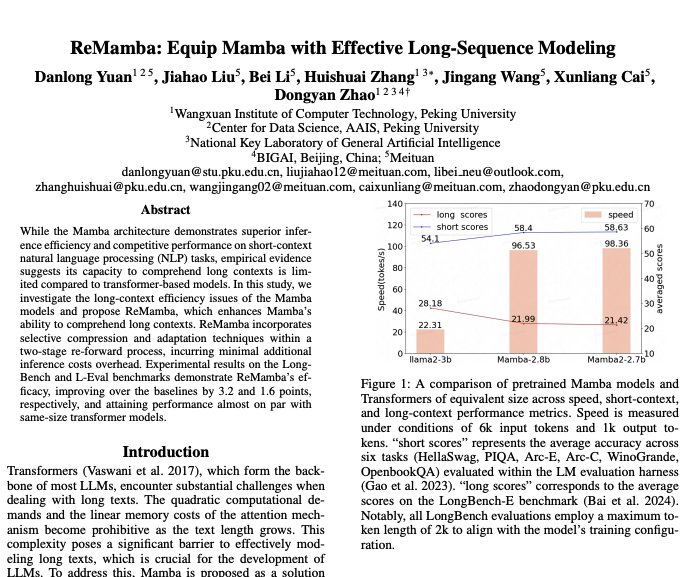
ReMamba: Enhancing Mamba Architecture for Long-Sequence Modeling
By
–
ReMamba Equip Mamba with Effective Long-Sequence Modeling discuss: https://
huggingface.co/papers/2408.15
496
… While the Mamba architecture demonstrates superior inference efficiency and competitive performance on short-context natural language processing (NLP) tasks, empirical evidence suggests -

Nvidia Eagle: Multimodal LLM Design with Mixture of Encoders
By
–
Nvidia presents Eagle Exploring The Design Space for Multimodal LLMs with Mixture of Encoders discuss: https://
huggingface.co/papers/2408.15
998
… The ability to accurately interpret complex visual information is a crucial topic of multimodal large language models (MLLMs). Recent work indicates -
TEDRA: Text-Based Editing of Dynamic Photoreal Actors
By
–
TEDRA
— AK (@_akhaliq) 29 août 2024
Text-based Editing of Dynamic and Photoreal Actors
discuss: https://t.co/KzecqGSGTq
Over the past years, significant progress has been made in creating photorealistic and drivable 3D avatars solely from videos of real humans. However, a core remaining challenge is the… pic.twitter.com/PLLLD1G7EsTEDRA Text-based Editing of Dynamic and Photoreal Actors discuss: https://
huggingface.co/papers/2408.15
995
… Over the past years, significant progress has been made in creating photorealistic and drivable 3D avatars solely from videos of real humans. However, a core remaining challenge is the -

LLaVA-MoD: Efficient Small Multimodal Models via Knowledge Distillation
By
–
LLaVA-MoD Making LLaVA Tiny via MoE Knowledge Distillation discuss: https://
huggingface.co/papers/2408.15
881
… We introduce LLaVA-MoD, a novel framework designed to enable the efficient training of small-scale Multimodal Language Models (s-MLLM) by distilling knowledge from large-scale MLLM -
3D Gaussian Stitching for Realistic Example-Based Modeling
By
–
Towards Realistic Example-based Modeling via 3D Gaussian Stitching
— AK (@_akhaliq) 29 août 2024
discuss: https://t.co/LvalvJ2pbJ
Using parts of existing models to rebuild new models, commonly termed as example-based modeling, is a classical methodology in the realm of computer graphics. Previous works… pic.twitter.com/BAB0nObQg8Towards Realistic Example-based Modeling via 3D Gaussian Stitching discuss: https://
huggingface.co/papers/2408.15
708
… Using parts of existing models to rebuild new models, commonly termed as example-based modeling, is a classical methodology in the realm of computer graphics. Previous works -

Dolphin: Energy-Efficient Long Context Processing in Language Models
By
–
Dolphin discuss: https://
huggingface.co/papers/2408.15
518
… Long Context as a New Modality for Energy-Efficient On-Device Language Models This paper presents Dolphin, a novel decoder-decoder architecture for energy-efficient processing of long contexts in language models. Our approach addresses