Our vision models required an entirely new architecture to support image reasoning. This was accomplished by training a set of adapter weights that integrate the pre-trained image encoder into the pre-trained language model.
MACHINE LEARNING
-
Llama 3.2 Multimodal Models with Improved Image Understanding
By
–
By training adapter weights without updating the language-model parameters, Llama 3.2 11B & 90B retain their text-only performance while outperforming on image understanding tasks vs closed models. Enabling developers to use these new models as drop-in replacements for Llama 3.1. pic.twitter.com/TQo4IIyqRH
— AI at Meta (@AIatMeta) 25 septembre 2024By training adapter weights without updating the language-model parameters, Llama 3.2 11B & 90B retain their text-only performance while outperforming on image understanding tasks vs closed models. Enabling developers to use these new models as drop-in replacements for Llama 3.1.
-

Data Analysis Essentials in Machine Learning Practice
By
–
new sticker dropped from @eugeneyan
's paper club session today QT with war stories of not looking at data -

Moments That Shaped the Internet: Innovation and Tech Evolution
By
–
Moments that shaped the #internet #innovation #tech #5G #smartphone #AI #ML #CustomerExperience #CX #SocialMedia #Netflix #Twitter #Facebook #WiFi #iPhone #Pokemon #YouTube #Google #Amazon #Yahoo #Napster Source @engineers_feed @EstelaMandela @mikeflache
-
Llama 1B & 3B Models Released, Quantized Variants Coming Soon
By
–
It’s still early days for these models and we’re excited for the innovations ahead. The Llama 1B & 3B weights being released today are based on BFloat16 numerics. Our teams are actively exploring quantized variants that will run even faster and we hope to share more on that soon.
-

New Models Outperform Gemma 2 and Phi 3.5 at Smaller Sizes
By
–
We’re seeing exciting performance from these new models, with results that outperform Gemma 2 2.6B and Phi 3.5-mini models on a range of tasks even at smaller sizes!
-
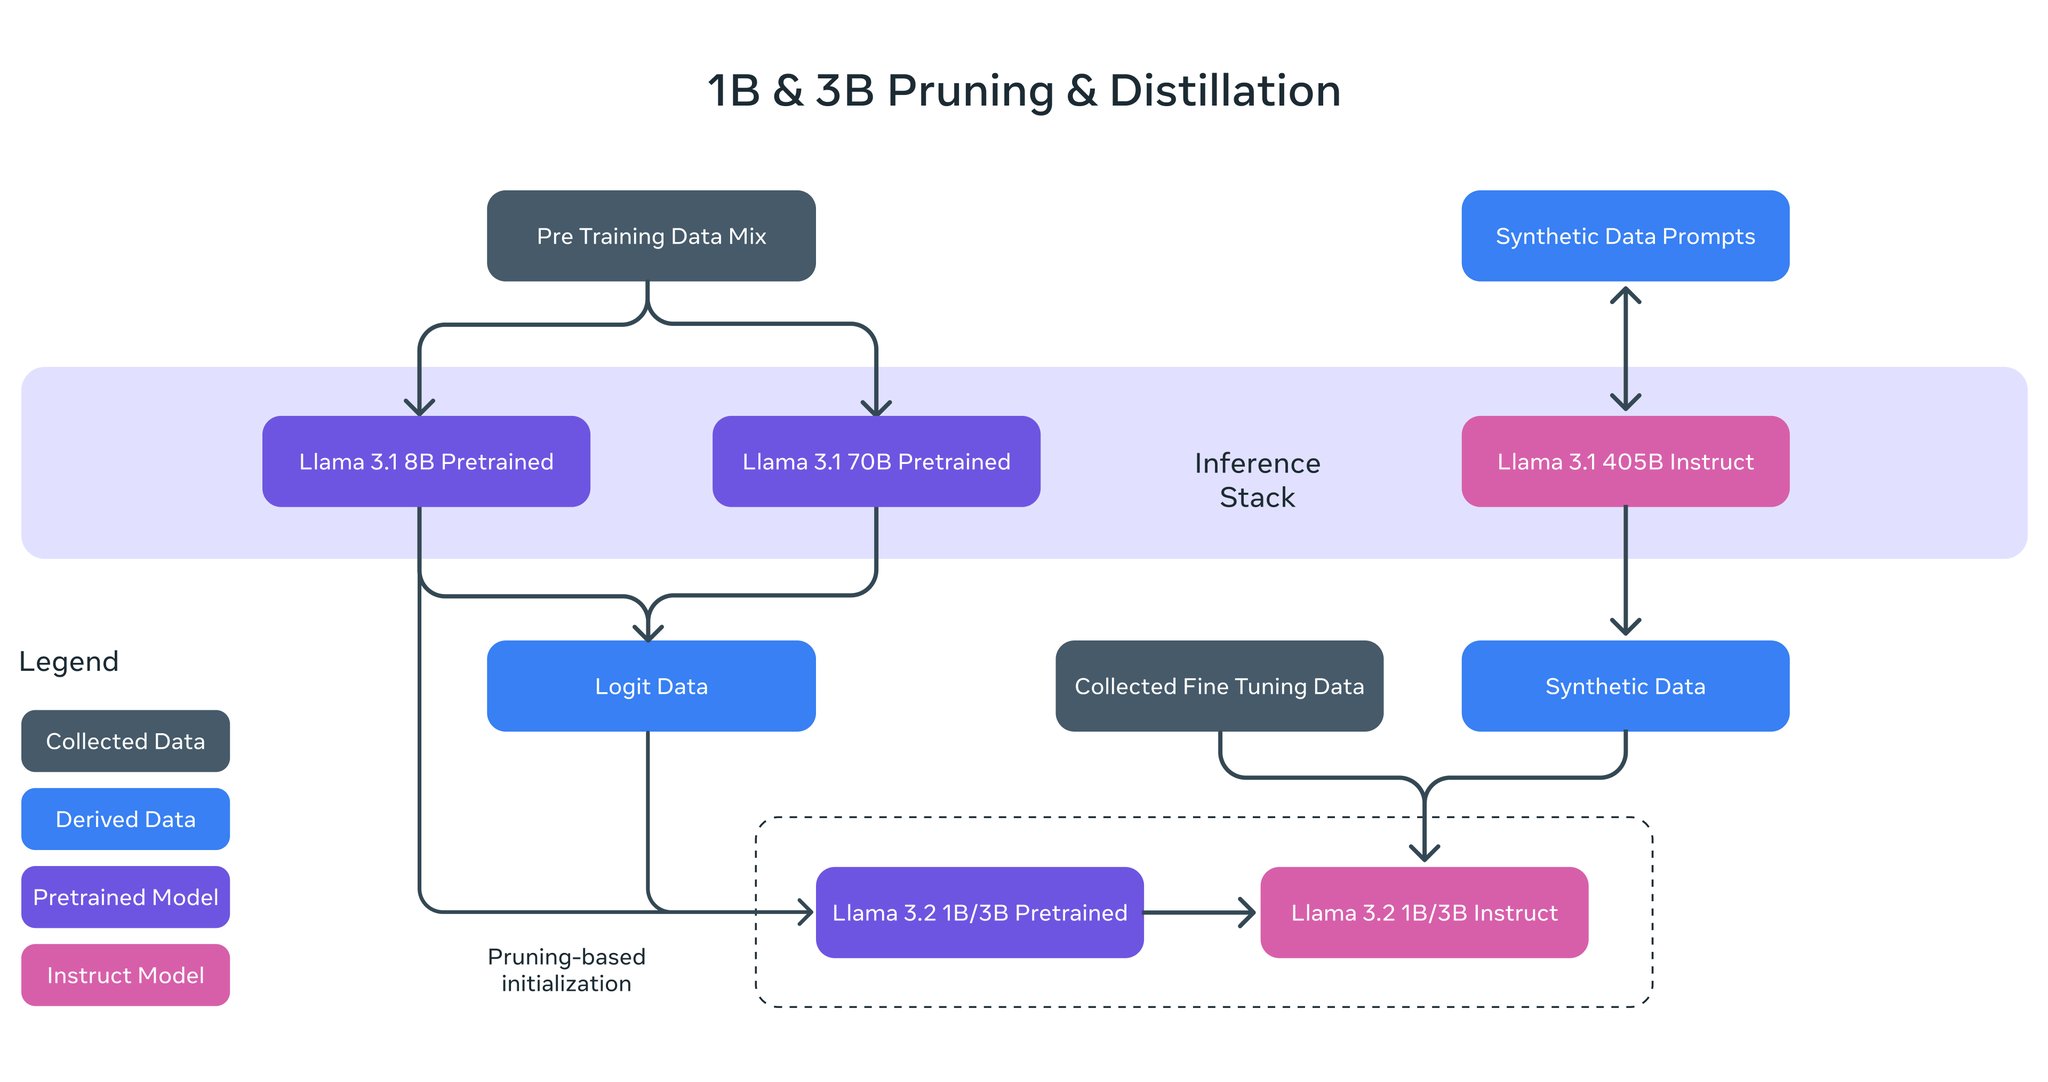
Llama Lightweight Models: Pruning and Distillation Techniques
By
–
These lightweight Llama models were pretrained on up to 9 trillion tokens. One of the keys for Llama 1B & 3B however was using pruning & distillation to build smaller and more performant models informed by powerful teacher models. Pruning enabled us to reduce the size of extant
-
Technical insights on lightweight Llama 3.2 1B and 3B models
By
–
A few technical insights on our lightweight Llama 3.2 1B & 3B models.
-
Inside the Mathematics That Powers Artificial Intelligence
By
–
Inside the maths that drives AI
#AI #AIio #BigData #ML #NLU #Futureofwork @IIoT_World @ipfconline1 @jblefevre60 @JimMarous @insurtechtalk @KirkDBorne @kuriharan @LouisSerge -

Vector LoRA technique test and evaluation results
By
–
Oooh I do like this vector LoRA! (my usual test )