https://
scientificamerican.com/article/inside
-the-secret-meeting-where-mathematicians-struggled-to-outsmart-ai/
…
"The bot spent the first two minutes finding and mastering the related literature in the field. Then it wrote on the screen that it wanted to try solving a simpler “toy” version of the question first in order to learn. A few minutes later, it wrote that it
MACHINE LEARNING
-
AI Masters Mathematics Through Self-Directed Learning Strategy
By
–
-
AI Self-Correction: More Thinking Yields Bigger Failures and Successes
By
–
What about thinking harder? Thinking more? Couldn't the AI be taught to self-correct? Well, according to the paper, more thinkg results in more spectacular results on both sides. Bigger failures.
Bigger successes too.
It cuts both ways. -
Thinking helps with medium tasks but fails on hard puzzles
By
–
For medium tasks, the first answer is often wrong, so thinking further helps it get to the correct answer. With hard tasks (or puzzles in the case of this research), it never manages to figure it out regardless.
-
Reasoning Models Overthinking Easy Tasks
By
–
When a thinking/reasoning model encounters an easy task, something funny happens. The model finds correct answer/plan early, but then it keeps thinking and sometimes talks itself out of it. Overthinking, lol. It's trained on human data, after all.
-
Three Complexity Bands: Where Reasoning Models Excel
By
–
where thinking models do well. Somewhere in the middle. See, there are three distinct complexity bands: → Low: Non-thinking LLMs actually outscore reasoning models.
→ Medium: The reasoning model's chain-of-thought helps.
→ High: Both vanilla and reasoning models drop to 0 %. -
Reasoning Models and the Goldilocks Zone of AI Thinking
By
–
Fast forward to today and we now have reasoning models ("LRMs") that are trained to think. When these first came out, I was skeptical. In my experience, LLM thinking was flawed. Apple's new paper confirms a similar finding. In fact, the identify a "Goldilocks band"…
-

Apple’s Paper Confirms Year-Long Observations About Thinking Models
By
–
Apple just dropped an machine learning paper that finally confirms what I've been noticing for over a year. The paper is about "thinking models" like OpenAI's o-series (o3, etc) Here's what happened:
-

AI Models Predict Career and Academic Success from Facial Images
By
–

Une nouvelle étude affirme que les modèles d’IA peuvent prédire la réussite professionnelle et scolaire à partir d’une seule image du visage d’une personne.
-
LLM Memorization Capacity: Quantifying 3.6 Bits per Parameter
By
–
10. Memorization in LLMs This study introduces a method to quantify how much a model memorizes versus generalizes, estimating GPT models have a capacity of ~3.6 bits per parameter.
-
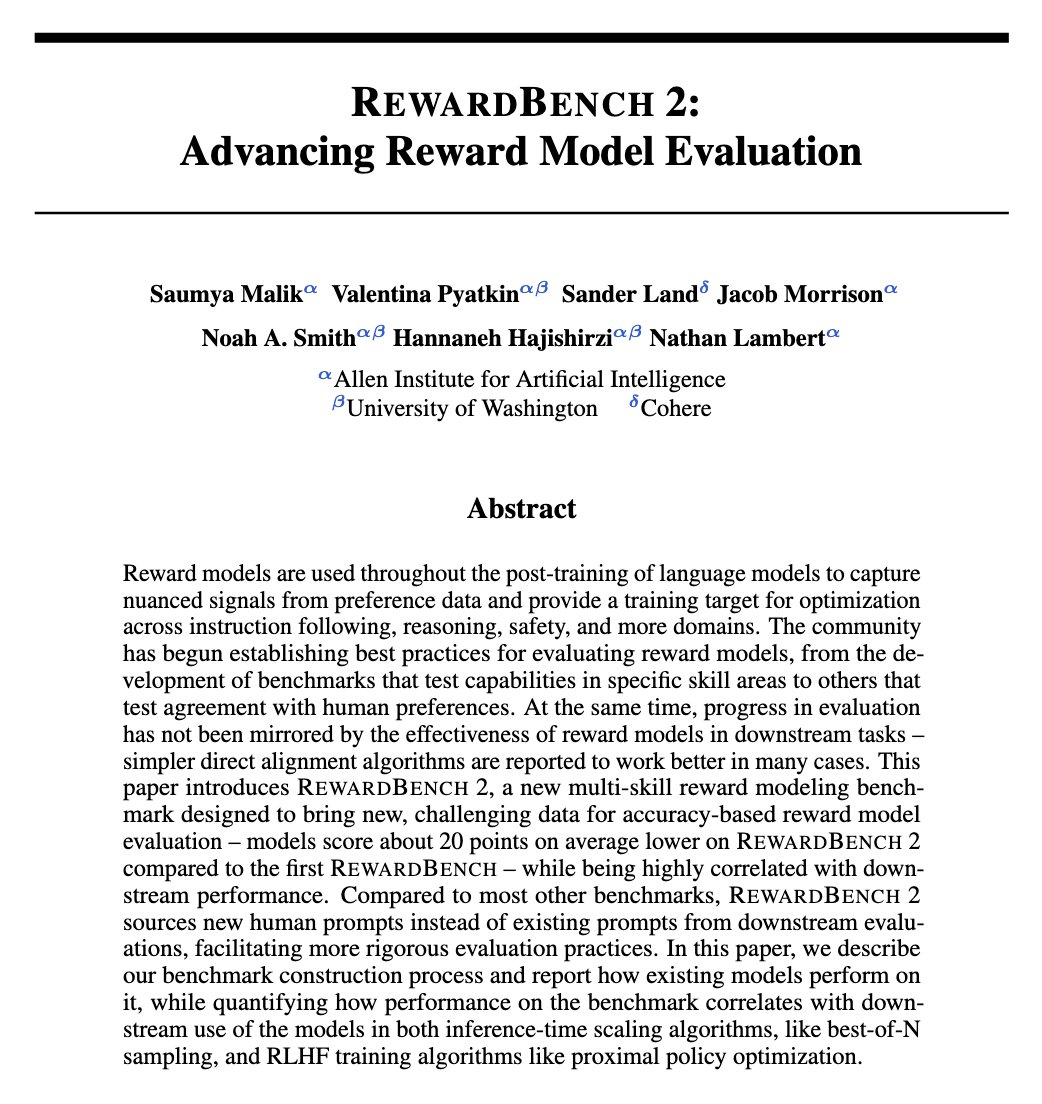
RewardBench 2: New Multi-Skill Reward Model Evaluation Benchmark
By
–
9. RewardBench 2 RewardBench 2 is a new multi-skill benchmark for evaluating reward models with more challenging human prompts and stronger correlation to downstream performance.