Hormis Google et META, Twitter est une des seules plateformes a posséder le stock vidéo necessaire pour entrainer une IA super puissante pour les vidéos
MACHINE LEARNING
-
AGI Benchmarks Double Score in Unprecedented Leap
By
–
Un x2 sur les benchmark qui testent l'AGI, c'était jamais arrivé. Là c'est beaucoup d'un coup
-
Huggingface explains stateless direct response MCP server choice
By
–
If you're developing MCP servers, you should give a read to how the @huggingface team built the Hub MCP, they explain why they chose a Stateless + Direct Response server over other options!
-

Tencent’s ArtifactsBench: Automated Evaluation for LLM Visual Artifacts
By
–
Tencent's Hunyuan team introduced ArtifactsBench, an automated evaluation pipeline for LLM-generated visual artifacts It assesses models on 1,825 diverse tasks with MLLM-as-Judge evaluating visual artifacts, achieving 94.4% ranking consistency with human experts
-

Grok 4 Achieves Perfect AIME 2025 Score and Doubles ARC-AGI Performance
By
–


Alors là… pour l'instant GROK 4 sur le papier, grosse percée ! Sur le benchmark AIME 2025 il a fini le Game (100% de score). Premier modelé à réussir. Sur l'ARC-AGI, un x2 par rapport à ce qu'il se fait aujourd'hui. Et surtout sur le HLE (humanity last exam), il fait
-
AI in Medicine and Domain-Specific Applications with fastai
By
–
Showing that this could be applied to transform an important domain (
@enlitic doing AI in medicine) was the next big step. Then enabled others to do it in their own domains (with @fastdotai
) was next… -
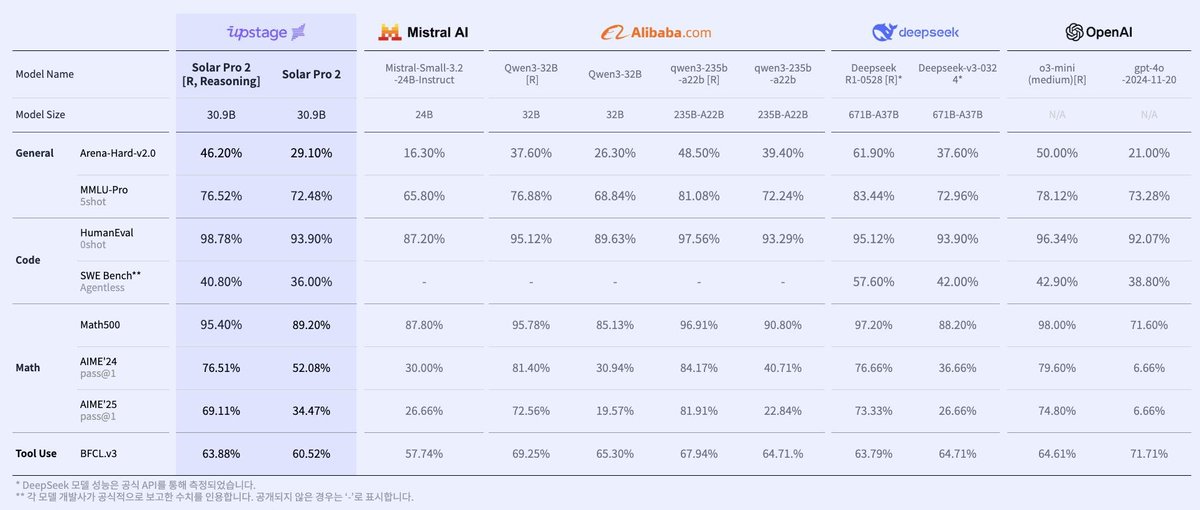
Upstage Launches Solar-Pro2 Frontier Model with Advanced Reasoning
By
–
Finally, @upstageai is proud to announce the launch of its #Frontier model #SolarPro2. We sincerely thank everyone who used our solar-pro2-preview and provided valuable feedback. Leveraging your input, we have incorporated newly developed learning methodologies, enhanced data curation techniques for improved data quality, general reasoning data synthesis methods, and verifiable reward technologies to create this advanced model. The Solar-Pro2 model demonstrates exceptional performance on high-difficulty reasoning benchmarks, including MMLU-Pro, Math500, AIME, and SWE-Bench. Moreover, it excels in Arena-Hard-Auto, a rigorous evaluation framework adapted from LMSYS’s LLMArena, which focuses exclusively on extremely challenging problems. Arena-Hard-Auto is not a simple multiple-choice test—it evaluates answers against those generated by top-tier models, akin to lengthy essay or subjective exams. This benchmark is so demanding that non-Frontier models often score only 10–20%, making it nearly impossible to publish results. Solar-Pro2 (reasoning) achieves a 46% score on Arena-Hard-Auto and 71% on Ko-Arena-Hard-v0.1, surpassing even the highest-quality Korean answers. Solar-Pro2 is now available for immediate use at chat.upstage.ai/ and via API (model name: solapr-pro2). To encourage broader adoption, we offer a TRY-SOLAR-PRO2 $50 credit code (valid until August 31).
-
Consistent ML Trend Growing Over Past Decade
By
–
That has definitely been a consistent trend in ML over the past five or ten years. Not true for everything, but the set of situations where that is true is growing quite quickly.
-
100M Parameter Networks Matching O3 Pro in 100 Years?
By
–
in 100 years, will we have 100M parameter neural networks that perform at the level of today's o3 pro?
— dr. jack morris (@jxmnop) 9 juillet 2025
and if so, how? https://t.co/i80ZeIH3Kyin 100 years, will we have 100M parameter neural networks that perform at the level of today's o3 pro? and if so, how?
-

Custom RL as Service: The New $500M Startup Opportunity
By
–
i think this is comparatively slept on the Current Thing if you depart from OAI (eg TML?) you are doing "we are extremely cracked and we will do custom RL for you!" as a service. 3 dudes in a basement immediately worth $500m. so it's notable when a former OAI RL person says https://
x.com/_kevinlu/statu
/_kevinlu/status/1942977315031687460
…