Navigating The New World Of AI Representation
#AI #AIio #AIInnovation #ML #DataScience #Futureofwork @HaroldSinnott @fogoros @iainljbrown @NandoDF @katecrawford @drhassanrashidi @YuHelenYu http://
ow.ly/je3a30sOj7C
MACHINE LEARNING
-
Navigating the New World of AI Representation and Innovation
By
–
-
ChatGPT-5 Unleashed: Next-Generation AI Capabilities Revealed
By
–
🚨 ChatGPT-5 is next level! Smarter. Faster. Mind-blowingly capable.
— Catherine Adenle (@CatherineAdenle) 9 août 2025
Tried it? What’s the wildest thing it’s done for you? 👇
📹 mrwhosetheboss | IG#ChatGPT5 #AI #ArtificialIntelligence #GenerativeAI #MachineLearning #OpenAI #TechNews #Innovation pic.twitter.com/ckoT0rx9exChatGPT-5 is next level! Smarter. Faster. Mind-blowingly capable.
Tried it? What’s the wildest thing it’s done for you? mrwhosetheboss | IG #ChatGPT5 #AI #ArtificialIntelligence #GenerativeAI #MachineLearning #OpenAI #TechNews #Innovation -
Recent AI Models Surpass GPT-4 Capabilities in Reasoning and Multimodality
By
–
Exactly. Recent releases have given us reasoning, adaptive thinking time, great multimodality, long context, etc. etc. So many things that we see today and are like "oh of course the new model has that", seems like everyone forgot that GPT-4 had none of it.
-

Machine Learning’s Journey: From 30 Pages to AI Evolution
By
–
In the first AI textbook (Rich, 1983), machine learning merited less than 30 small-format pages. But that’s how I got into it.
-
Are We Witnessing The Birth Of Machine Psychology?
By
–
Are We Witnessing The Birth Of Machine Psychology?
#AI #AIio #AIInnovation #ML #DataScience #Futureofwork @HaroldSinnott @fogoros @iainljbrown @NandoDF @katecrawford @drhassanrashidi @YuHelenYu -
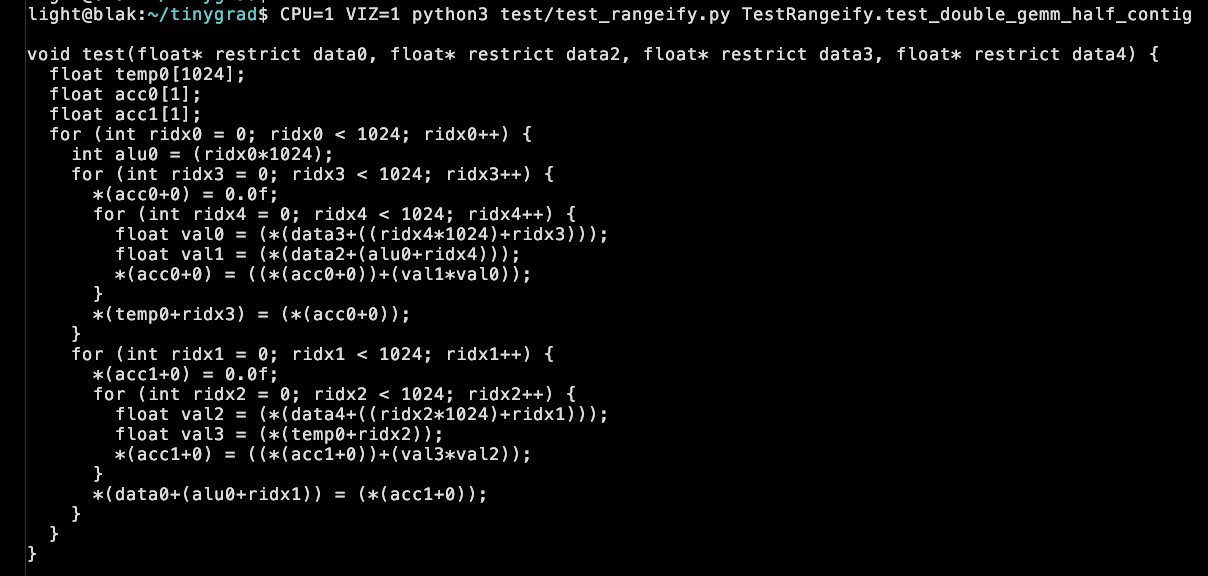
Matrix Operations Optimization for Neural Networks
By
–
This is burying the lede a bit, which is that with a minor change you can also do ReLU(A @ B) @ C on NxN matrices with N intermediates and no recomputation. (aka: a neural network.)
-
Synthetic Data Generation for AI Model Training and Benchmarks
By
–
oh i mean it’s probably synthetic data that was generated to convey skills useful for certain benchmarks. not trying to imply that they’re training on the benchmarks. saw no evidence of that and i doubt it
-

Reasoners Emerge as Pre-Training Scaling Returns Diminish
By
–
Traditional pre-training had diminishing returns (which is what the “scaling law”predicted anyway) The fact that reasoners were developed at exactly the moment where pre-training faltered is exactly the pattern of how Moore’s Law works: new technique appear to maintain the trend
-
Extracting Training Data Directly from Large Language Models
By
–
FUTURE WORK – direct extraction we're working on directly extracting training data from models using RL and other methods. we'll be presenting our first work on this in COLM, and expect more in this space we may be able to directly extract data from the 120b model.. one day