Data Visualization in Python! #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
geni.us/Nelson-Py
MACHINE LEARNING
-
Data Visualization in Python for Analytics and Machine Learning
By
–
-
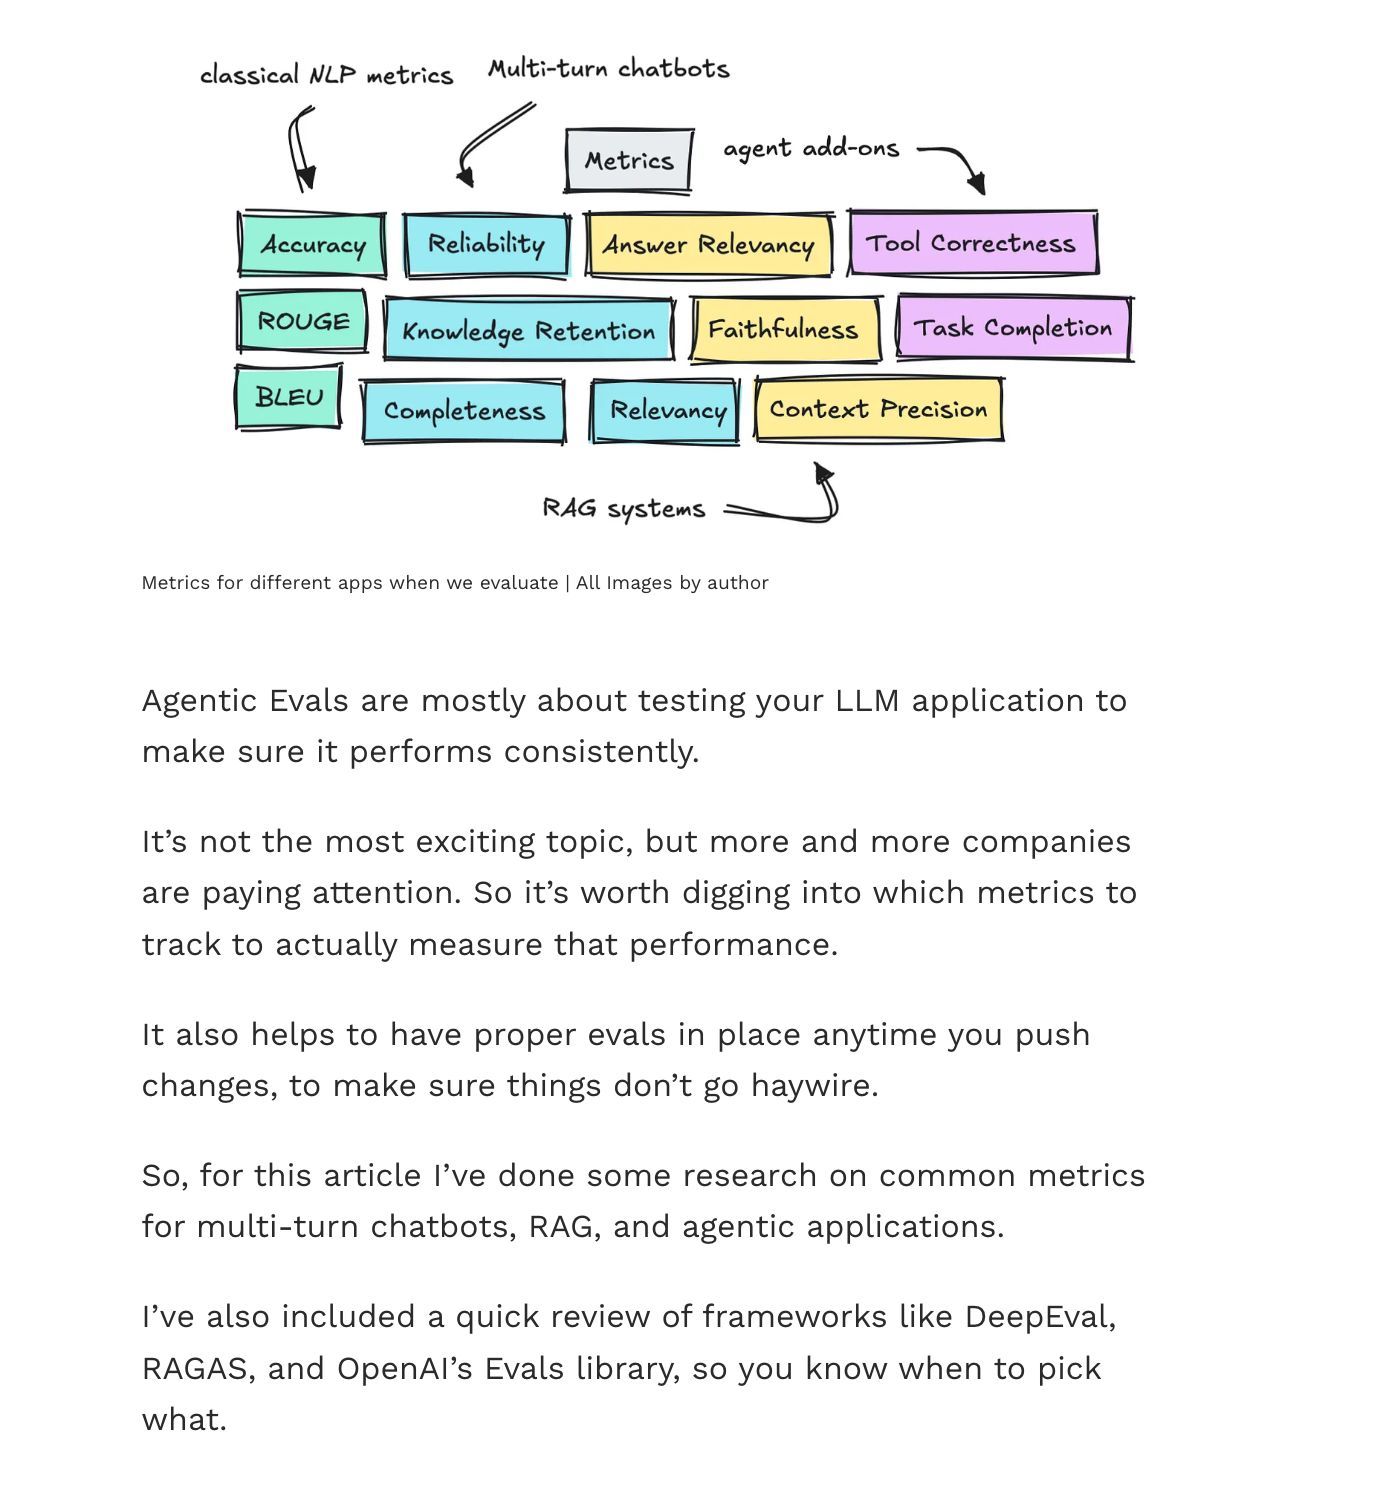
Agentic AI: Evaluation Methods and Best Practices
By
–
Agentic AI: On Evaluations!#BigData #Analytics #DataScience #AI #MachineLearning #NLProc #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #Books #100DaysofCode
-
Machine Learning with R: BigData Analytics and DataScience Tools
By
–
Machine Learning with R. #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
buff.ly/3Y6vQhn -

GPT Engineering with LangChain and LangGraph Advanced Techniques
By
–
GPT Engineering with LangChain and LangGraph! @benji1a #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #Books
-
Share Insights on LLMs AI Agents and Machine Learning
By
–
If you found it insightful, reshare with your network. Find me → @akshay_pachaar For more insights and tutorials on LLMs, AI Agents, and Machine Learning!
-
Multi-GPU Training Strategies for Deep Learning Models
By
–
By default, deep learning models only utilize a single GPU for training, even if multiple GPUs are available.
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
An ideal way to train models is to distribute the training workload across multiple GPUs.
The graphic depicts four strategies for multi-GPU training👇 pic.twitter.com/rEKkFw3pF3By default, deep learning models only utilize a single GPU for training, even if multiple GPUs are available. An ideal way to train models is to distribute the training workload across multiple GPUs. The graphic depicts four strategies for multi-GPU training
-
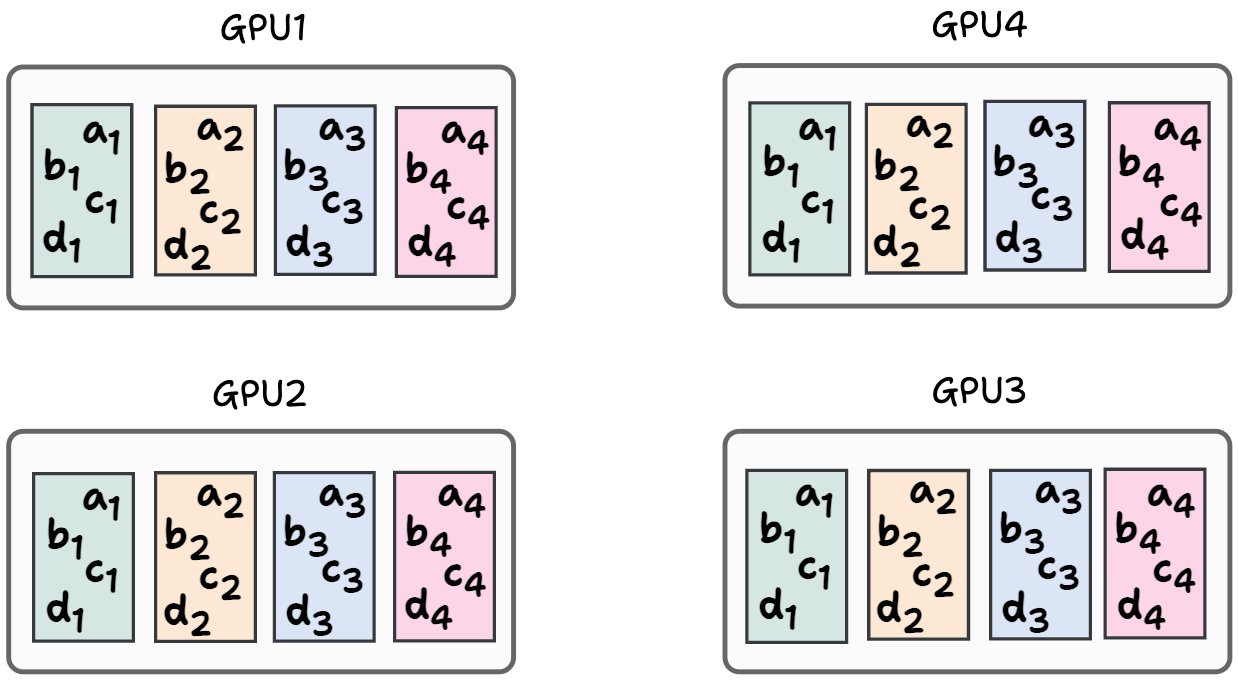
Ring Approach for Scalable Model Weight Synchronization Across GPUs
By
–
And there you go! Model weights across GPUs have been synchronized. While the total elements transferred is still the same as we had in the “single-GPU-master” approach, this ring approach is much more scalable since it does not put the entire load on one GPU. Check this
-
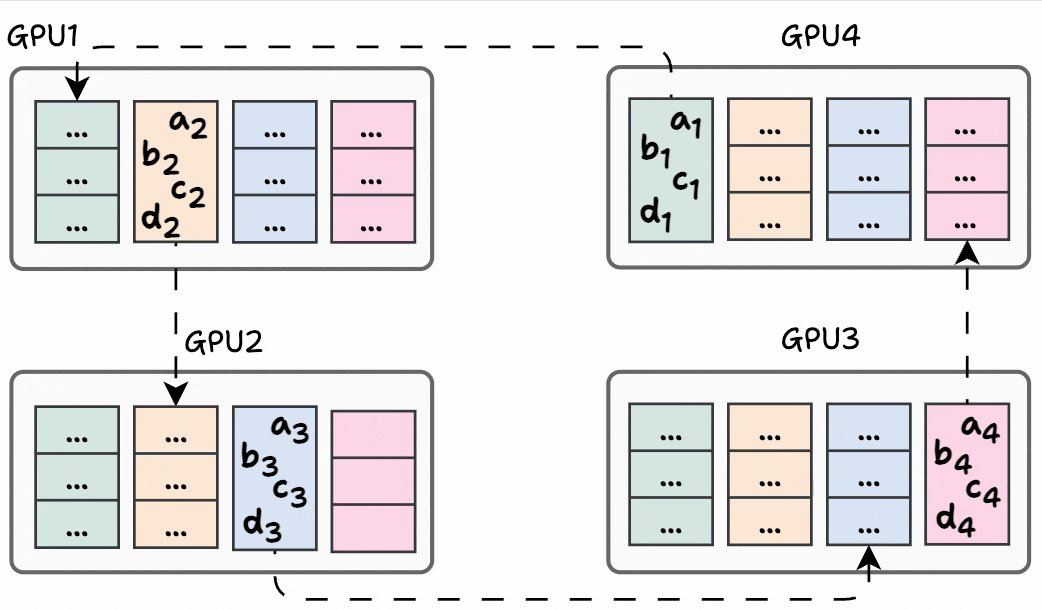
Phase 2: Share-only segment transfer across GPUs
By
–
Phase #2) Share-only
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
Now that each GPU has one entire segment, we can transfer these complete segments to all other GPUs.
The process is carried out similarly to what we discussed above, so we won’t go into full detail.
Iteration 1 is shown below👇 pic.twitter.com/7MssxcJfoEPhase #2) Share-only Now that each GPU has one entire segment, we can transfer these complete segments to all other GPUs. The process is carried out similarly to what we discussed above, so we won’t go into full detail. Iteration 1 is shown below
-

Ring-reduce Algorithm: Share-reduce Phase with Gradient Segmentation
By
–
Algorithm 2) Ring-reduce
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
Phase #1) Share-reduce
First, gradients are divided into G segments on every GPU (G = total number of GPUs).
Check this 👇 pic.twitter.com/15v6GIivHoAlgorithm 2) Ring-reduce Phase #1) Share-reduce First, gradients are divided into G segments on every GPU (G = total number of GPUs). Check this
-

GPU Optimization: Scaling Challenges in Distributed Gradient Communication
By
–
We can optimize this by transferring all elements to one GPU, computing the final value, and sending it back to all other GPUs.
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
This is a significant improvement.
But now a single GPU must receive, compute, and communicate back the gradients, so this does not scale. pic.twitter.com/xgZJ5FdymfWe can optimize this by transferring all elements to one GPU, computing the final value, and sending it back to all other GPUs. This is a significant improvement. But now a single GPU must receive, compute, and communicate back the gradients, so this does not scale.