ActionMesh
— AK (@_akhaliq) 30 janvier 2026
Animated 3D Mesh Generation with Temporal 3D Diffusion pic.twitter.com/WI22IJg3WR
ActionMesh Animated 3D Mesh Generation with Temporal 3D Diffusion

By
–
ActionMesh
— AK (@_akhaliq) 30 janvier 2026
Animated 3D Mesh Generation with Temporal 3D Diffusion pic.twitter.com/WI22IJg3WR
ActionMesh Animated 3D Mesh Generation with Temporal 3D Diffusion
By
–
The false positive rate was 1.4% in both arms of the trial
(radiologist plus AI vs 2 radiologists)
Sensitivity was 80.5% with AI, 73.8% without AI

By
–
Everyone who wrote good code pre-2025 should feel happy that we bootstrapped the current generation of engineers and models
By
–
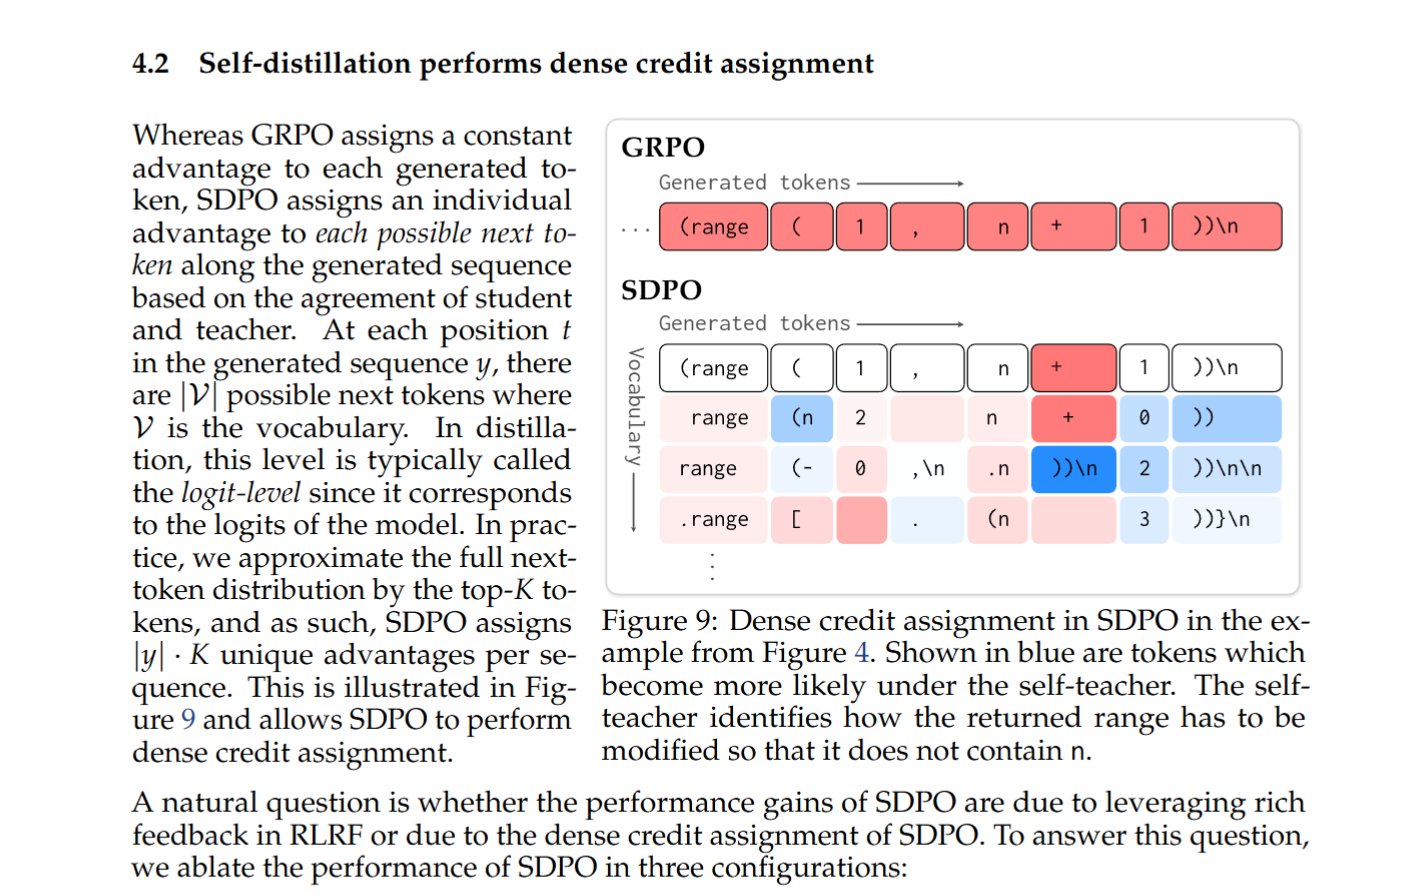
"Reinforcement Learning via Self-Distillation" Current RLVR has a major flaw, where credit assignments and signals are sparse due to its binary feedback So this paper introduced a new paradigm called Reinforcement Learning with Rich Feedback (RLRF), using a new
By
–
The most jam-packed Dose in history includes stories from @neuralink @ModdedQuad @PamphletsY @demishassabis @GoogleDeepMind @RaianyRomanni @davidasinclair @RubenLaukkonen @faunarobotics @maticrobots @Tesla_Optimus @pipedream_labs @standardnuclear @EricTopol @pronounced_kyle @a16z

By
–
For more than 30 years, The Kids’ Cancer Project has worked to transform cancer treatment and research for children worldwide. With the help of SAS, it can continue funding and conducting highly impactful work. See how they work together to save lives: http://
2.sas.com/6014CFybk
By
–
Read All the Good News That's Fit to Print in this week's Weekly Dose from @notboringco
. This is one of the wildest weeks in recent memory, so we added seven Extra Doses for not boring world members:
By
–
I see, but beware, this technology is designed to eventually train AGI. For content creation it's overkill. The ultimate engineering goal here is not to create content on demand (even if that will be possible) but rather to see the limits of models for
By
–
I've been yelling and screaming that the future is world models after Oliver Cameron showed me how. World models are not LLMs (large language models). World models are trained mostly with video data or other kinds of data that isn't really text.
By
–
Yeah, we're in the black and white TV era of this new form of media. It'll improve; it'll just take time. It's not much time, either. You know, 24 months ago, the models could only create hands with seven fingers; now they're creating cinematic movies and things like that. In