shoutouts:
• why multi-agent LLM systems fail? (arXiv:2503.13657) — @mertcemri @melissapan + @istoica05 @matei_zaharia @profjoeyg @adityagp & team • DSPy (arXiv:2310.03714) — @lateinteraction + @hazyresearch lab & co-authors
• GRASP (arXiv:2605.29668) — Jonas Moll,
MACHINE LEARNING
-
Shoutouts to multi-agent LLM systems, DSPy, and GRASP papers
By
–
-
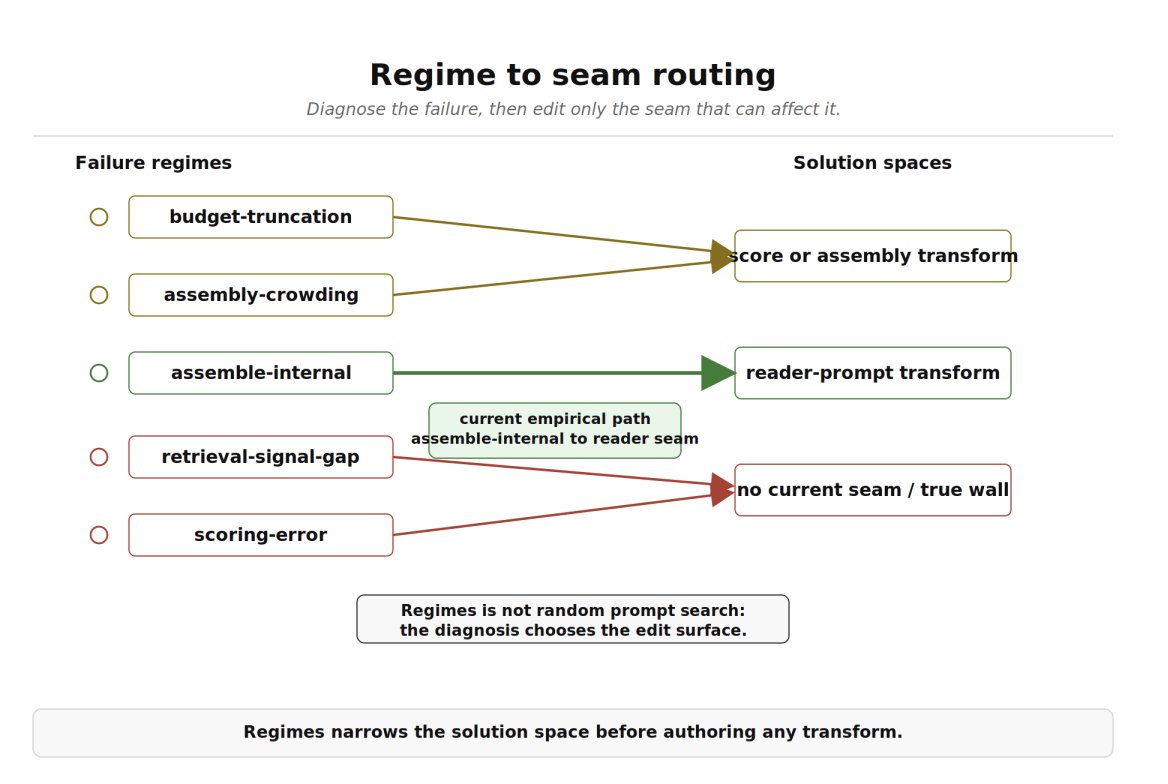
Showcasing controlled self improvement with regime-to-seam approach
By
–
i showcase "controlled" self improvement with a novel regime-to-seam approach where failures are categorized and allowed to fix targeted areas of the agent while interesting, it's more to showcase the type of self-modification that's easy to set up with activegraph
-

ActiveGraph: Auditable Gated Improvement Loop Demonstrated on LongMemEval
By
–
in arxiv paper #2, i tackle the last topic from paper #1: @activegraphai as an architectural affordance for self-improving agents "Regimes: An Auditable, Held-Out Gated Improvement Loop Demonstrated on LongMemEval with ActiveGraph" i demonstrate this with a reproducible gated
-
Refuting claims that satellite latency blocks AI inference or training
By
–
Next thing people are saying you can't do inference or training because satellite to satellite latency is too big Also mostly wrong: https://
x.com/i/grok/share/3
4b7a26aa6954d5ab02d8bbdf63fd2b2
… -
PettiChat uses AI to turn pet behavior into human conversations
By
–
PettiChat Uses #AI to Turn Pet Behavior Into Human Conversations
— Ronald van Loon (@Ronald_vanLoon) 10 juin 2026
by @IntEngineering#EmergingTech #Technology #Innovation #Tech #FutureTech pic.twitter.com/aiezKTRaSxPettiChat Uses #AI to Turn Pet Behavior Into Human Conversations
by @IntEngineering #EmergingTech #Technology #Innovation #Tech #FutureTech -

AI agents improve their own control harnesses
By
–
—
"Auto-Harness: Harnesses That Improve Themselves" What if an AI agent improved the harness that controls how it acts? Thus, instead of humans adjusting prompts, tools, retry rules, and verification for each model, this article explores
— -
Only boomers fix typos; LLMs understand despite mistakes
By
–
only boomers fix typos in prompts. llms perfectly understand you even if you mistype.
-

Claude Fable 5 vs Opus 4.8: one-shot test results
By
–
BREAKING Claude Fable 5 went public yesterday, the first Mythos model, the tier above Opus 4.8. So I tested it. Same 3 prompts, Fable 5 vs Opus 4.8, one shot each, no follow-ups. Watch what came back:
-
AI Improves Seasonal Allergic Rhinitis Diagnosis
By
–
AI Improves Seasonal Allergic Rhinitis Diagnosis
#AI #AIio #AIInnovation #ML #DataScience #Futureofwork @Scobleizer @AndrewYNg @drfeifei @KirkDBorne @fchollet @rowancheung @antgrasso -

Cohere Transcribe ranks #1 in enterprise speech recognition tests
By
–
These tests measure performance in varying signal-to-noise conditions: the kinds of audio found in meeting rooms, contact centres, & phone calls. In other words, environments where enterprise speech applications actually operate. Cohere Transcribe ranked #1 across every metric: