
Struggling with AI that can't handle long, multi-page documents? Researchers from HUST and Xiaomi introduce Doc-V*, an OCR-free agent that starts with a thumbnail overview, then actively retrieves and reads only the relevant pages, storing evidence in a working memory. It
LLMS
-

Technical Requirements for Deploying Long-Running AI Agents
By
–
What does it actually take to deploy long-running agents and the runtime capabilities that make it possible? Join us for an evening in New York with
– Robert Xu, Deployed Engineering @LangChain – Austin Berke, Lead AI Product Engineer @harmonic_ai RSVP: Robert Xu, Deployed -
User switches from Grok 4.1 Fast to Grok 4.3 without reasoning
By
–
I just use whatever is available, yday that was Grok 4.1 Fast Non Reasoning, now I try Grok 4.3 via grok-latest with reasoning set to none
-

RAG is old way; future AI memory is compilation, not retrieval
By
–
RAG is already becoming the “old way” The future of AI memory is not retrieval.
It’s compilation. Here’s the shift in one sentence: From searching information To structuring knowledge The new model? LLM Wiki Instead of: Chunking documents Running similarity -

Secretary MEITY calls for indigenous AI at hackathon
By
–
In his keynote address at the AB PM-JAY Auto-Adjudication Hackathon Showcase 2026, @SecretaryMEITY made the case for building AI that is rooted in India's linguistic and cultural context — and affirmed the IndiaAI Mission's commitment to supporting indigenous foundation model
-

Try Gemma 4 Assistant GGUF Builds on Hugging Face
By
–
You also want to give these Gemma 4 assistant GGUF builds a try on @huggingface →
https://
huggingface.co/collections/At
omicChat/gemma-4-assistant-gguf
… -
Faster Inference for Gemma 4 on LLaMA.cpp with Multi-Token Prediction
By
–
🚨 STOP WHAT YOU ARE DOING AND LOOK AT THESE BENCHMARKS@atomic_chat_hq just unlocked 1.5x faster inference for Gemma 4 on LLaMA.cpp using Multi-Token Prediction.
— Charly Wargnier (@DataChaz) 8 mai 2026
138 tokens per second on a local 26B model is pure sorcery 👀
Get the code and GGUFs below ↓ https://t.co/o4aF64B5eeSTOP WHAT YOU ARE DOING AND LOOK AT THESE BENCHMARKS @atomic_chat_hq just unlocked 1.5x faster inference for Gemma 4 on LLaMA.cpp using Multi-Token Prediction. 138 tokens per second on a local 26B model is pure sorcery Get the code and GGUFs below ↓
-
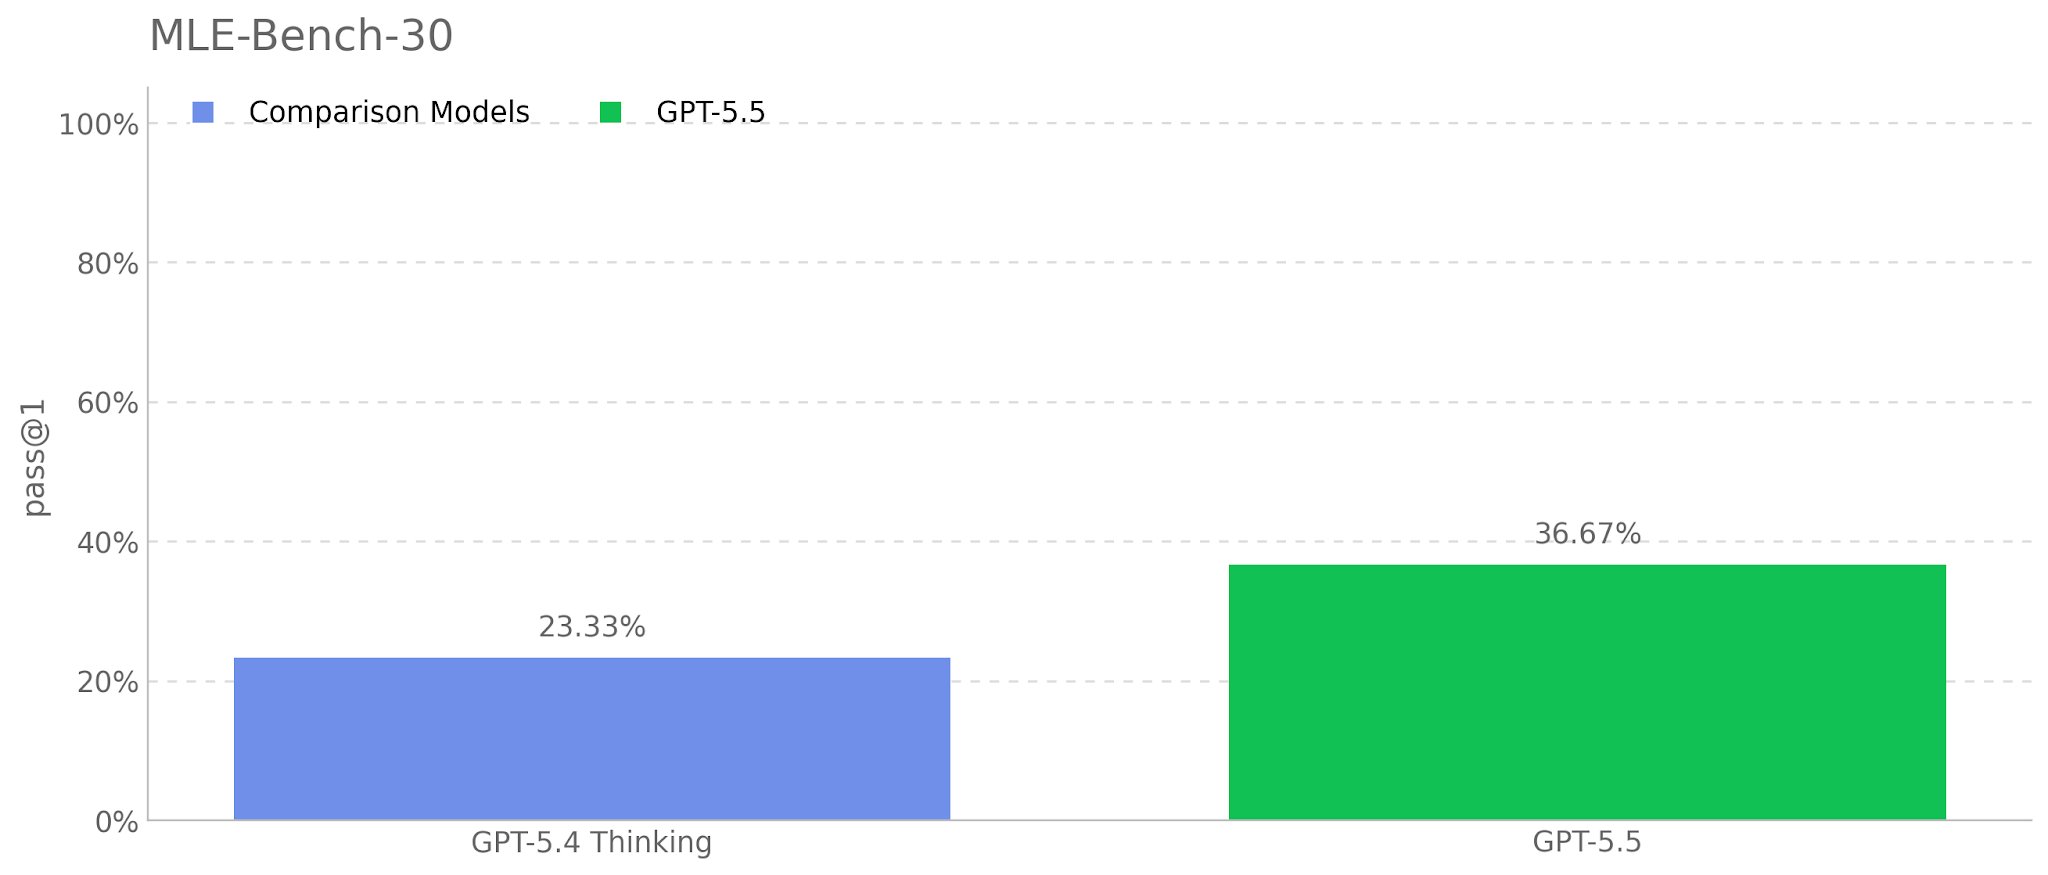
GPT 5.5 Impresses in Deep Learning Research
By
–

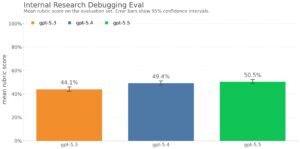
After another week of intensive work with GPT 5.5, I’m once again confirming my initial conclusions: it’s an impressive model. For deep learning auto-research tasks, the improvement over versions 5.2 and 5.4 is highly noticeable! It’s not just about execution and implementation—
-

SecretaryMEITY: Orchestration Layer for AI in Indian Healthcare
By
–
In a panel discussion on Building AI for Indian Healthcare at the AB PM-JAY Auto-Adjudication Hackathon Showcase 2026, @SecretaryMEITY spoke about the need for an orchestration layer that leverages multiple model architectures — LLMs, SLMs and VLMs — to address critical
-
Anthropic’s Playbook on Claude’s AI Prompt Engineering
By
–
🚨 Anthropic quietly dropped a FREE 33-page playbook on Claude’s ultimate cheat code:
— Charly Wargnier (@DataChaz) 8 mai 2026
the 'Skills' folder ✨
Take 30 mins to set it up and stop repeating yourself forever.
Pros build systems, not prompts.
link below ↓ pic.twitter.com/9z2x2stON7Anthropic quietly dropped a FREE 33-page playbook on Claude’s ultimate cheat code: the 'Skills' folder Take 30 mins to set it up and stop repeating yourself forever. Pros build systems, not prompts. link below ↓