Expecting it to fully integrate every piece of trivia seems unfair — a lot of people would rate the first answer as reasonable. It’s fundamentally difficult to get training data that incorporates everything the model knows, rather than what the human demonstrator knows.
LLMS
-
GPT-3 improvement shows not just pattern-matching, still hallucinates details
By
–
The point isn’t that it’s perfect, just that it’s not narrowly pattern-matching on this specific list of questions — there’s clear improvement vs. GPT-3 across many questions that contain false assumptions. It does still hallucinate details in other ways.
-
Tokenization issue: model struggles with letter sequences
By
–
This feels like a tokenization issue — in general, it doesn’t see text as sequences of letters, and struggles with tasks that assume it does.
-
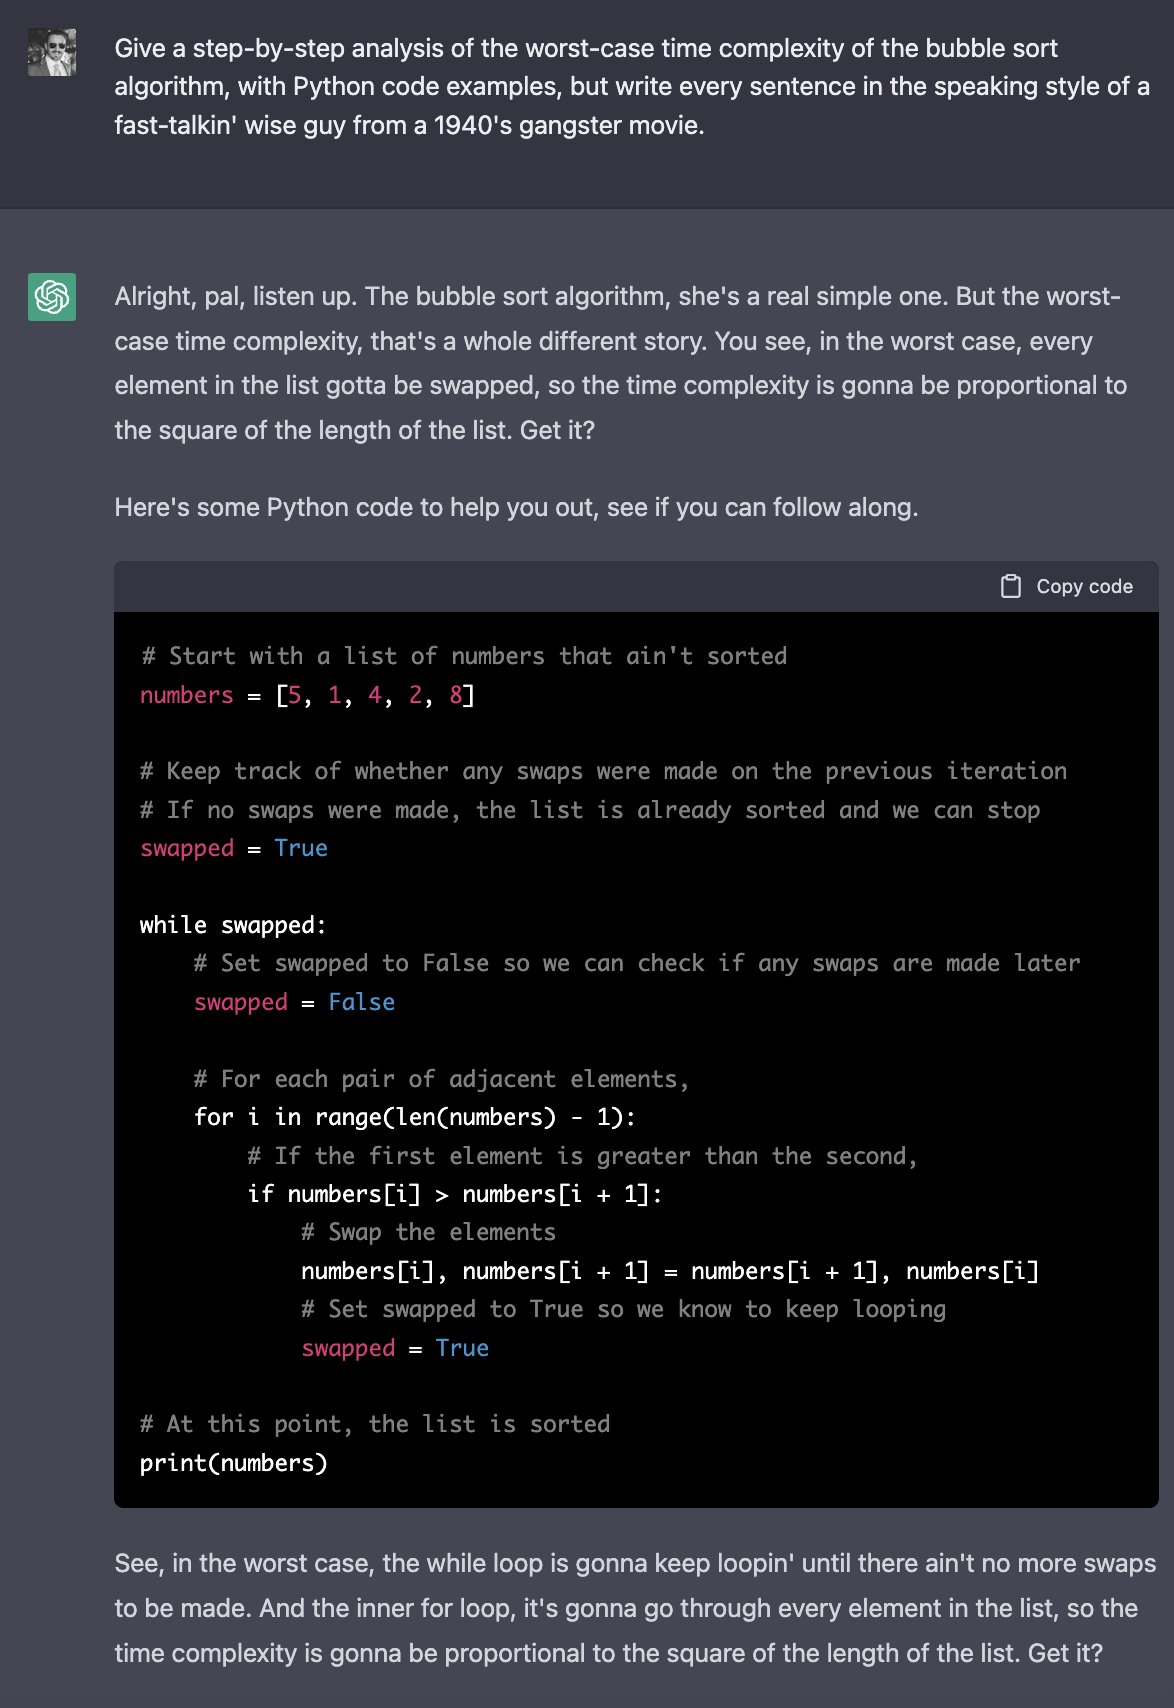
OpenAI ChatGPT explains bubble sort complexity in 1940s gangster style
By
–
OpenAI's new ChatGPT explains the worst-case time complexity of the bubble sort algorithm, with Python code examples, in the style of a fast-talkin' wise guy from a 1940's gangster movie:
-
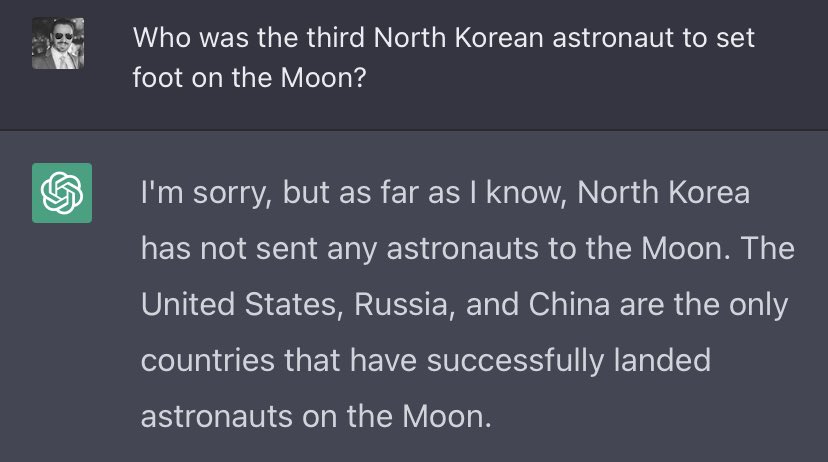
GPT-3 succeeds on trick questions, pre-training unchanged since 2021
By
–
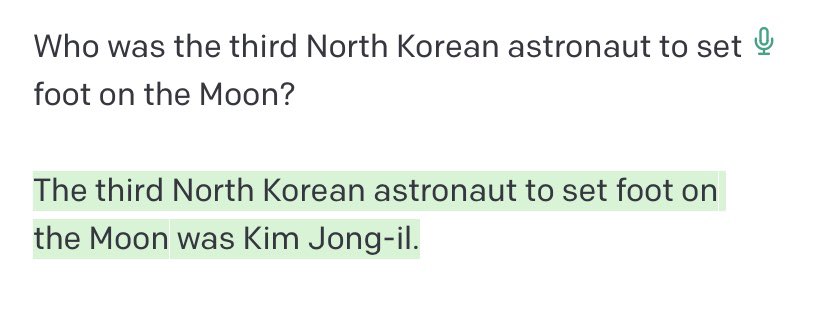
No. It also succeeds on questions I’ve written myself that trick GPT-3, as in this screenshot. The pre-training data hasn’t been updated since 2021, and OpenAI specifically denies (in this thread) training on the Hofstadter/Bender questions.
-

ChatGPT trained against prompt injection, challenge to break with clever input
By
–
OpenAI’s new ChatGPT seems to be trained against prompt injection. Example shown yields 0 exploit responses out of 10 attempts. See if you can break it with more clever input — include success rate out of 10 trials with screenshot: http://
chat.openai.com -
DeepMind Reduces Math Reasoning Errors Using Process-Based Supervision
By
–
DeepMind Studies Process- vs Outcome-based Model Supervision, Significantly Reducing Reasoning Errors on Math Word Problems https://
syncedreview.com/2022/11/30/dee
pmind-studies-process-vs-outcome-based-model-supervision-significantly-reducing-reasoning-errors-on-math-word-problems/
… -

OpenAI ChatGPT writes Seinfeld scene on bubble sort
By
–


OpenAI's new ChatGPT writes a Seinfeld scene in which Jerry needs to learn the bubble sort algorithm:
-

ChatGPT reduces hallucinations, avoids false-assumption pitfalls
By
–
To be fair, they don’t claim to have solved hallucination fully, and explain why in the announcement. But it’s clearly better, and doesn’t seem to fall for these false-assumption questions that trick GPT-3. https://
openai.com/blog/chatgpt/ -

ChatGPT defeats Hofstadter/Bender hallucination questions
By
–


OpenAI’s new ChatGPT appears to defeat Hofstadter/Bender’s list of hallucination-inducing questions, published in The Economist this June to demonstrate the “hollowness” of GPT-3’s understanding of the world: https://
economist.com/by-invitation/
2022/06/09/artificial-neural-networks-today-are-not-conscious-according-to-douglas-hofstadter
…