1000s of toks/sec across a dozen parallel requests if not more
LLMS
-
Gemini 3.5 Flash: Eager Model Built for Real-World Usefulness
By
–
Gemini 3.5 Flash is definitely an over eager model, a bit of over correction from the “Gemini laziness” feedback, but definitely built to be real world useful!
-
LLM trained on whole Internet is inefficient for language understanding
By
–
Learning an LLM from the whole Internet is a spectacularly inefficient way to understand language.
-
Critique of local AI performance metrics as TikTok-style grifting
By
–
No, I am saying that this is the equivalent of TikTok brain rot for Local AI Longest prompt was 368 tons, longest output was 3k and some grifters out there are saying that this is great results of 45tok/s lol If you cannot see how this is performative slop / grifting then
-
Sarcastic commentary on short prompt and costly hardware
By
–
I mean, dude's longest prompt was 368 tokens and longest output was 4k He's literally crying next to that hardware and hoping to get enough engagement that elonbux can pay for his next month installment on those desk warmers
-
GPT 5.5 improving while Claude models worsening, no clear winner
By
–
GPT 5.5 seems to be improving in that direction now, and Claude models are getting worse at it, so I don't think there's a clear winner now.
-
Gemini Flash 3.5 criticized for prioritizing evals over user helpfulness
By
–
Gemini Flash 3.5 is such a disappointing model. It's intelligence and speed is awesome. Absolutely amazing. But it's been trained to max evals, not to be helpful to humans. It goes off and does random crap "for me" rather than just doing what I asked.
-
Need better evaluation of models for human-AI cooperation
By
–
We desperately need better ways of evaluating models. Something that shows how helpful they are at working hand-in-hand with humans to help them get stuff done in a cooperative/iterative way. The Claude models have consistently been better at this, and the market rewards that.
-

LongLive-2.0 AI Model Generates Long Videos with Consistency
By
–
A closer look at LongLive-2.0: • Generates long video at 720p
• Preserves subject and background consistency across multi-shot sequences
• Able to switch prompts at chunk boundaries -
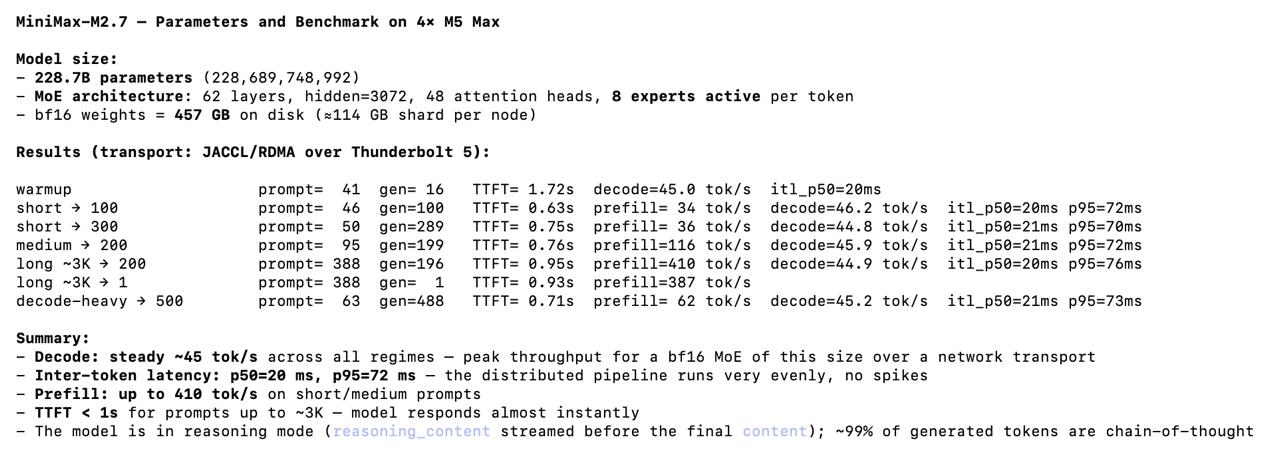
Expensive MacBooks run MiniMax with low performance and limited context
By
–
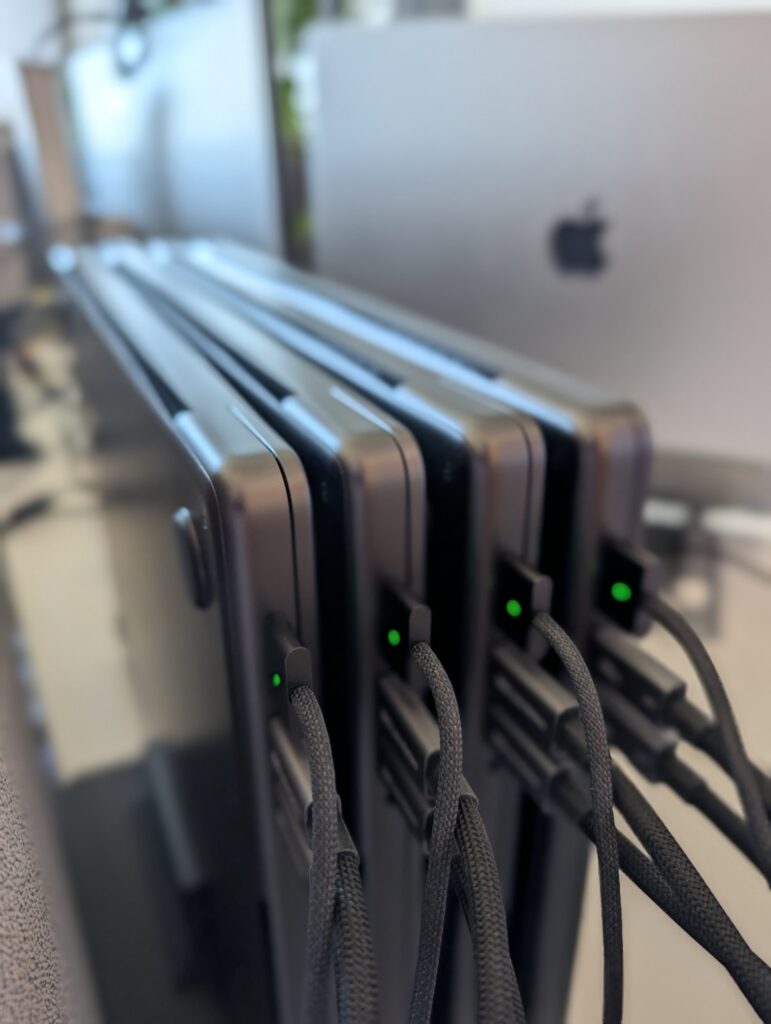
Good example of Performative Inference / Local AI grifting MiniMax-M2.7 on 4x M5 Max MacBooks (~$22,000 USD) – Longest prompt: 338 (???) – Max context: ~3k (???) – 45 tok/s (lol) – Single prompt, no parallel requests Some of the funniest & stupidest shit I've ever seen