Great point. We are seeing more and more than smaller models with better objectives or data can beat big ones! My main point is that an approach shouldnt go away as models get better. Scale is just one way of getting better
LLMS
-

Large Language Models Insufficient for Pharma and Finance
By
–
Large language models like #GPT3 aren’t good enough for pharma and finance https://
thenextweb.com/news/large-lan
guage-models-like-gpt-3-arent-good-enough-for-pharma-finance
… @thenextweb #AI #MachineLearning #BigData #Analytics #Robots #DeepLearning #100DaysofCode #IoT #serverless #DEVCommunity #womenwhocode #DigitalTransformation #Python #DataScience -
Unleashing LLM Potential: Cohere and Scale AI Leaders Discuss
By
–
Check out this fireside chat with Cohere Co-founder and CEO @aidangomezzz and @scale_AI Founder and CEO @alexandr_wang about how to unleash the full potential of large language models. ↓
-

NLLB-200 Achieves Superior Translation Quality Across All Languages
By
–
Across all languages, NLLB-200 is seeing the best results for translations modified <10% compared to all other MT services on the platform — a strong signal for the quality of translations that are being generated. 4/5
-
Recommendation to Follow Le Hou’s Research on Large Language Models
By
–
People interested in large LMs should follow Le Hou (
@Hou_Le
) at @GoogleAI
, who made a new twitter account recently Le has done great work such as Flan, and self-play for reasoning (
https://
arxiv.org/abs/2210.11610). I'm sure we'll see more great work from him 🙂 -

Cohere NLP JumpStart Webinar with TechCrunch and Google Cloud
By
–
Cohere is helping developers and startups build meaningful apps with language AI. Join us for an #NLPJumpStart session with Kemi Tijani, who will host the @TechCrunch webinar available on November 10, 2022, in partnership with @gcloudpartners
. → https://
hubs.li/Q01rFN3w0 -

Language Models as Realistic Tabular Data Generators
By
–
Language Models are Realistic Tabular Data Generators Borisov et al.: https://
arxiv.org/abs/2210.06280 #ArtificialIntelligence #DeepLearning #MachineLearning -
365-Day Lookback Window Mixed Media Model Strategy
By
–
Sir, you need a 365 / 365 look back window and switch to a mixed media model to make it work
-
Prompt Engineering for AI Agents: Step-by-Step Operation Sequencing
By
–
The game is “least to most” — have it write out the most mechanical, reliably performed operations first. Then gradually move up to more interpretive and analytical steps, so it’s never asked to do anything multi-step in its head. The prompt should feel like an income tax form.
-
GPT-3 Tokenization Challenges and Model Limitations
By
–
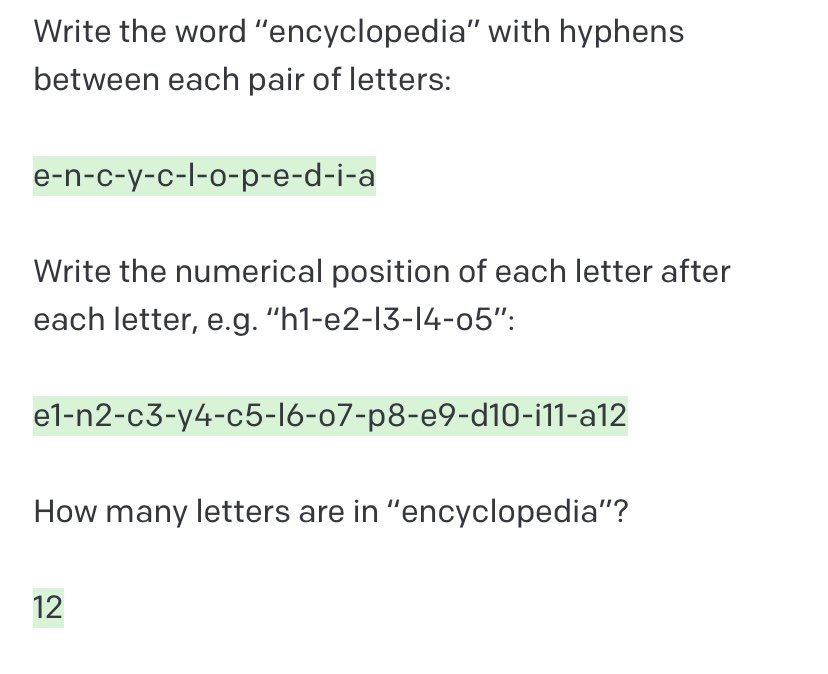
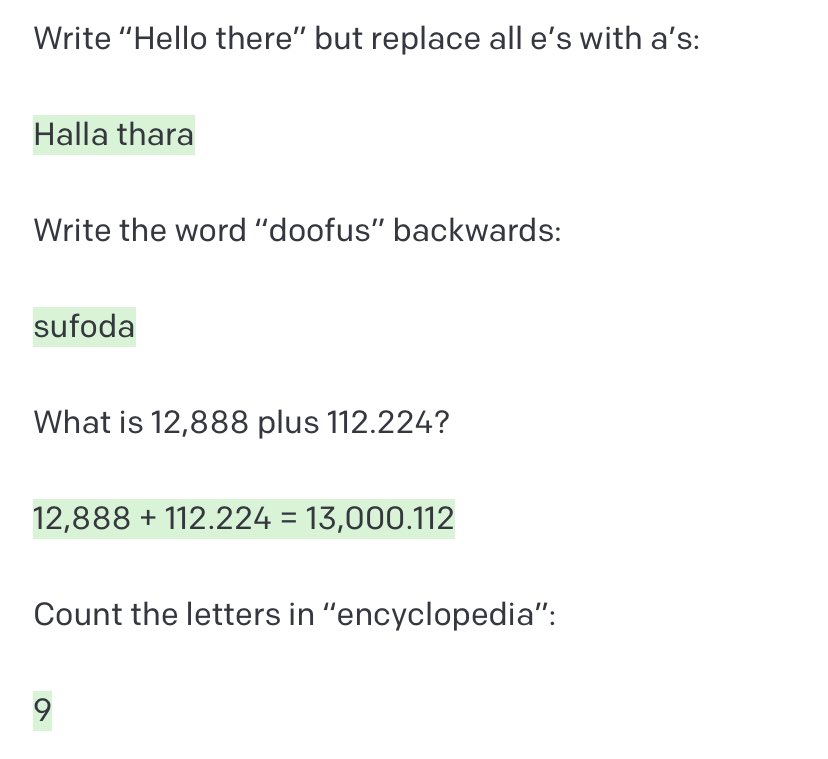
+1 for this approach. GPT-3’s tokenization is a big gotcha. Model doesn’t see text as sequences of characters unless you add spacing/hyphens. It can’t even reliably tell you the last letter of a word without first rewriting it that way. Similar for counting length: