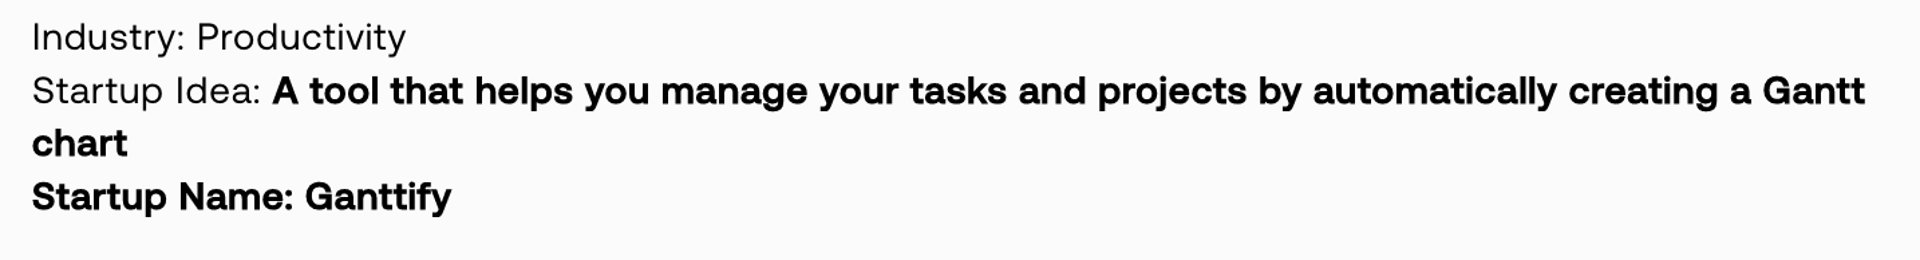
3. Top-p – is similar to top-k, except the choice scoping is not by the token count, but by the sum of the token probabilities. By the way, you can try out the prompt here: https://
os.cohere.ai/custom-preset?
ref=Startup-Idea-Generator-nyrnln&e=generate
…
LLMS
-
Top-p Sampling Technique for Language Models Explained
By
–
-
Top-k Sampling Control in AI Model Generation
By
–
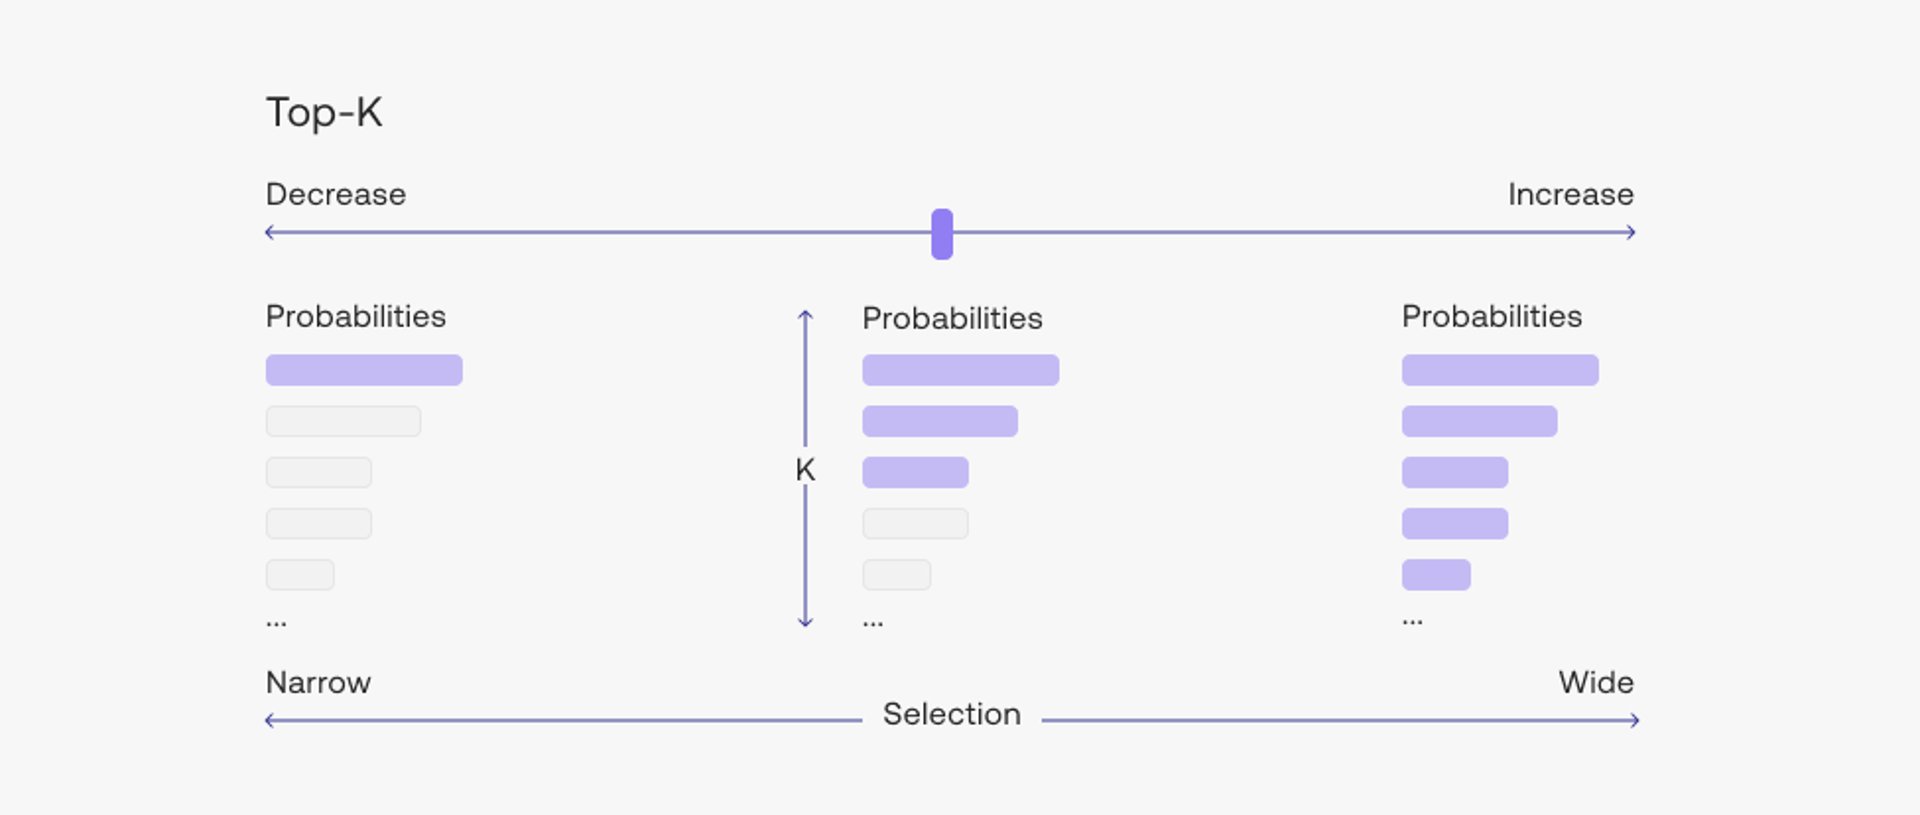
Let’s take the same example of startup ideas brainstorming. Now, set the top-k to 1. This means the model can choose from exactly 1 option. So, no matter how many times you generate, or what temperature value you set, the output will be the same every time, as below.
-
Temperature vs Top-k/Top-p: Token Selection Explained
By
–
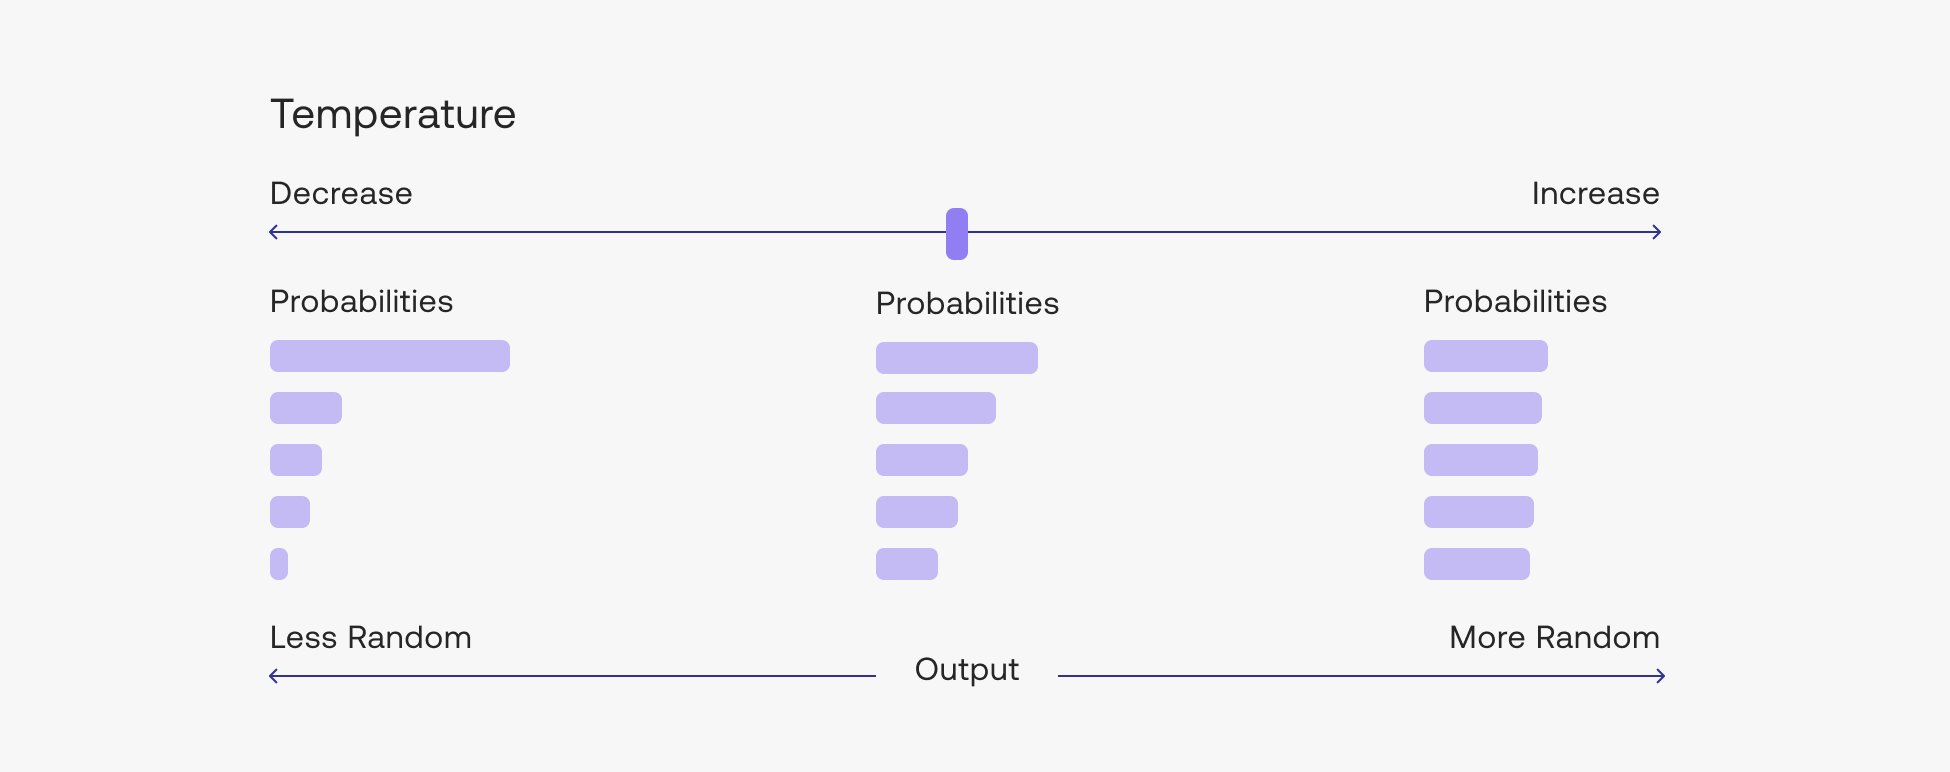
How is it different from temperature? In a nutshell:
• Temperature – how to choose between tokens
• Top-k/top-p – how many tokens to choose from As a result,
• Lower top-k/top-p = more predictable
• Higher top-k/top-p = more creative -
Top-k and Top-p: Controlling Model Token Selection
By
–
2. Top-k (also top-p) – controls the list from which the model can make its choices. Increasing the top-k increases the number of tokens that the model can choose from, and vice versa.
-
Temperature Controls Model Token Generation Creativity
By
–
1. Temperature – controls how the model chooses from its next choice of tokens. Increasing the temperature makes generating tokens with lower likelihoods more probable, and vice versa. As a result:
• Lower temperature = more predictable
• Higher temperature = more creative -

Understanding Token Likelihood Parameters in Language Models
By
–
It does this by giving a “likelihood” number to each token. So, for the phrase “I like to bake …”, “cookies” has a higher likelihood than “chairs.” “chairs” can still appear, but “cookies” has a much higher chance. But we can change this behavior with those 3 parameters.
-
Adjusting Model Parameters: Temperature, Top-k, Top-p
By
–
So, how can you do this? By adjusting the model parameters. There are 3 parameters you can adjust:
1. Temperature
2. Top-k
3. Top-p But before we see how to use them, let’s first understand how the model selects the next token to generate. -
FHE Limitations for Large Model Inference Privacy
By
–
But FHE is not so practical for these models. And it may be infeasible to use some of these large models on a user's device. So even with private fine-tuning, then privacy at inference time still remains. 11/n
-
ML Privacy Risks: Models Can Leak Secrets from Training Data
By
–
There's more such examples in large pre-training datasets. Since ML models pretrained on them without privacy considerations can be coerced to spit secrets out verbatim (see e.g., https://
arxiv.org/abs/2012.07805 by Carlini et al), this dilutes the meaning of "privacy" for such models 7/n -
Private Fine-Tuning of LLMs Shows Modest Utility Loss
By
–
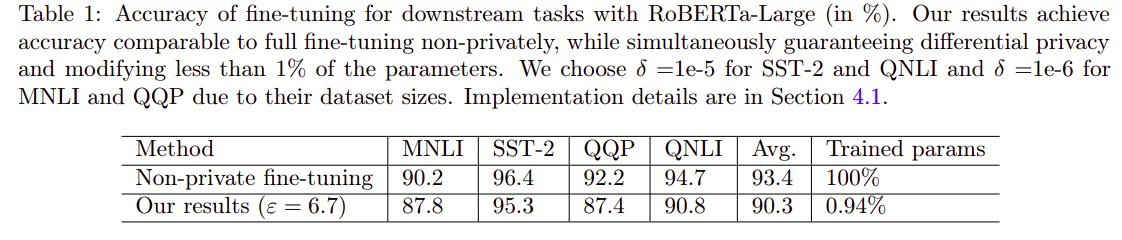
Story is similar for language models. In some prior works at #ICLR2022 (by Yu et al https://
arxiv.org/abs/2110.06500 and @lxuechen et al https://
arxiv.org/abs/2110.05679), it was shown that privately fine-tuning (publicly) pretrained LLMs suffers only a modest utility loss. 4/n