
Microsoft is exploring a deal to acquire Inception, an AI lab that recently released Mercury 2, the world's first reasoning diffusion LLM, according to Reuters. Imagine diffusion Copilot

By
–
Microsoft is exploring a deal to acquire Inception, an AI lab that recently released Mercury 2, the world's first reasoning diffusion LLM, according to Reuters. Imagine diffusion Copilot
By
–
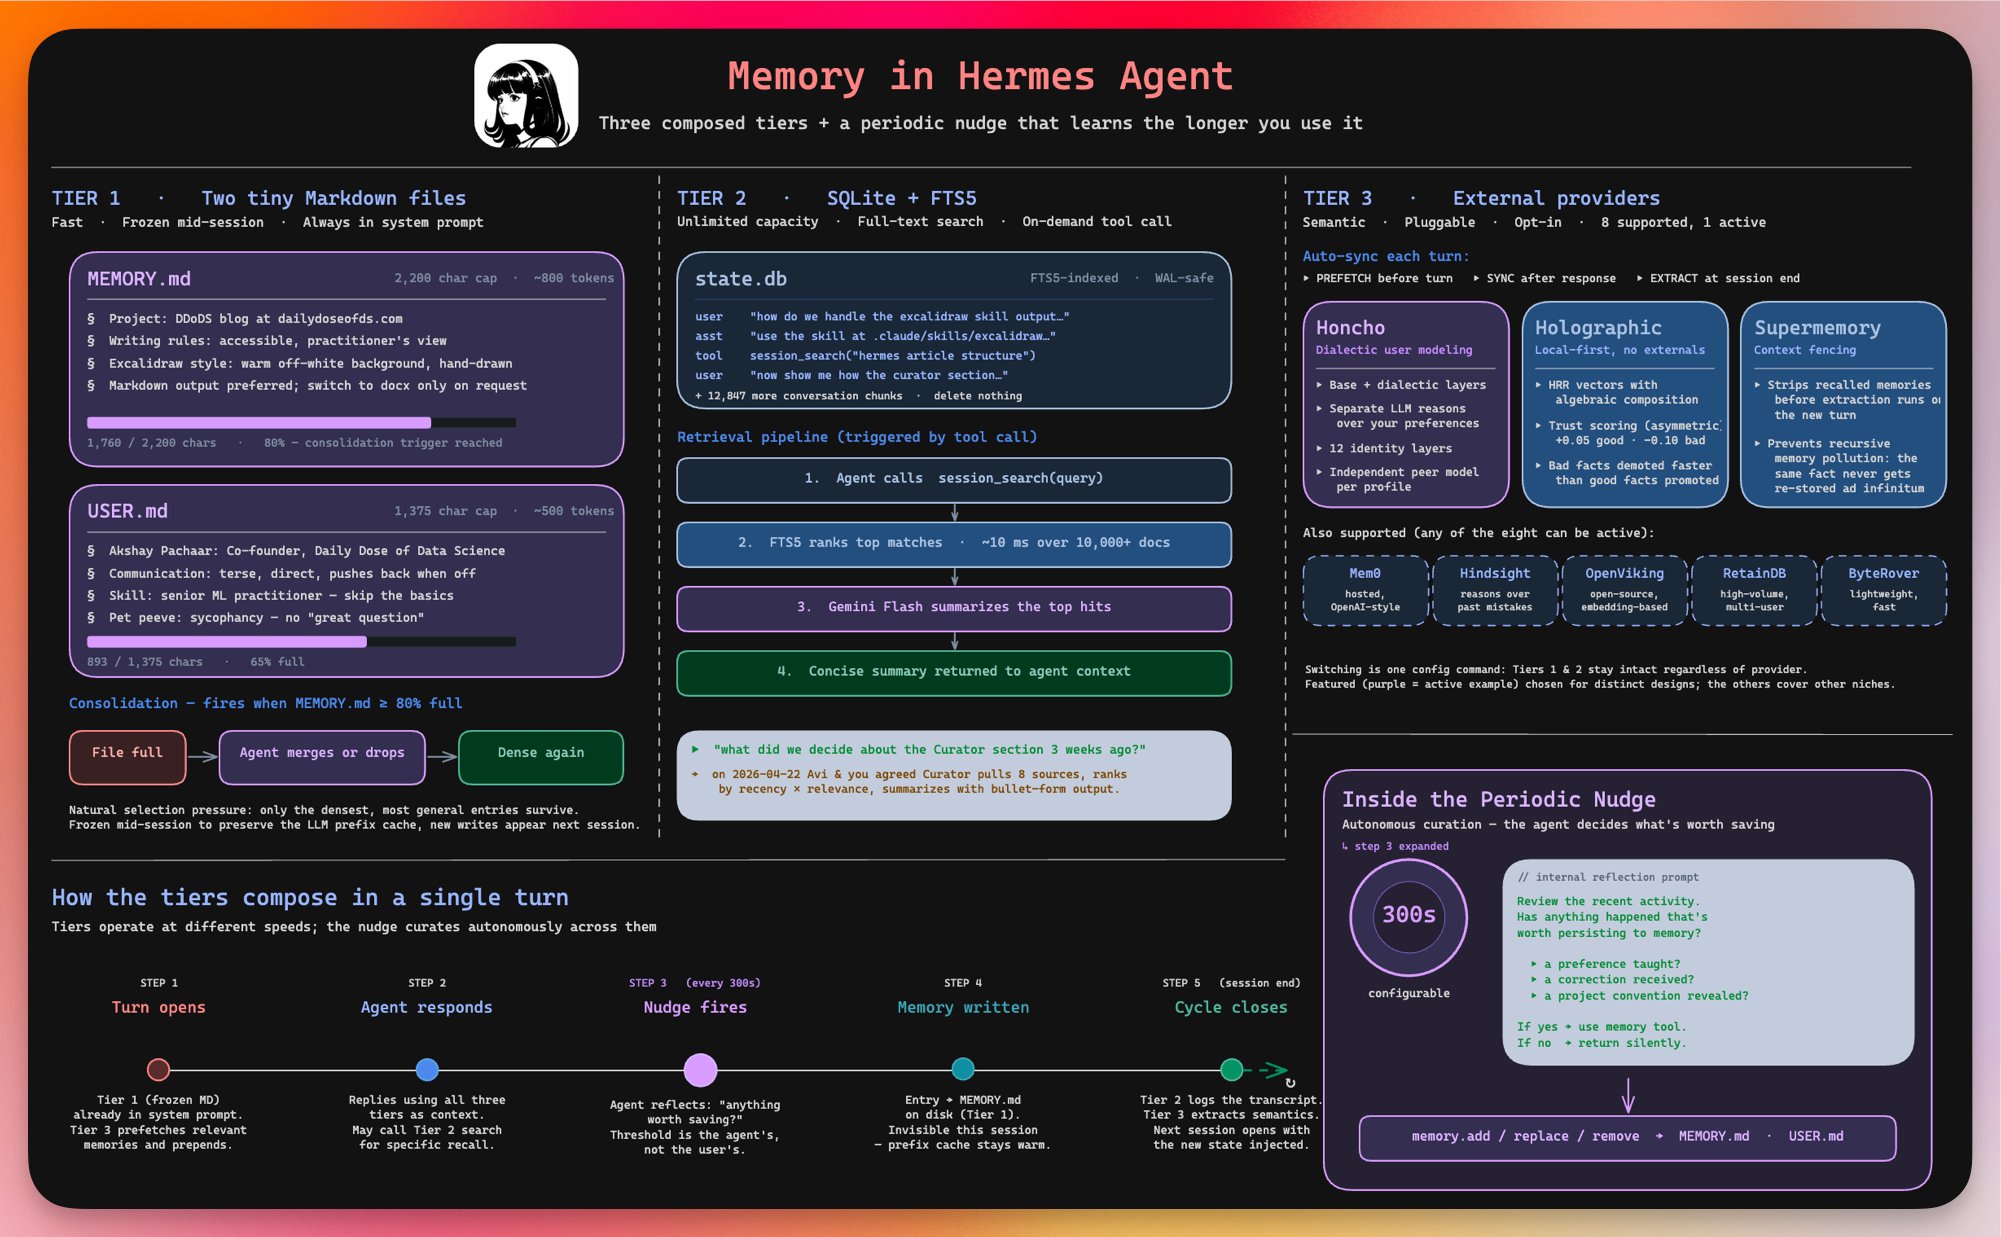
the three-tier memory of Hermes agent. AI agents forgets everything when your session ends. Hermes doesn't. it has three memory layers, each at a different speed. 𝘁𝗶𝗲𝗿 𝟭: 𝘁𝘄𝗼 𝘁𝗶𝗻𝘆 𝗺𝗮𝗿𝗸𝗱𝗼𝘄𝗻 𝗳𝗶𝗹𝗲𝘀 MEMORY.md (2,200 chars) and USER.md (1,375 chars).
By
–
The job of the future: AI orchestrator. For every task, deciding between 15 models based on 4 variables: intelligence, cost per token, hallucination rate, and latency. Between Claude Opus at $15 per million tokens and the Chinese Qwen at $0.50, there’s a 30x difference. Multiplied by…

By
–

OpenSquilla released a new open-source AI agent designed for executing cost-efficient, long-running tasks. It offers 60-80% token savings and is available under the Apache-2.0 license! > ML classifier sends simple tasks to cheap models, complex ones to stronger models > 60-80%
By
–
Wrote a skill that runs codex /review in a loop until there's no booboos anymore. Caveat: It won't fix system architecture for ya, so you still need BRAIN as master model. https://
github.com/steipete/agent
-scripts/blob/main/skills/codex-review/SKILL.md
…
By
–
same, models are so good at planning and inferring intent that you don’t really need to add the extra step of planning!

By
–
Patched LLaMA.cpp
→
https://github.com/AtomicBot-ai/atomic-llama-cpp-turboquant
…

By
–
GGUF models on @huggingface → https://
huggingface.co/AtomicChat/Qwe
n3.6-27B-UDT-MTP-GGUF
…
By
–
🚨 LOCAL AI JUST GOT A SERIOUS SPEED BOOST
— Charly Wargnier (@DataChaz) 14 mai 2026
I just found a custom setup for Qwen 27B.
> Qwen 3.6 quantized with @GoogleDeepMind's TurboQuant
> from 21 to 34 tokens per second
> +40 % performance boost 🤯
feels incredibly smooth on my Mac.
open-source code just dropped ↓ https://t.co/0zXA4uCXyz
LOCAL AI JUST GOT A SERIOUS SPEED BOOST I just found a custom setup for Qwen 27B. > Qwen 3.6 quantized with @GoogleDeepMind
's TurboQuant
> from 21 to 34 tokens per second > +40 % performance boost feels incredibly smooth on my Mac. open-source code just dropped ↓
By
–
Full /goal documentation from Anthropic: