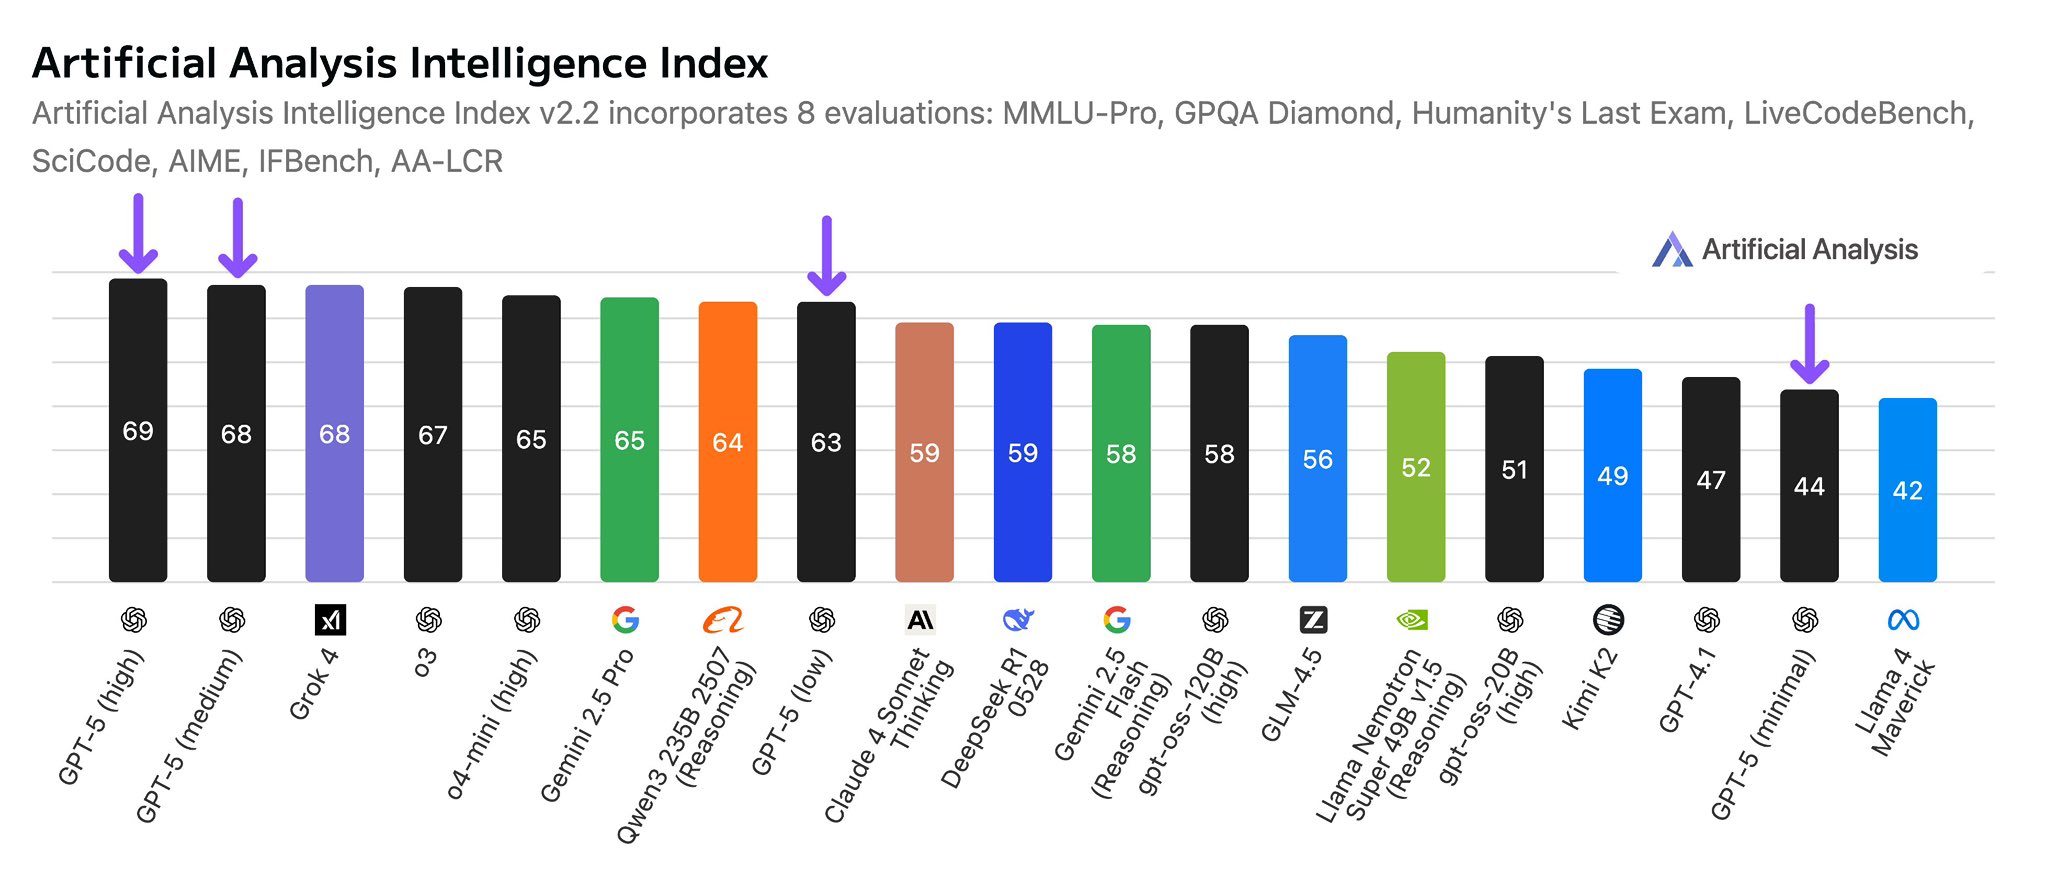
Tu as tout résumé, je peux dire qu’avec GPT-5 j'arrive à le mener à faire ce que je veux, c'est juste qu'il faut le prompter différemment. Et ça les gens, n'aiment pas
LLMS
-

Agent Reliability: Catching Hallucinations and Verifying Groundedness
By
–
Agent Reliability A practical guide to help you catch hallucainations, verify groundedness, and monitor tool usage for LangChain/LangGraph applications: https://
docs.futureagi.com/cookbook/cookb
ook13/Adding-Reliability-to-Your-LangChain-LangGraph-Application-with-FutureAGI
… -
GPT-5 on Replicate: An Addictive Experience
By
–
Playing with GPT-5 on Replicate is addicting. pic.twitter.com/e7jQEm1Kap
— Replicate (@replicate) 9 août 2025Playing with GPT-5 on Replicate is addicting.
-
Sam Altman Shares GPT-5 Deployment Update and Changes
By
–
Update au sujet de GPT 5 : Sam Altman : Je voulais donner plus d’informations sur le déploiement de GPT-5 et les changements que nous mettons en place pour ce week-end. – Nous avons clairement sous-estimé à quel point certaines choses que les gens apprécient dans GPT-4o
-

OpenAI’s naming confusion despite promises of simplification
By
–
OpenAI: with GPT-5 we are getting rid of all the confusing naming schemes (4o, o4,o4,4.1,…) Also OpenAI: do you want the thinking mode, thinking-think or think-mode?
-
LLMs Cannot Distinguish Context: Collaboration vs High-Stakes Evaluation
By
–
Two situations: 1 I wave a co-worker to my monitor to show them a file I have open. "Is this right"? 2 I sit down someone at a table. They have 2 hours to respond. This is an exam. The stakes are high. "Is this right?" The humans collaborator knows 1 vs 2. The LLM doesn't know
-
Qwen3 4B Thinking Model Achieves Fantastic Pelican Benchmark Results
By
–
I've even seen some of them wildly over-think on my pelican benchmark – got a fantastic result from Qwen3 4B Thinking yesterday
-
LLMs Becoming Too Agentic By Default
By
–
I'm noticing that due to (I think?) a lot of benchmarkmaxxing on long horizon tasks, LLMs are becoming a little too agentic by default, a little beyond my average use case. For example in coding, the models now tend to reason for a fairly long time, they have an inclination to
-
LLM Security Challenges: Protection Against Emerging Attack Classes
By
–
Right, that's why the stuff is such a massive nightmare: so many of the things that we want to use LLMs for can't be done securely in the absence of a completely reliable protection against this class of attacks – which so far does not exist