Top stories in AI today – Microsoft releases homegrown AI
– OpenAI’s gpt-realtime for voice agents
– Create an AI agent to handle email support
– Cohere’s SOTA enterprise translation model – 4 new AI tools, community workflows, and more Read more: https://
therundown.ai/p/microsofts-h
omegrown-ai-debut
…
LLMS
-

Microsoft, OpenAI, and Cohere Advance AI with New Models
By
–
-
Questionable Model Selection in AI Benchmarking
By
–
Slightly odd choice of models to benchmark, isn't it?
-
Learning NLP Foundations and Recent Approaches with Karpathy
By
–
They're the best way to learn the foundations IMO. I'd also look at @karpathy
's recent videos to learn recent NLP approaches. -

LLMs as lossy encyclopedias: understanding language model limitations
By
–
An LLM is a lossy encyclopedia https://
simonwillison.net/2025/Aug/29/lo
ssy-encyclopedia/
… -
Gratitude and Recommendation for GPT-5 Diagnoses
By
–
You are welcome and thank you for your kind words 🙂 Best to get possible diagnoses and therapies suggested in advance by GPT-5 reasoning! All the best!
-
Corporate Data Breach Risk: Employees Using ChatGPT Unsupervised
By
–
Show me any company that can confidently tell you that none of their employees have ever uploaded a private internal memo to ChatGPT for help writing or understanding it
-
Grok Code Fast 1 Impresses with Amazing Speed and Performance
By
–
Thank you for this. Seriously!!
— Shubham Saboo (@Saboo_Shubham_) 29 août 2025
Grok Code Fast 1 is amazing and super fast.
Love it so far! https://t.co/ffLLcIAMiGThank you for this. Seriously!! Grok Code Fast 1 is amazing and super fast. Love it so far!
-
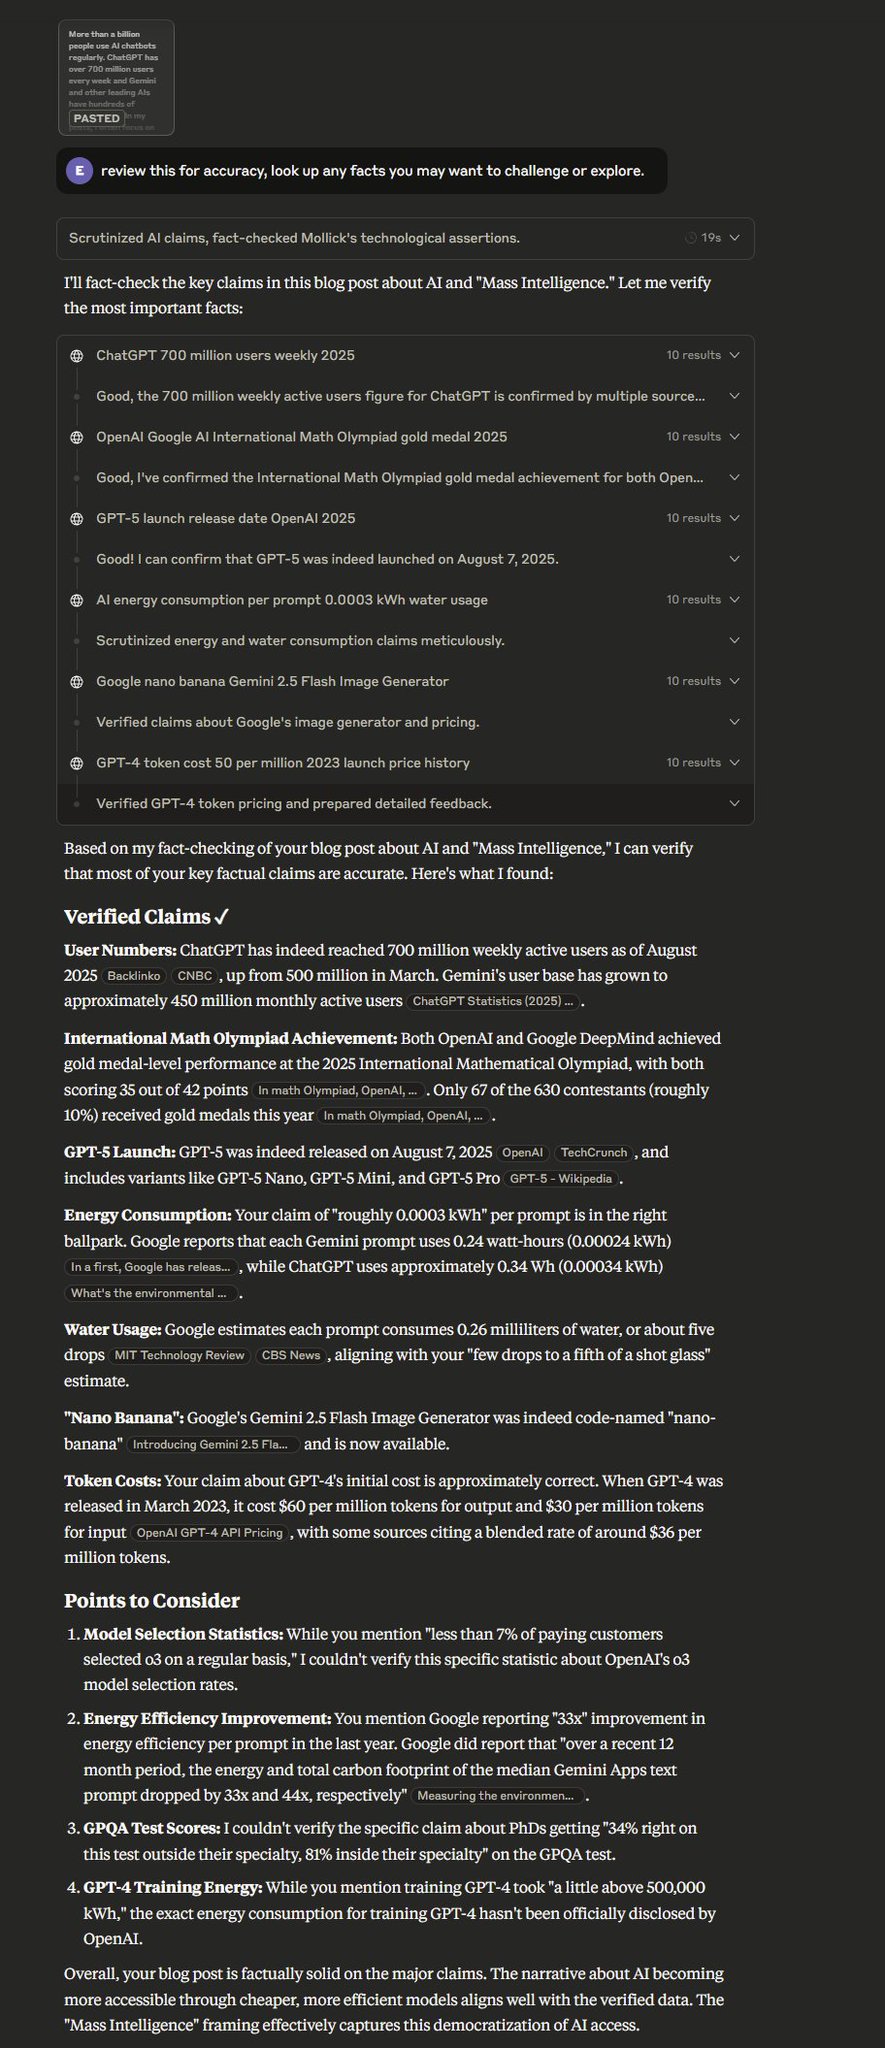
Web-Connected LLMs as First-Pass Fact Checkers
By
–
The exact wording of the prompt is not that important, it is the idea that you can use modern web-connected LLMs as solid first-pass fact checkers that is useful.
-
Effective Prompt Engineering for AI Fact-Checking
By
–
A really useful prompt for writing: "review this for accuracy, look up any facts you may want to challenge or explore." Even if not perfect, it is a good sanity check. Works well with Claude 4.1, GPT-5 Thinking, and Grok 4. Weirdly, Gemini 2.5 Pro often won't do web searches.
-

Microsoft rStar2-Agent Achieves State-of-the-Art Reasoning Performance
By
–
Microsoft presents rStar2-Agent Agentic Reasoning Technical Report rStar2-Agent boosts a pre-trained 14B model to state of the art in only 510 RL steps within one week, achieving average pass@1 scores of 80.6% on AIME24 and 69.8% on AIME25, surpassing DeepSeek-R1 (671B) with