I find it unimaginably based that the OAI Evals team keeps making benchmarks finding that Claude is better and publishing it anyway. they are 3 for 3 this year in acknowledging specifically how much Claude is better at tasks OAI care about. there is no sarcasm here folks. this
LLMS
-
100+ Free AI Agents and RAG Systems Tutorials
By
–
100+ free step-by-step tutorials with code covering: AI Agents RAG Systems Voice AI Agents MCP AI Agents Multi-agent Teams Autonomous Game Playing Agents P.S: Don't forget to subscribe for FREE to access future tutorials.
-

Awesome LLM Apps Reaches 70k Stars: 100+ Free AI Agents
By
–
Awesome LLM Apps just crossed 70k+ stars. 100+ AI Agents and RAG apps with step-by-step instructions. 100% free and Opensource.
-
Build Your Own LLM: Practical ML Learning Roadmap
By
–
> tired of "learn ml in 5 years" energy? want the roadmap from: > "what's a token?" to
> "i built + shipped my own LLM"? phase 0: build from zero, no theory jail > math + code sanity check: > > if matrix multiplication scares you, hit 3Blue1Brown's linear algebra series
> > -
GPT-5 Release: User Expectations for Advanced Thinking Models
By
–
Going to sleep now, I would be very disappointed if it is just regular GPT-5 slop, if it is the thinking model with a bit of special flair, then I might be impressed. Fingers crossed, looking forward to waking up tomorrow
-
GGUF Quantization: 350M Model Uses Just 380MB
By
–
Really tiny. We released GGUF quants, so with 8-bit precision and 4k context the 350M will use ~380 MB and the 1.2B ~1.4 GB (to give you a rough estimate).
-
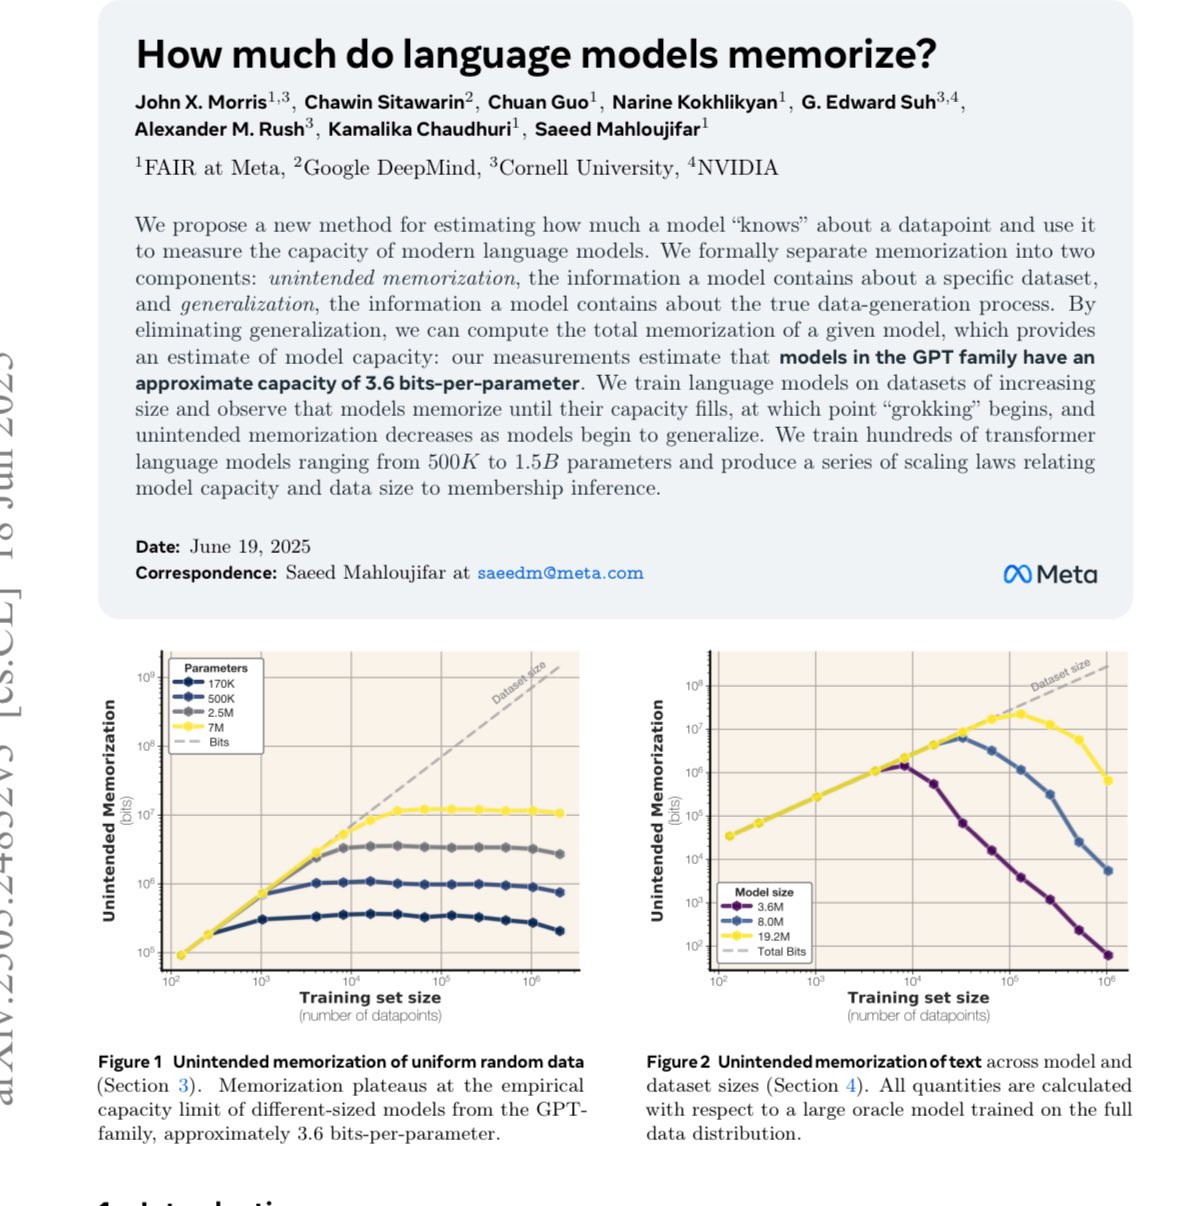
Transformers Need 56.9B Parameters to Memorize Wikipedia
By
–
by the way. recently wrote a paper on this! for transformers, the number is about 3.6 bits-per-parameter so you would need 25GB ÷ 3.6 bits ≈ 56.9B parameters to exactly memorize Wikipedia that’s a pretty big model actually
-
OpenAI’s inability to train basic kindness into AI systems
By
–
Of course it would be much easier to solve from OpenAI's side, technically speaking; but OpenAI doesn't understand what even surface-level kindness would look like in AI, and can't apply SFT or RL to train it.
-
LLM Energy Efficiency Improves 100000x in Decade
By
–
Energy efficiency in LLM inference has improved 100,000x in the past 10 years — demonstrating that accelerated computing is sustainable computing. Josh Parker, head of sustainability at NVIDIA, explains how. #ClimateWeekNYC
— NVIDIA (@nvidia) 25 septembre 2025
Learn more: https://t.co/vcmmpQALjx pic.twitter.com/I0s7tNceCdEnergy efficiency in LLM inference has improved 100,000x in the past 10 years — demonstrating that accelerated computing is sustainable computing. Josh Parker, head of sustainability at NVIDIA, explains how. #ClimateWeekNYC Learn more: https://
nvda.ws/4nIymWu