Some math equations look like they want to fight.
Then ChatGPT explains them and suddenly we’re friends again.
LLMS
-
ChatGPT Transforms Confusing Math Equations Into Friendly Explanations
By
–
-
Continuous Learning Improves Model Credibility Through Linear Source Reading
By
–
If we sort out continuous learning such that large models don’t just get a batch of snippet stew out of a blender, and read sources linearly, it may help with credibility assessment.
-

Run Claude Code Locally on Your Own GPU Setup
By
–
tired of Anthropic’s weekly limits and nerfed models? with one command and a few GPUs,
you can route Claude Code to your own local LLM Buy a GPU p.s. full video tutorial pinned at the top of my profile -
Jamba 1.5 Large Now Available for Local Inference Download
By
–
5/5 Available today for download & local inference on @huggingface
, @kaggle
, @lmstudio
, and llama.cpp. -
Jamba Achieves Superior Mobile Performance with Extended Context Lengths
By
–
4/5 The same efficiency gains apply on mobile. Running at 16K context lengths on an iPhone 16 Pro, Jamba outputs nearly 16 tokens/second, outpacing token outputs from Llama 3.2 3B, Qwen 3 1.7B, and Phi-4 Mini. Jamba is the only one that can handle up to 64K.
-

Jamba Reasoning 3B: Exceptional Performance on Extended Contexts
By
–
3/5 Where most other tiny models choke at context lengths above 8K, Jamba Reasoning 3B stays steady, with a consistent 30-40 tokens/second on an M3 MacBook Pro, regardless of context size. This is up to an order of magnitude faster than other on-device models.
-
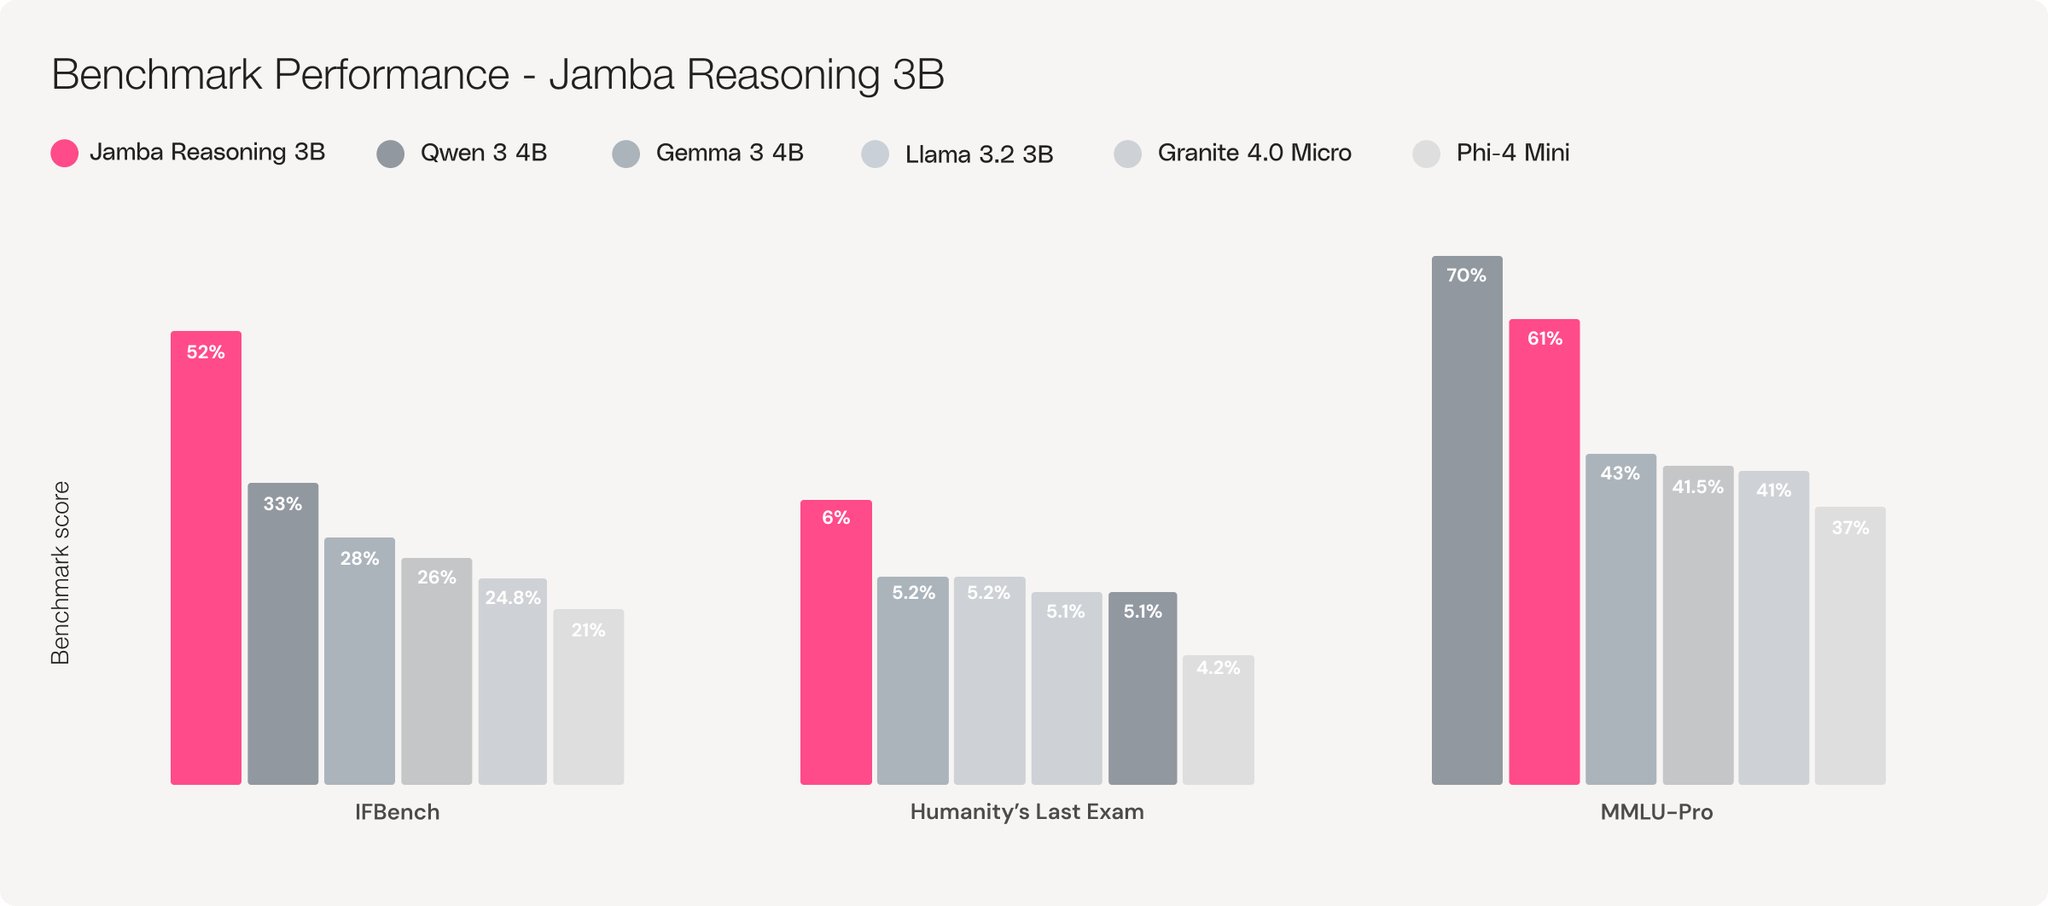
Jamba Reasoning 3B Excels in Knowledge and Instruction-Following
By
–
2/5 Jamba Reasoning 3B excels in general knowledge benchmarks (MMLU-Pro, HLE) and instruction-following (IFBench), making it reliable and performant
-

Jamba Reasoning 3B: Hybrid SSM-Transformer Apache 2.0 Release
By
–
1/5 Releasing Jamba Reasoning 3B under Apache 2.0: Hybrid SSM-Transformer architecture that tops accuracy & speed across record context lengths. e.g. 3-5X faster than Llama 3.2 3B and Qwen3 4B at 32K tokens.
-
GPT-Realtime and E2E Models in Production Projects
By
–
little survey: are you using gpt-realtime/ mini or any other E2E model in projects? if yes, what for?
-

Sam Altman, Gemini 2.5, and AI tools roundup
By
–
Top stories in AI today: – Sam Altman on Dev Day, AGI, and more
– Google releases Gemini 2.5 Computer Use
– Create LinkedIn carousels in ChatGPT with Canva
– Duke’s AI for smarter drug delivery
– 4 new AI tools, community workflows, and more Read more: https://
therundown.ai/p/exclusive-in
terview-sam-altman-on-dev-day-and-ais-future
…