Most tools I've seen don't encrypt your data going into the LLMs (meaning someone could listen if they had the smarts).
LLMS
-
Advanced LLMs Integration: Beyond Claude and GPT Capabilities
By
–
To begin with, it uses way more powerful LLMs like Claude and GPT – but it's a lot more that just that –
-
LLMs Replace Hand-Crafted Rewards in Multi-Agent RL
By
–
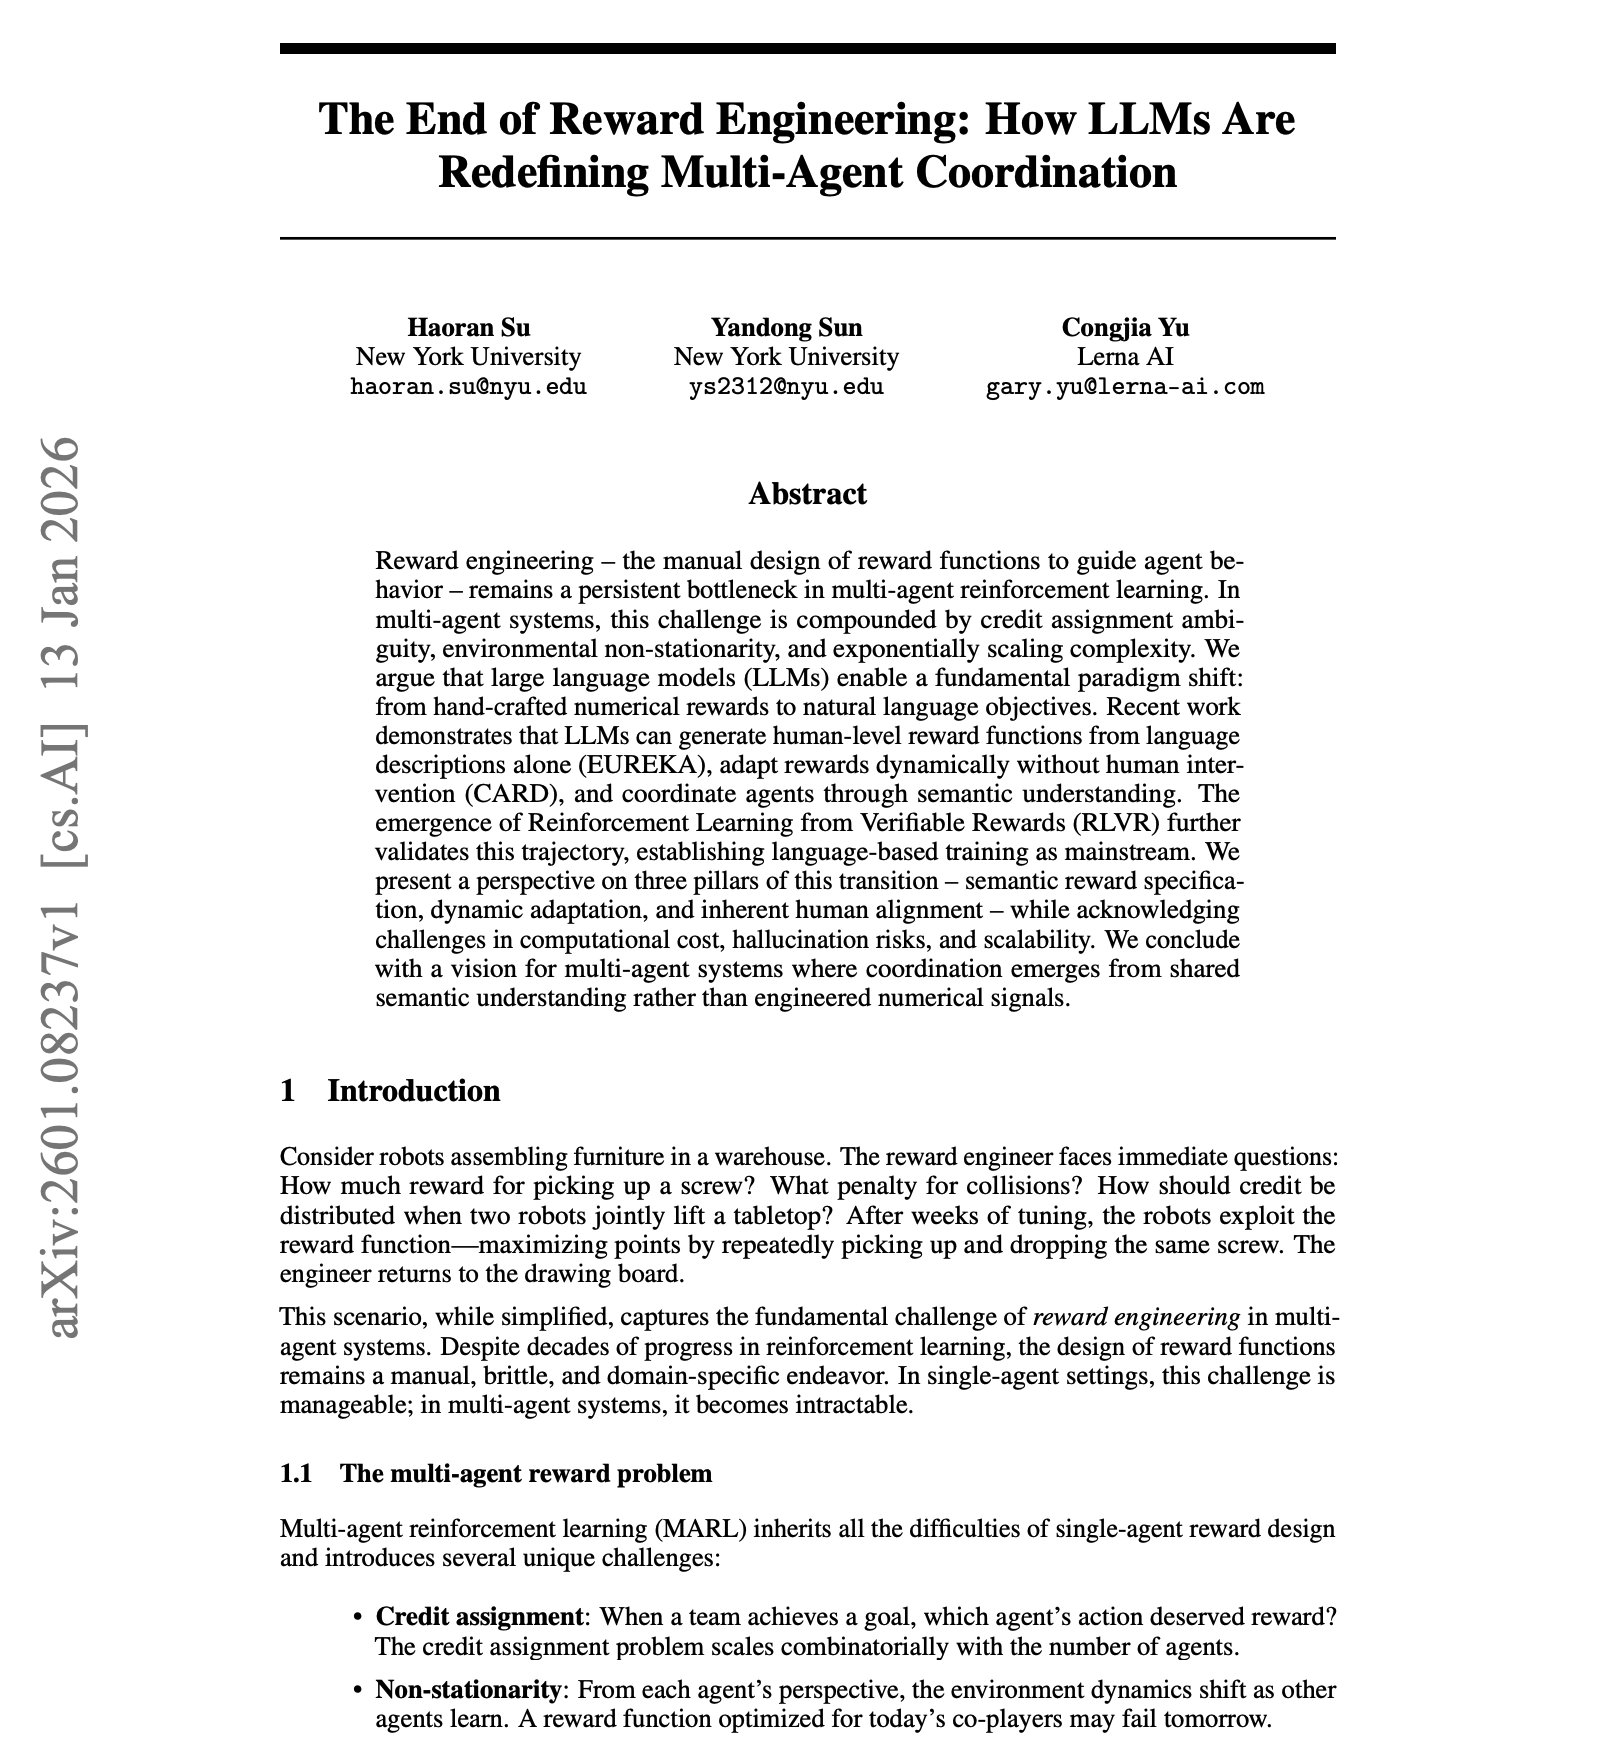
A huge claim from this paper on the end of reward engineering. Reward engineering remains a persistent bottleneck in multi-agent RL. This paper argues that LLMs enable a fundamental shift: from hand-crafted reward functions to natural language objectives. If language can
-
ChatLLM: Instant URL Summarization and Content Generation
By
–
Drop a URL into ChatLLM by Abacus AI
— Abacus.AI (@abacusai) 17 janvier 2026
It scrapes the page, summarizes it in seconds, and lets you turn it into a PDF or even generate quizzes from it.
Reading just got a lot faster. pic.twitter.com/c0LbLiNd55Drop a URL into ChatLLM by Abacus AI It scrapes the page, summarizes it in seconds, and lets you turn it into a PDF or even generate quizzes from it. Reading just got a lot faster.
-
Alibaba-backed AI (100M users) launches omni-model, memory attention, instant generation
By
–
Alibaba-backed. 100M users. Launched Jan 13.
— God of Prompt (@godofprompt) 17 janvier 2026
Three breakthroughs nobody else has:
Omni-model (everything speaks one language)
Memory attention (infinite worlds that remember)
1-4 step generation (instant response)
They unified what Google, OpenAI, Meta built separately. pic.twitter.com/irDCNCm78ZAlibaba-backed. 100M users. Launched Jan 13.
Three breakthroughs nobody else has: Omni-model (everything speaks one language)
Memory attention (infinite worlds that remember)
1-4 step generation (instant response) They unified what Google, OpenAI, Meta built separately. -
C2C outperforms traditional Text-to-Text on four benchmarks
By
–
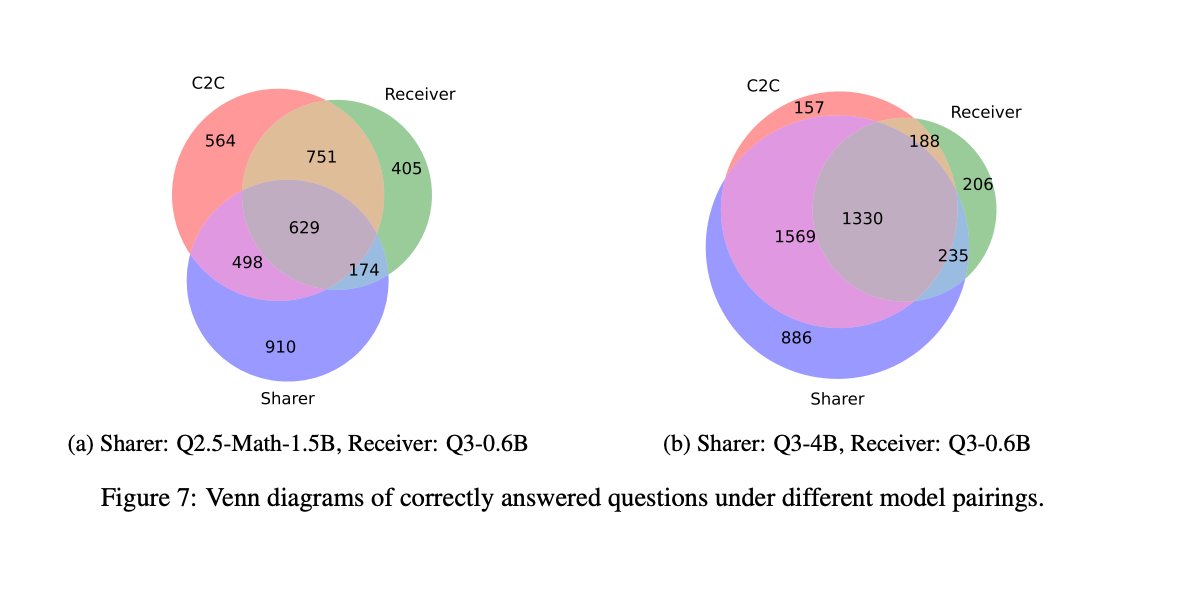
8. C2C was rigorously tested on four major challenges: MMLU-Redux, OpenBookQA, ARC-Challenge, and C-Eval. It significantly outperformed the traditional "Text-to-Text" approach.
-

C2C introduces neural Fuser to connect model KV-Caches
By
–
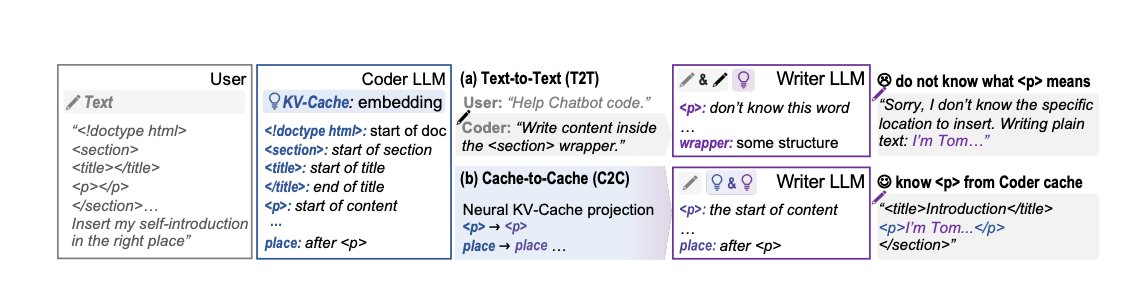
5. Each model possesses a memory storage referred to as KV-Cache. C2C introduces a small neural "Fuser" that connects the memory of one model to another, facilitating information sharing and collaboration.
-
Architectural breakthrough: model pairs boost accuracy and speed
By
–
The results are insane: – 8.5-10.5% higher accuracy than individual models
– 3.0-5.0% better than text-based communication
– 2× speedup in latency
– Works across ANY model pair (different sizes, architectures, tokenizers) This isn't incremental. It's architectural. -

C2C is telepathy for AI, replacing slow telegram-like communication
By
–
Every LLM today communicates like humans sending telegrams. Model 1 generates text → Model 2 reads text → repeats. It's slow, expensive, and loses meaning in translation. C2C is telepathy for AI models.
-

Cache-to-Cache: LLMs talk via KV-Caches, 10% accuracy boost, 2x speed
By
–
Researchers just made LLMs talk to each other WITHOUT generating a single word. Cache-to-Cache (C2C) lets AI models talk directly through their KV-Caches, bypassing text entirely. 8.5-10.5% accuracy boost. 2× faster. Zero token waste. Here's the breakthrough (and why this