
We introduce SP3F: an algorithm to improve LLM reasoning in lower-resource languages (e.g., Indonesian, Bengali, and Swahili), no manual data collection needed! SP3F produces models that out-perform fully post-trained models across multiple tasks and languages🧵 [1/N]
LLMS
-
LobeHub: multi-model, direct API, agent marketplace, 70k GitHub stars
By
–
Claude Cowork: $200/month. One model. macOS only.
Manus: VM-based browsing. Slow. Unstable. Expensive. LobeHub:
→ Multi-model support (switch freely)
→ Direct API access (faster, more accurate)
→ Agent marketplace to discover and remix
→ 70k GitHub stars foundation More -
How AI Chatbot Tools Like Clawdbot Emerge Rapidly
By
–
Wondering how tools like Clawdbot / Moltbot are emerging so quickly?
-
Clawdbot Risk Prevention for Non-Tech
By
–
Prevention message, following the hype:
I dread the moment when clawdbot will leave the circle of geeks.
If "non-tech" people start using it without being aware of security issues, how models work, their limitations, and associated risks. -

Anthropic CEO warns of AI civilizational risks and new tools
By
–
Top stories in AI today: Anthropic CEO on AI’s ‘civilizational’ danger
Anthropic embeds interactive apps inside Claude
Build your own design system for AI
Microsoft's powerful new Maia 200 AI chip
4 new AI tools, community workflows, and more Read more: https://
therundown.ai/p/anthropic-ce
o-confronts-ais-dangers
… -
Now anyone can build n8n agents easily using Claude with this prompt
By
–
Now anybody can build n8n agents easily using Claude with this prompt. loved it.
-

Grassmann model trails in perplexity but leads in SNLI accuracy
By
–
Does it actually work in practice? Wikitext-2 (language modeling): 13M param Grassmann model: 275.7 perplexity
13M param Transformer: 248.4 perplexity
Gap: ~11% behind SNLI (natural language inference): Grassmann head: 85.50% validation accuracy
Transformer head: 85.45% -

Attention quadratic vs Grassmann linear scaling complexity gap
By
–
The complexity story is WILD: Standard attention: O(L²d) – quadratic scaling with sequence length
Grassmann mixing: O(Ld²) – LINEAR scaling (for fixed rank r) This isn't just theoretical. As sequences get longer, the gap becomes exponential. -

Massive attention matrices cause Transformer interpretability crisis
By
–
Here's the interpretability crisis no one talks about: Every Transformer layer creates an L×L attention matrix. Across 96 layers and 96 heads in GPT-4, that's a MASSIVE evolving tensor cloud. The paper proves this is why we can't interpret these models not their size, but their
-
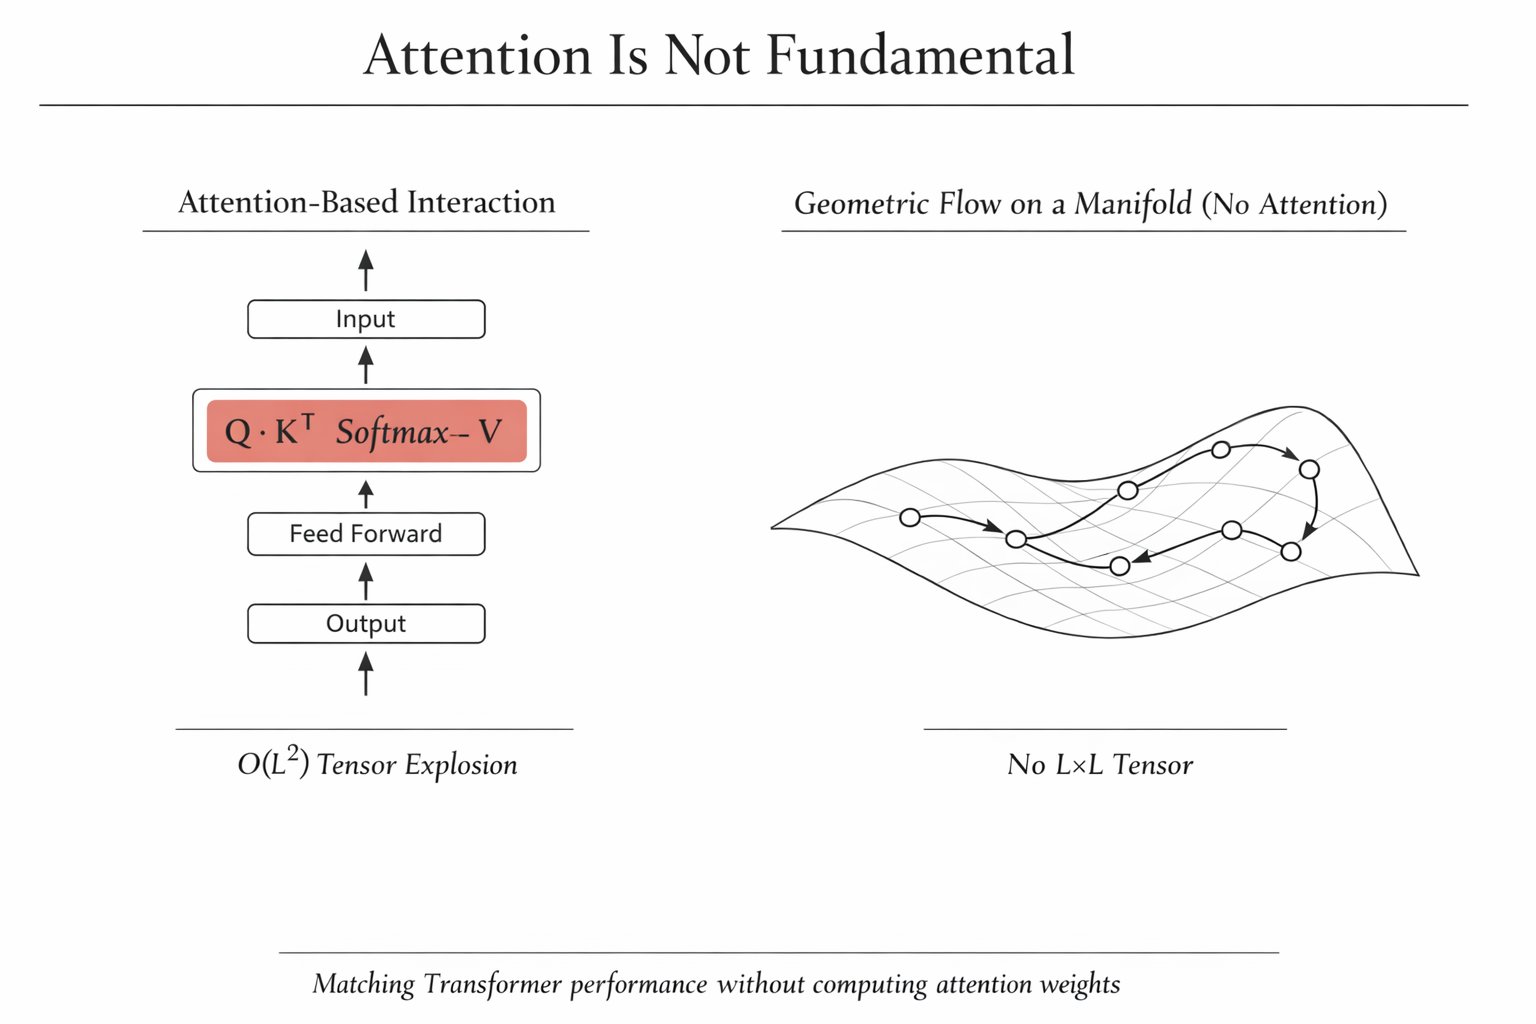
Transformer performance matched without computing attention weights
By
–
This paper just murdered the foundation of every AI model you've ever used. A researcher proved you can match Transformer performance WITHOUT computing a single attention weight. Here's what changed (and why this matters now):