
Arrête de dire à ChatGPT : « corrige mon texte et ma grammaire ». Un prompt mal formulé donne un rendu médiocre, et un texte généré par ChatGPT se repère très vite. Utilise plutôt ces prompts… et regarde la différence [ Ajoutez en signet pour ne pas perdre ! ]
LLMS
-
Using Codex for Code Review and Instruction Following
By
–
would love for you to give codex a try for this, team trained codex to specifically follow instructions and 100% of the code across OpenAI repos is reviewed via it
-
Simulation as reasoning tool for AI behavior over time
By
–
Your framing is important, Linda, because simulation becomes a place to reason about behavior over time, not just to pretrain components.
-
Baichuan AI Achieves State-of-the-Art Results Across Multiple Benchmarks
By
–
SOTA sweep:
HealthBench 65.1 / Hard 44.4 Hallucination 3.5% (lower than ChatGPT) ScanBench all-stations #1: 74.9 / 72.1 / 74.4 -
SPAR, Fact-Aware RL, and Rubric Evolution in AI Training
By
–
Key takeaways:
SPAR: align RL credit to where decisions happen — optimize stage-wise, not via one noisy end reward. Fact-Aware RL: verify atomic claims with retrieval → make hallucination measurable & optimizable
Rubric Evolution: auto-mine & patch adversarial reward hacks. -
Baichuan-M3 Technical Report Released for Clinical Decision Support
By
–
Baichuan-M3 Technical Report is live. Report:
https://
arxiv.org/abs/2602.06570
Models: https://
hf.co/collections/ba
ichuan-inc/baichuan-m3
…
Try: https://
ying.ai
Built for clinical decision support, not trivia QA, optimized on the real outpatient workflow: Inquiry → Lab Testing → Diagnosis →→ -
Optimizing vLLM Deployments: Workload Tuning and Metrics Scaling
By
–
5/5 The takeaway: know your workload, tune your config, scale on metrics that reflect client experience. These lessons apply beyond GRPO – any high-throughput vLLM deployment facing variable load can benefit. Full blog post:
-
Autoscaling by Queue Depth: Beyond GPU Utilization Metrics
By
–
4/5 The horizontal fix: autoscale on queue depth, not GPU utilization 100% GPU = efficiency, not overload. We use vllm:num_requests_waiting to trigger scale-up when the deployment can't keep up with incoming requests.
-
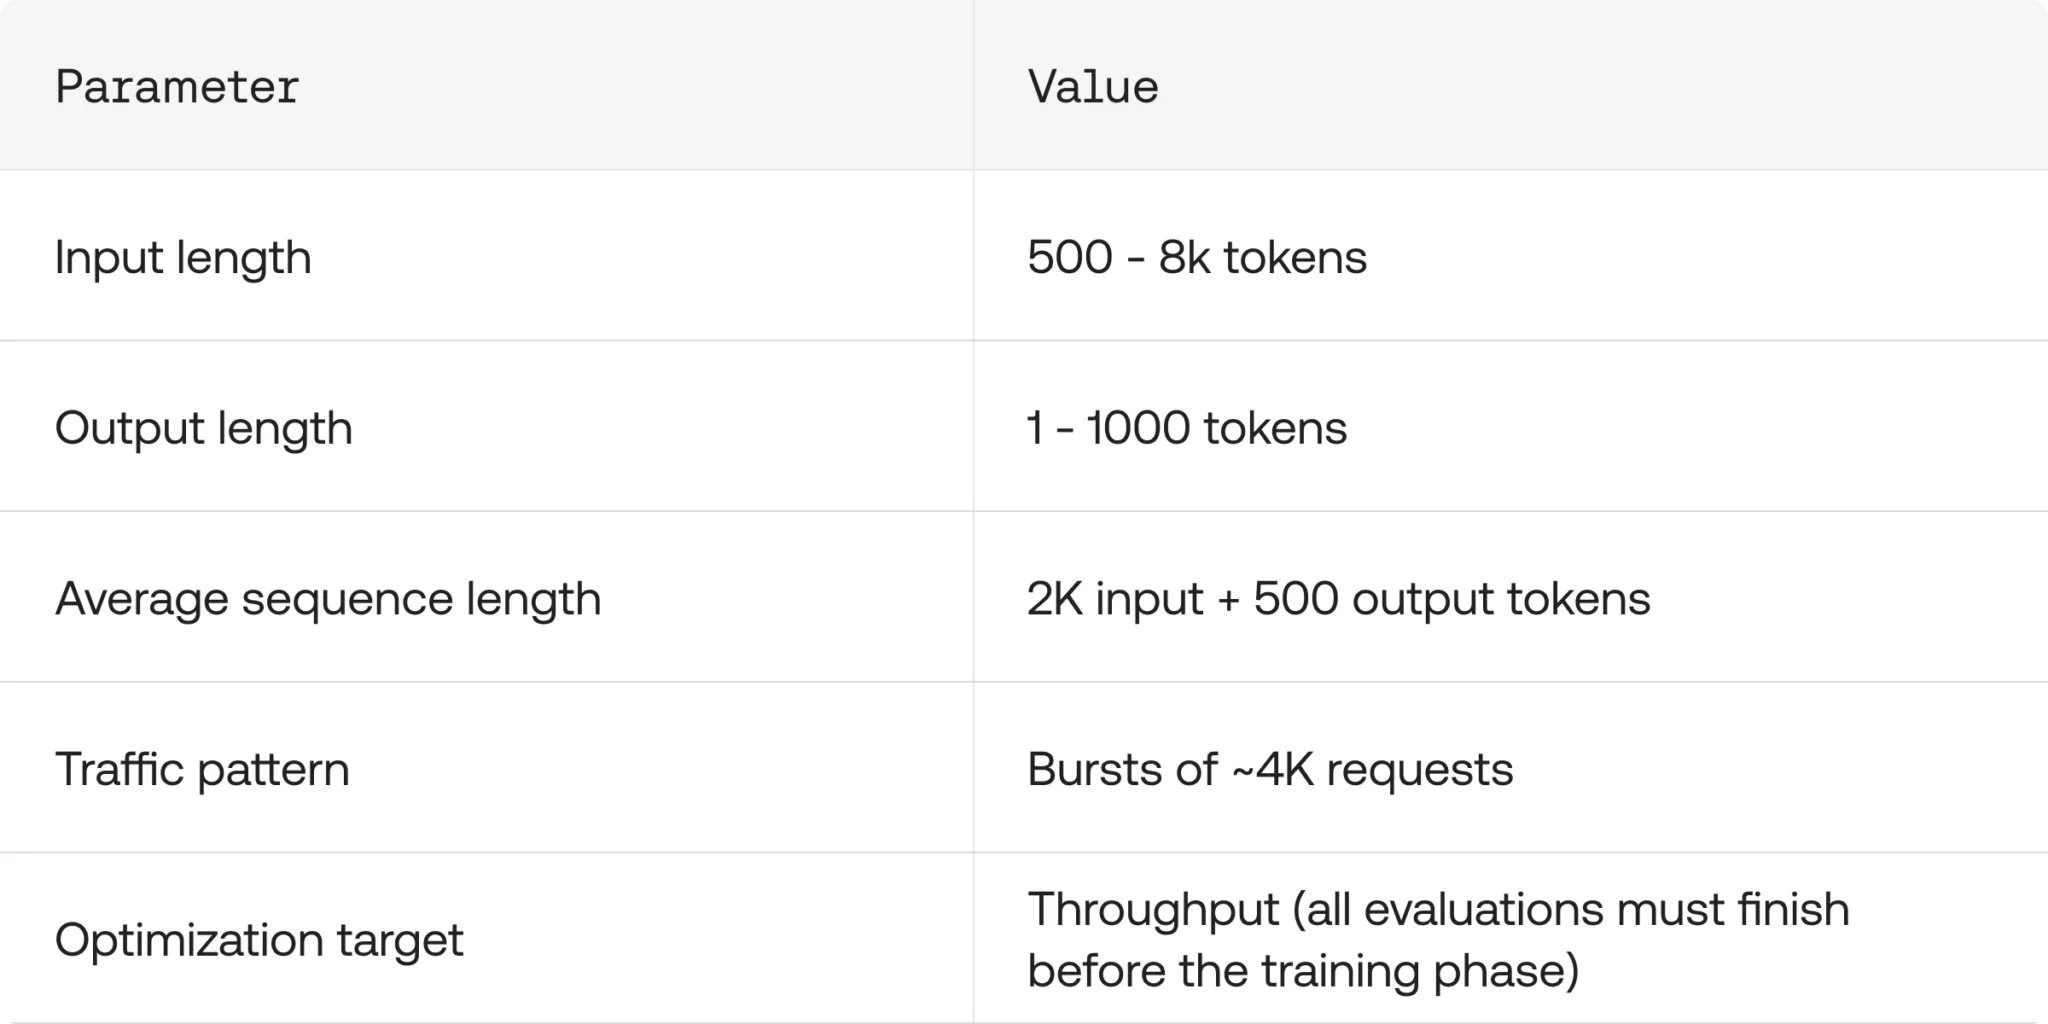
Auto-Tune vLLM Config Doubles Throughput and Halves Latency
By
–
3/5 The vertical fix: auto-tune vLLM config Our old settings were way too conservative. After tuning with Auto-Tune vLLM + GuideLLM we got: ~2× throughput, 2× lower latency, same GPU budget @VLLM @Openshift
-
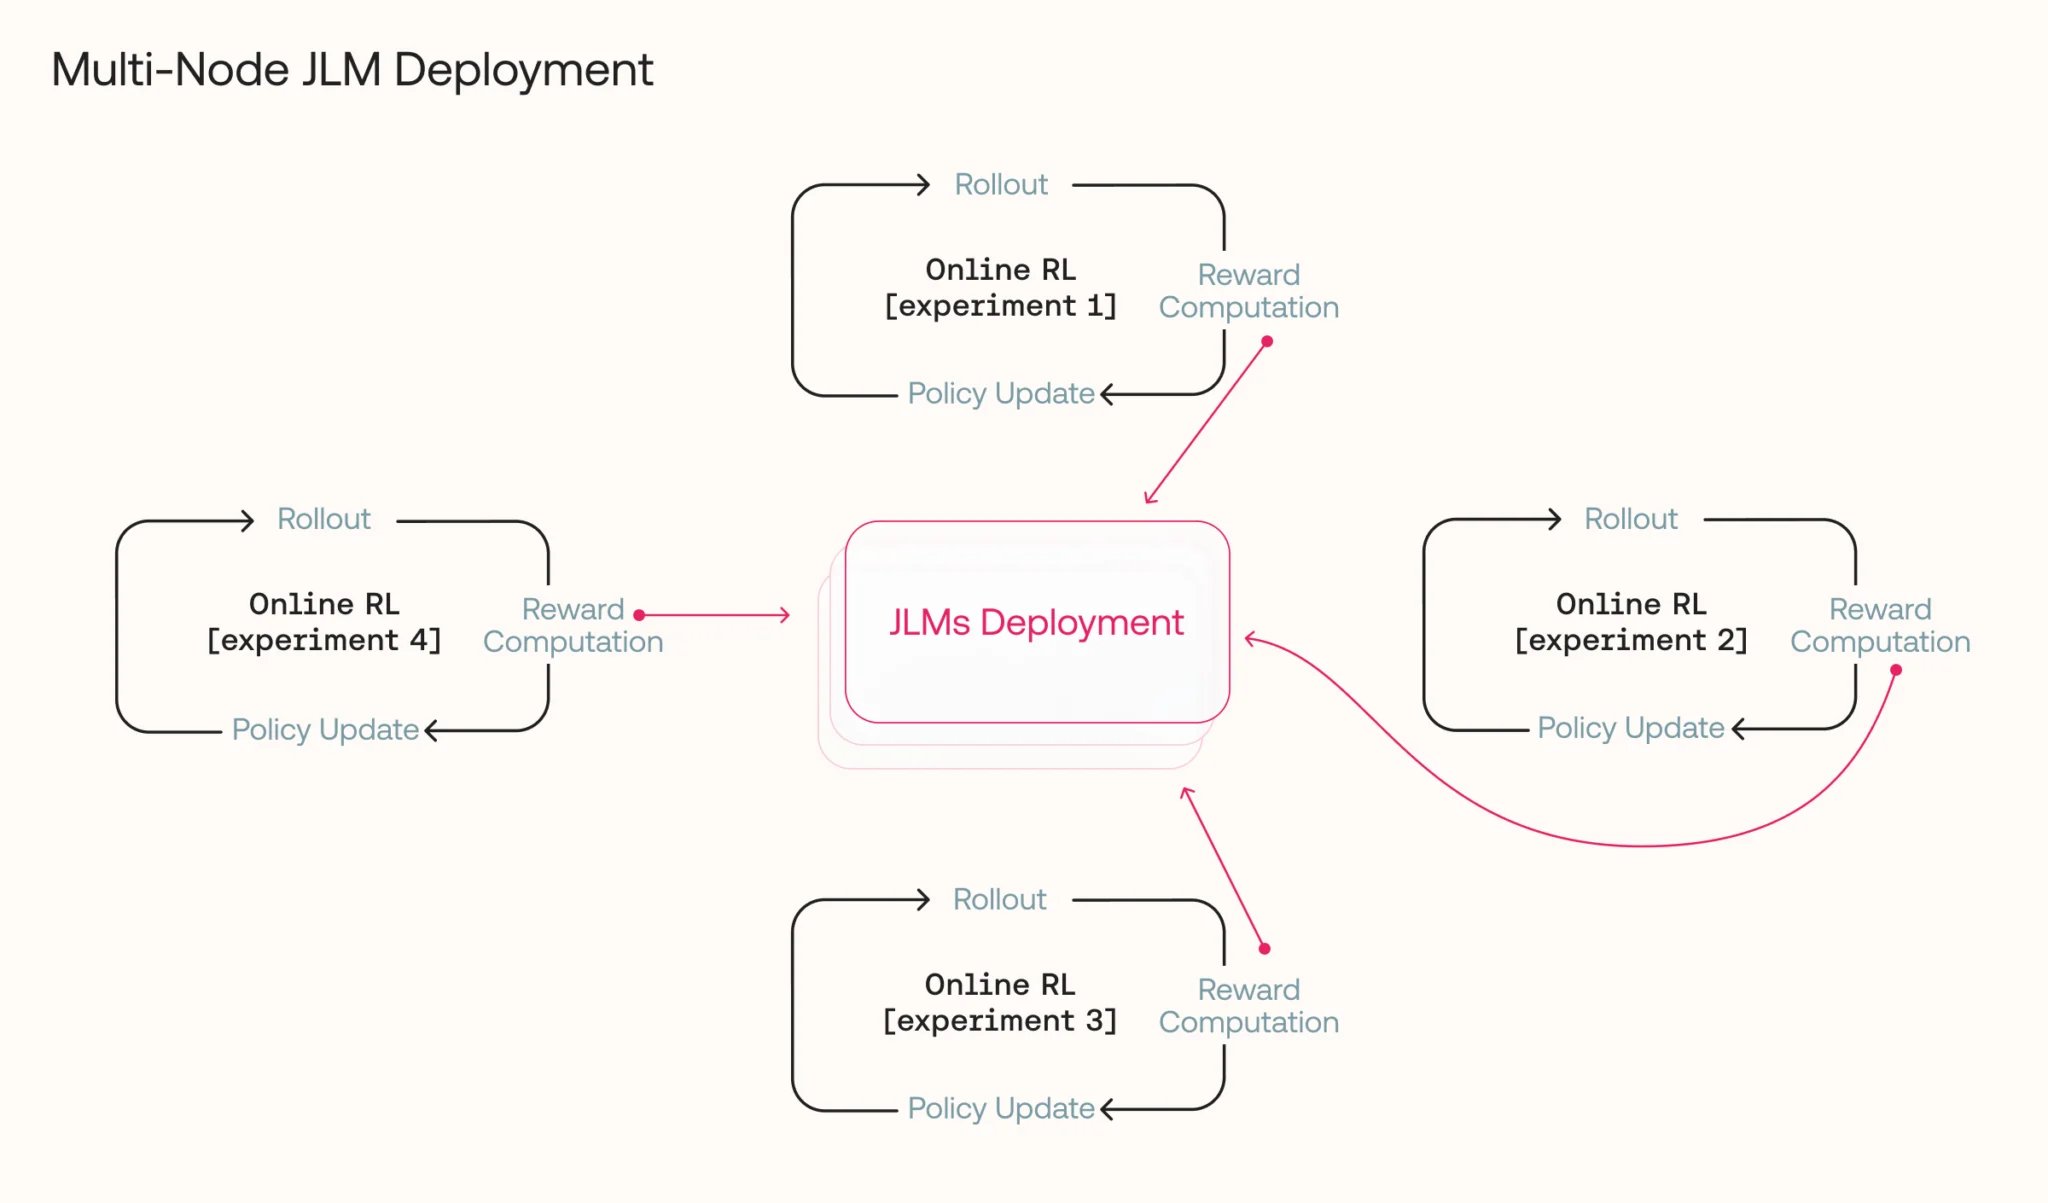
JLM Deployment Sharing Across Multiple Training Jobs for GPU Optimization
By
–
2/5 The setup: JLMs are used only during the reward phase of Online RL, sitting idle the rest of each step. To avoid GPU waste, we shared JLM deployments across multiple training jobs. This improved utilization but exposed JLMs to unpredictable traffic bursts from multiple