The biggest shift is architectural. This is not text routed to a vision model. It is a native multimodal model. → Send base64 images or even videos directly into a chat completion request
→ Reason across text and visuals in the same workflow
→ No fragile orchestration layer
LLMS
-
Native Multimodal Models: Architectural Shift in AI Integration
By
–
-
AI Can Now Write and Publish Books in 48 Hours with Gemini 3.0 Prompts
By
–
L'IA peut maintenant écrire, designer et publier un livre complet en seulement 48 heures. Voici 10 prompts puissants de Gemini 3.0 pour devenir auteur publié ce mois : [ Ajoute en Signet pour ne pas perdre ! ]
-
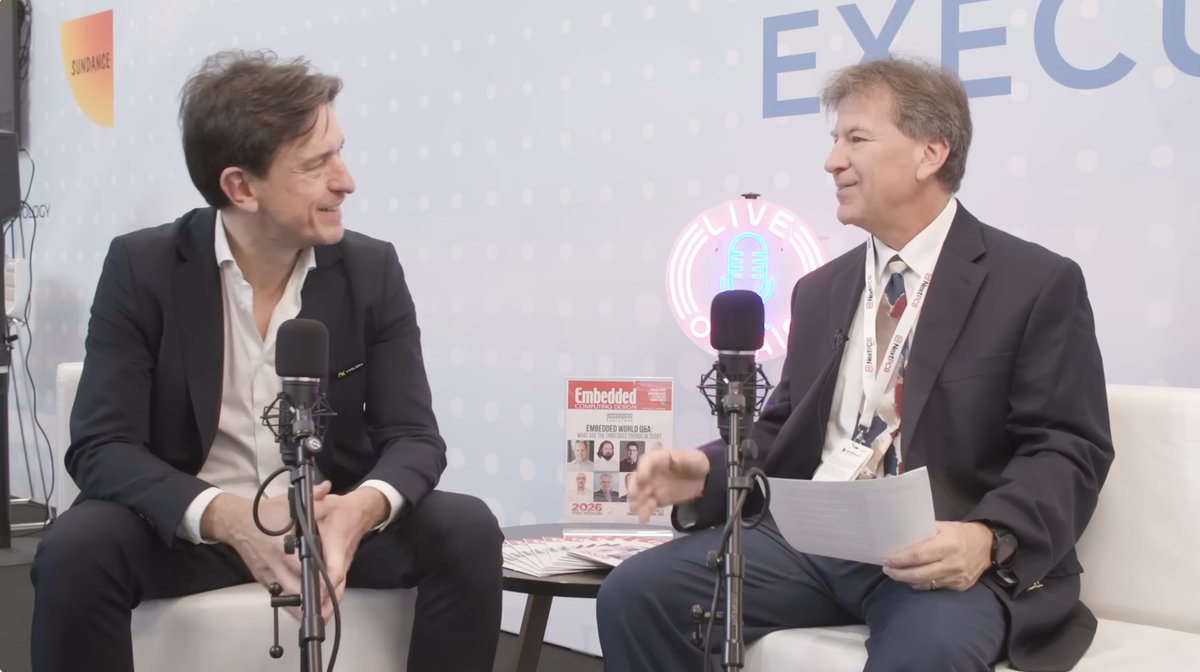
Edge AI Innovation: Metis AIPU and Europa LLM Technology
By
–
At Embedded World 2026, our CEO and co-founder Fabrizio Del Maffeo sat down with Embedded Computing Design to talk about where edge AI is headed and what it actually takes to get there. A few things worth watching for: The dedicated accelerator model. Just as a graphics card handles specialized tasks without burdening the CPU, our AIPUs are purpose-built to run AI workloads efficiently alongside existing processors. No rip and replace, just more capability where you need it. Real-time intelligence at the edge. Physical AI means the machines around us can understand and respond to the world in real time, without a round trip to the cloud. That changes what is possible across industrial, medical, and autonomous systems. Performance that scales. The Metis AIPU delivers 214 TOPS at a fraction of the power and cost of traditional setups, bringing high-performance inference within reach for builders who previously could not justify the tradeoff. What comes next. With Europa on the way, large language models are coming to the edge too. Watch the full conversation here: eu1.hubs.ly/H0sVnCq0 #AxeleraAI #EmbeddedWorld #EdgeAI #PhysicalAI #ComputerVision #Semiconductors
→ View original post on X — @axeleraai, 2026-03-24 07:30 UTC
-
Budget Tokens Parameter Naming Hallucination in AI Responses
By
–
Having said that, the "budgetTokens:0" thing in the response appears to be a hallucination. The correct name of that param is "budget_tokens".
-

Agentic Design Patterns: Building Intelligent Systems Guide
By
–
"Agentic Design Patterns: A Hands-On Guide to Building Intelligent Systems" Read the Online eBook from Google at https://
docs.google.com/document/d/1rs
aK53T3Lg5KoGwvf8ukOUvbELRtH-V0LnOIFDxBryE/mobilebasic?pli=1#heading=h.pxcur8v2qagu
… Buy hardcopy version at http://
amzn.to/3IyOrPx -
AI Models Excel at Breadth But Lack Depth and Creativity
By
–
Current AI models have super human breadth and speed, but lack depth and creativity https://t.co/RDmr0aP87X
— Joscha Bach (@Plinz) 24 mars 2026Current AI models have super human breadth and speed, but lack depth and creativity
-

Complete Guide to Building AI Agents from Zero to Production
By
–
"The Complete Guide to Building AI Agents — From Zero to Production" 51-page PDF — download at https://
linkedin.com/posts/suryakir
an-jose-bb24671bb_ai-activity-7380718746245500928-Huap
… -
Qwen3.5-397B Runs on iPhone with Streaming MoE Weights
By
–
Here's Qwen3.5-397B-A17B- a 397B model – using the streaming MoE weights trick to run on an iPhone! https://t.co/YjBZrUMt9S
— Simon Willison (@simonw) 24 mars 2026Here's Qwen3.5-397B-A17B- a 397B model – using the streaming MoE weights trick to run on an iPhone!
-

AI Model Advancement: 5.4 Integrates Codex with General Purpose Utility
By
–

Dude stop lying It doesn't update the score Brb I have to sleep 😀
-

Running 1T MoE Models on Mac Hardware via Expert Streaming
By
–
Turns out you can run enormous Mixture-of-Experts on Mac hardware without fitting the whole model in RAM by streaming a subset of expert weights from SSD for each generated token – and people keep finding ways to run bigger models Kimi 2.5 is 1T, but only 32B active so fits 96GB