
Claude's use in the USA is no surprise. But apparently, Europe has also developed above-average use of Claude. China lags far behind. At least officially, there is no use of Claude (although we know that distillation was a significant part of its production). Funnily enough:
LLMS
-
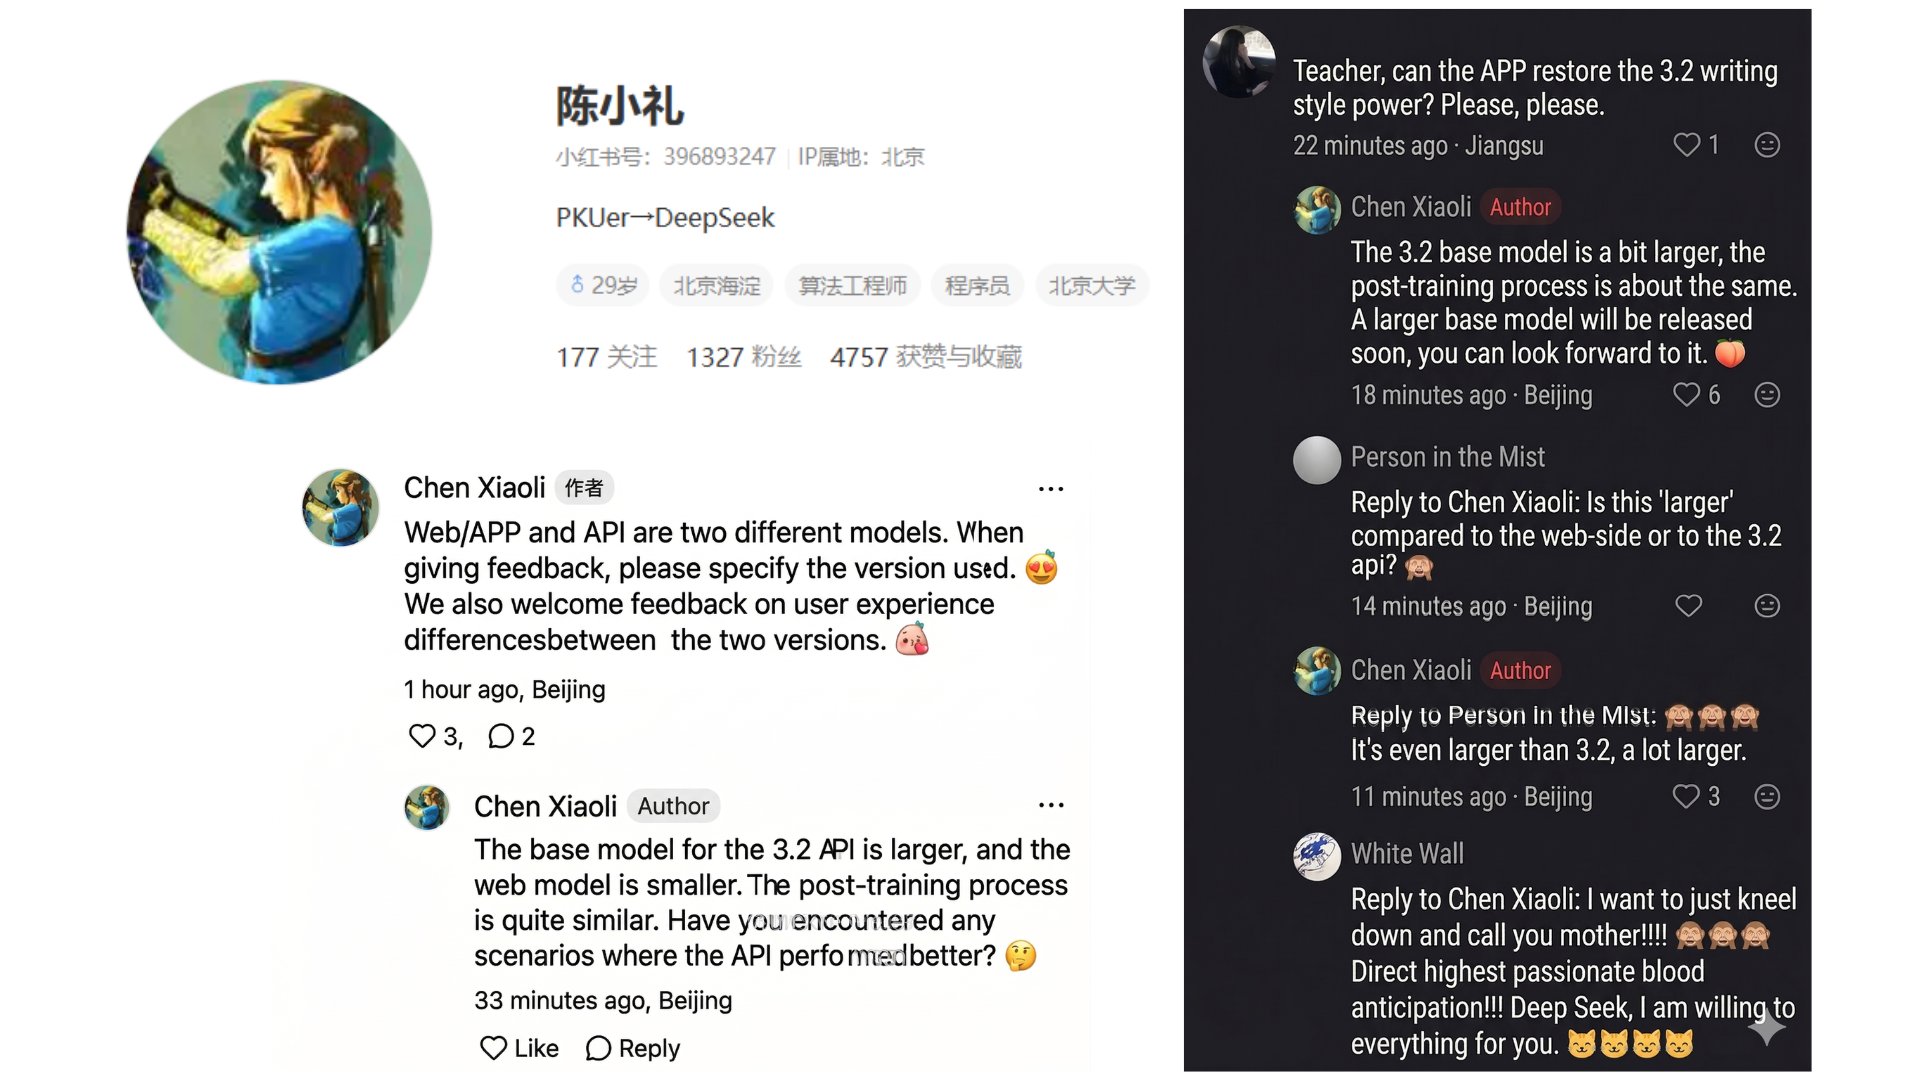
DeepSeek Releases Larger Base Model Amid Training Silence
By
–
"A new, much larger (DeepSeek) base model will be released soon", from DeepSeek staff. I'm currently wondering why there's been so much silence surrounding DeepSeek. The last report stated that they attempted to train on Huawei chips but failed ("DeepSeek AI model failed to
-
Best Model for Actual Machine Learning Work
By
–
For actual ML work it's still the best overall model around.
-
Google’s TurboQuant Algorithm Enables Local Execution of Large LLMs
By
–
Esta es potencialmente la noticia más importante del año.
— SONIA (@S0N_IA_) 25 mars 2026
Google acaba de lanzar TurboQuant. Un algoritmo que hace que los modelos LLM sean más pequeños y rápidos, sin perder calidad.
Esto significa que ahora un Mac Mini de 16 GB puede ejecutar modelos de IA INCREÍBLES.… https://t.co/O271fYGWxUThis is potentially the most important news of the year. Google has just launched TurboQuant. An algorithm that makes LLM models smaller and faster, without losing quality. This means that now a 16 GB Mac Mini can run INCREDIBLE AI models. Completely local, free, and secure.
-
Q-Priming Improves Agent Reliability Through Clarification Requests
By
–
The Q-priming part is really interesting. Making models 5x more likely to ask for clarification instead of guessing wrong is exactly what we need for agentic workflows. Right now most agents just confidently charge ahead with bad assumptions.
-
Distilling Opus reasoning into 27B local model for production
By
–
Distilling Opus reasoning into a 27B model that runs locally is incredible. The fact that tool calling works too makes this actually useful for production, not just benchmarks. Super excited to test its limits 😀
-

Google DeepMind TurboQuant Redefines AI Model Compression Efficiency
By
–
Absolute GAME CHANGER for local AI @GoogleDeepMind
’s new TurboQuant algorithm achieves extreme AI compression, completely redefining model efficiency. Usually, shrinking an AI makes it “dumber.” Not this time. It’s an algorithm that makes LLMs smaller and faster without -

Cohere Partners with RWS Group for Enterprise Translation AI
By
–
We’re excited to announce our partnership with @RWSGroup, bringing Cohere’s frontier AI models to Language Weaver Pro – unlocking new enterprise‑grade translation capabilities. Purpose-built for high-stakes environments, this integration empowers enterprises and governments to communicate seamlessly across languages and accelerate new opportunities for global collaboration and growth! Learn more: rws.com/about/news/2026/lang…
-
Microsoft Spends $8M Super Bowl Ad to Showcase Excel Copilot AI
By
–
Microsoft paid $8 Million for a Super Bowl commercial to show off that Excel now has AI powered by Copilot#microsoft #excel #superbowl #AI #copilot #artificialintelligence #LLM #GenAI@PawlowskiMario @chidambara09 @Ym78200 @CurieuxExplorer @efipm @bigfundu @sayedflah… pic.twitter.com/Zw2eKqKEqc
— Amitav Bhattacharjee (@bamitav) 25 mars 2026Microsoft paid $8 Million for a Super Bowl commercial to show off that Excel now has AI powered by Copilot #microsoft #excel #superbowl #AI #copilot #artificialintelligence #LLM #GenAI @PawlowskiMario @chidambara09 @Ym78200 @CurieuxExplorer @efipm @bigfundu @sayedflah
-

Google TurboQuant Compresses Large Language Models by 6x
By
–
Thats freaking awesome: Google Research has introduced TurboQuant, a compression algorithm (presenting at ICLR 2026) that shrinks the memory footprint of large language models by at least 6x, without any retraining or drop in accuracy. It works by converting data into a polar