I know it sucks. Fundamentally engineering is about tradeoffs, and one of the things we do to serve a lot of customers is optimize the way subscriptions work to serve as many people as possible with the best model. Third party services are not optimized in this way, so it's
INNOVATION
-

Anthropic Copies Open Source Features Then Locks Out Competition
By
–
woke up and my mentions are full of these Both me and @davemorin tried to talk sense into Anthropic, best we managed was delaying this for a week. Funny how timings match up, first they copy some popular features into their closed harness, then they lock out open source.
-
Working on Claude Code improvements, use latest version
By
–
Actively working on making it better. Make sure you're using the latest Claude Code version
-
Automatic Dispensing Robots Modernizing Pharmacies
By
–
How #Automatic Dispensing #Robots Are Modernizing Pharmacies
— Ronald van Loon (@Ronald_vanLoon) 3 avril 2026
by @gigadgets_
#MedTech #HealthTech #Tech #Healthcare #TechForGood pic.twitter.com/T3rg50nAt5How #Automatic Dispensing #Robots Are Modernizing Pharmacies
by @gigadgets_ #MedTech #HealthTech #Tech #Healthcare #TechForGood -
Anthropic Bans The Claw Open Source Models Local Alternative
By
–
Anthropic banning the Claw. Open Source models running locally is the way.
-
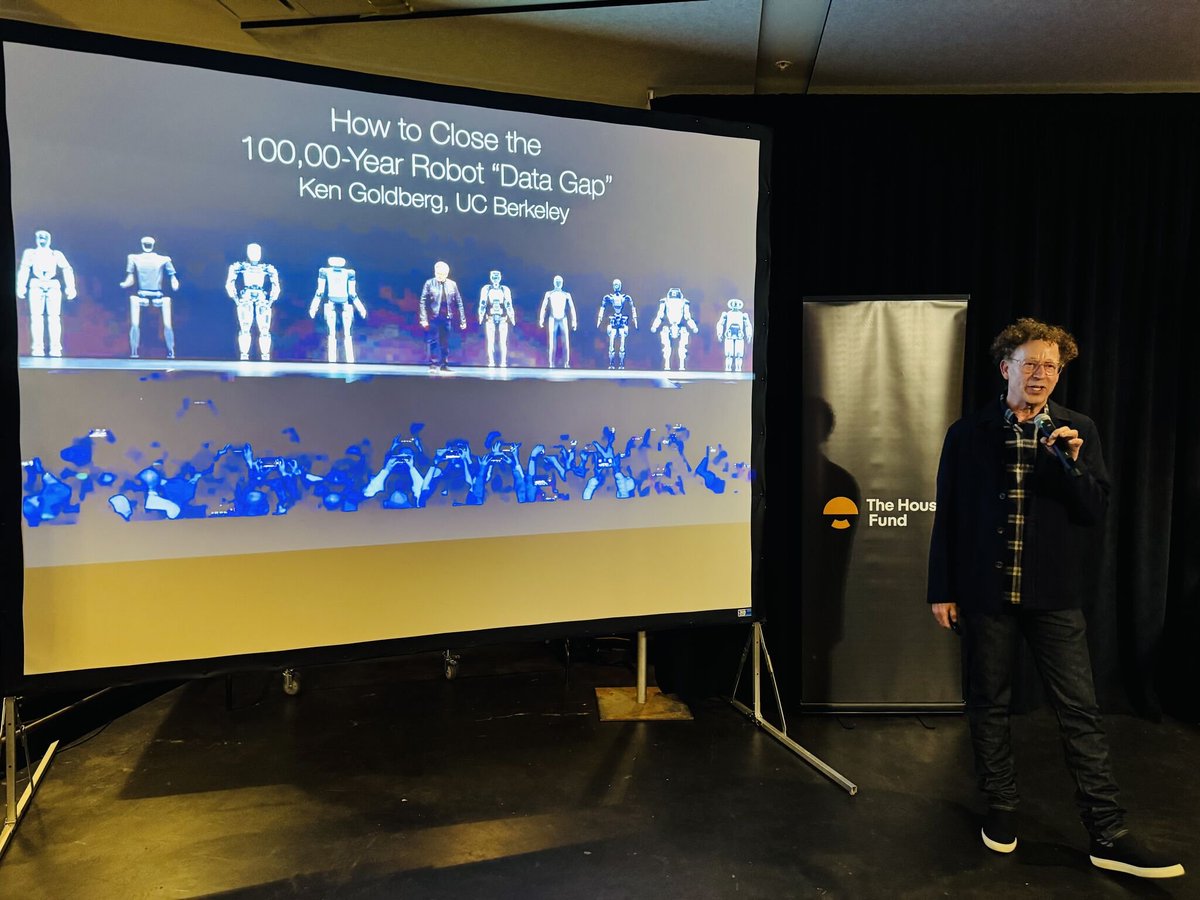
Closing the 100,000-Year Robot Data Gap with Code-as-Policy
By
–


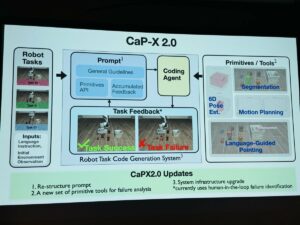
Thank your for this excellent summary Junfan! Junfan Zhu 朱俊帆 (@junfanzhu98) How to Close the 100,000-Year Robot “Data Gap” — @Ken_Goldberg (@UCBerkeley) Goldberg’s core claim: end-to-end Vision-Language-Action (VLA) models aren’t delivering. They’re opaque, hard to debug, and fragile under distribution shift. On LIBERO / LIBERO-PRO, models reach ~100% in-distribution, but tiny pose perturbations collapse success to ~17% or 0% (even π₀). This is systematic overfitting, not generalization. Code-as-Policy (CaP) reframes control: LLMs generate executable programs that call structured primitives (perception, 6D pose, motion planning, grasping). Generalization shifts from weights → code. Benefits: interpretable, verifiable, training-free at inference, debuggable. Open question: reliability. CaP-X (arXiv 2603.22435) introduces a full evaluation stack: 🔷 CaP-Gym: unified REPL over RoboSuite + LIBERO-PRO + BEHAVIOR (tabletop → mobile/bimanual, sim→real) 🔷 CaP-Bench: multi-level abstraction tests 🔷 CaP-Agent0: training-free agent (visual differencing, skill library, parallel queries) 🔷 CaP-RL: verifiable reward RL in Python sandbox Results: under perturbations that break VLAs, CaP-X hits ~96% success with strong pose invariance (extreme corners, lighting, object swaps). LIBERO-PRO (50 trials/task): many 100%, lowest ~76–78%. Failures are mostly semantic (label ambiguity), not control. Grasping/planning ≈ solved. CaP-X 2.0 pushes agentic coding: prompt restructuring, failure-analysis primitives, human-in-loop, reusable cloud skill cache. Test-time loop (no retraining): generate → compile → execute → perturb → diagnose → patch. Extensions include Rust backends (reliability) and Graph-as-Policy (GaP) for node-level verification. Core thesis (GOFE + CaP hybrid): pure VLA scaling cannot close the 100,000-year data gap (robot ≈10K hrs vs LLM ≈1.2B hrs). Robotics needs a Good Old-Fashioned Engineering (GOFE) skeleton: modular pipelines, PID (kp, kv), feedforward (e.g., virtual gravity) — inherently pose-invariant. → Build GOFE backbone + CaP brain. Deploy now, collect real data, spin a flywheel to improve modules and future VLAs. Hot 🔥 takes: 🔷 “Robot generalists should get off their high horse.” VLA-only is dogmatic. 🔷 VLAs may win eventually, but near-term progress requires hybrids. 🔷 Reliability (→99.9%) is the real bottleneck, not demos. Comparison 🔷 GOFE: no generality, but available, interpretable, reliable 🔷 VLA: promised generality, but opaque, brittle, not ready 🔷 CaP: generality + available + interpretable; reliability improves via hybrid + iteration Timeline: near-term: structured tasks (declutter, laundry, delivery). ~5 years: major home logistics gains. Full humanoid generalists: far off. Strategy: specialists first + reliability to 99.9%. Bottom line: don’t wait for end-to-end intelligence. Turn LLMs into super-programmers over a GOFE substrate, deploy hybrids, iterate with real data, and asymptotically approach VLA—without burning out the field. 👉🏻More pics: linkedin.com/posts/junfan-zh… — https://nitter.net/junfanzhu98/status/2039953079706247169#m
→ View original post on X — @ken_goldberg, 2026-04-03 23:15 UTC
-
Ship Fast: Validate Real User Value Over Perfect Planning
By
–
Ship and see if anyone gets value out of what you built. Boil the ocean approaches bug me
-

LangSmith Arrives in New York City
By
–
Had to hop on the wrong train to get this photo, but LANGSMITH IS IN NYC!
→ View original post on X — @langchain, 2026-04-03 23:10 UTC
-
Welcome to OpenAI Team Building Codex
By
–
welcome to the team!! Kath Korevec (@simpsoka) Can’t wait to join the team at @openai building codex. Would love to hear what you love about it or want changed. We’re moving fast. DMs open. — https://nitter.net/simpsoka/status/2040144952550969516#m
-
Demis Hassabis runs Gemma 4 locally on Mac Studio, eliminates token costs
By
–
It’s happened.
— Jesse Genet (@jessegenet) 3 avril 2026
Mac Studio is here. Gemma 4 31b @GoogleDeepMind installed, chatting with my main @openclaw for $0 in token expenses now…
I've burned $5-6k on tokens on my crazy ideas over past few months, so this mac studio should pencil out for me within 3 months or so 🤓 pic.twitter.com/OV3ebyprVdIt’s happened. Mac Studio is here. Gemma 4 31b @GoogleDeepMind installed, chatting with my main @openclaw for $0 in token expenses now… I've burned $5-6k on tokens on my crazy ideas over past few months, so this mac studio should pencil out for me within 3 months or so 🤓
→ View original post on X — @demishassabis, 2026-04-03 23:08 UTC