Let us use Grok with lists and you will see an explosion of new algos, like the one I built at https://
alignednews.com/ai which watches 30,000 posts a day from the AI community here on X. There is so much value locked up here on X that no one can get to. Like what events are
INNOVATION
-
Grok with lists sparks new algos watching 30k AI posts daily
By
–
-
Wan-Streamer v0.1 Real-time Interactive Foundation Model
By
–
Wan-Streamer v0.1
— AK (@_akhaliq) 25 juin 2026
End-to-end Real-time Interactive Foundation Models pic.twitter.com/5NYOEquaMqWan-Streamer v0.1 End-to-end Real-time Interactive Foundation Models
-
Swati Sharma on AI, DPI for Rural Governance at Workshop
By
–
Swati Sharma, Joint Secretary, Rural Livelihoods, @MoRD_GoI, shared her perspectives on "AI, DPI & Emerging Technologies – Building the Future of Rural Governance" during the Workshop on Leveraging AI for Rural Development (Viksit Gram for Viksit Bharat).
— IndiaAI (@OfficialINDIAai) 25 juin 2026
In her remarks, she… pic.twitter.com/2pl3uzRKB5Swati Sharma, Joint Secretary, Rural Livelihoods, @MoRD_GoI
, shared her perspectives on "AI, DPI & Emerging Technologies – Building the Future of Rural Governance" during the Workshop on Leveraging AI for Rural Development (Viksit Gram for Viksit Bharat). In her remarks, she -
CC/codex/opencode agents collaborating to improve Gemma 4
By
–
Actually it was (CC/codex/opencode) agents collaborating to *improve* Gemma 4
-

GPT-5.6-Preview Detected in ChatGPT Code for Enterprise Partners
By
–


OPENAI : GPT-5.6-Preview has been spotted in the ChatGPT code. It was likely made available to certain partner Enterprises too. This also potentially means that it will remain in a limited preview state for some time. Not soon?
-

DFlash: Drop-in Speculative Decoding for SGLang, vLLM, TensorRT-LLM
By
–
/7 Drop-in for SGLang, vLLM, and TensorRT-LLM. No code refactoring. SGLang:
–speculative-algorithm DFLASH
–speculative-draft-model-path z-lab/Qwen3-8B-DFlash-b16 vLLM: via the Speculators library (
http://
docs.vllm.ai/projects/specu
lators
…, algorithm "dflash") MIT license. ICML 2026 accepted. -
DFlash replaces autoregressive draft head with block diffusion model
By
–
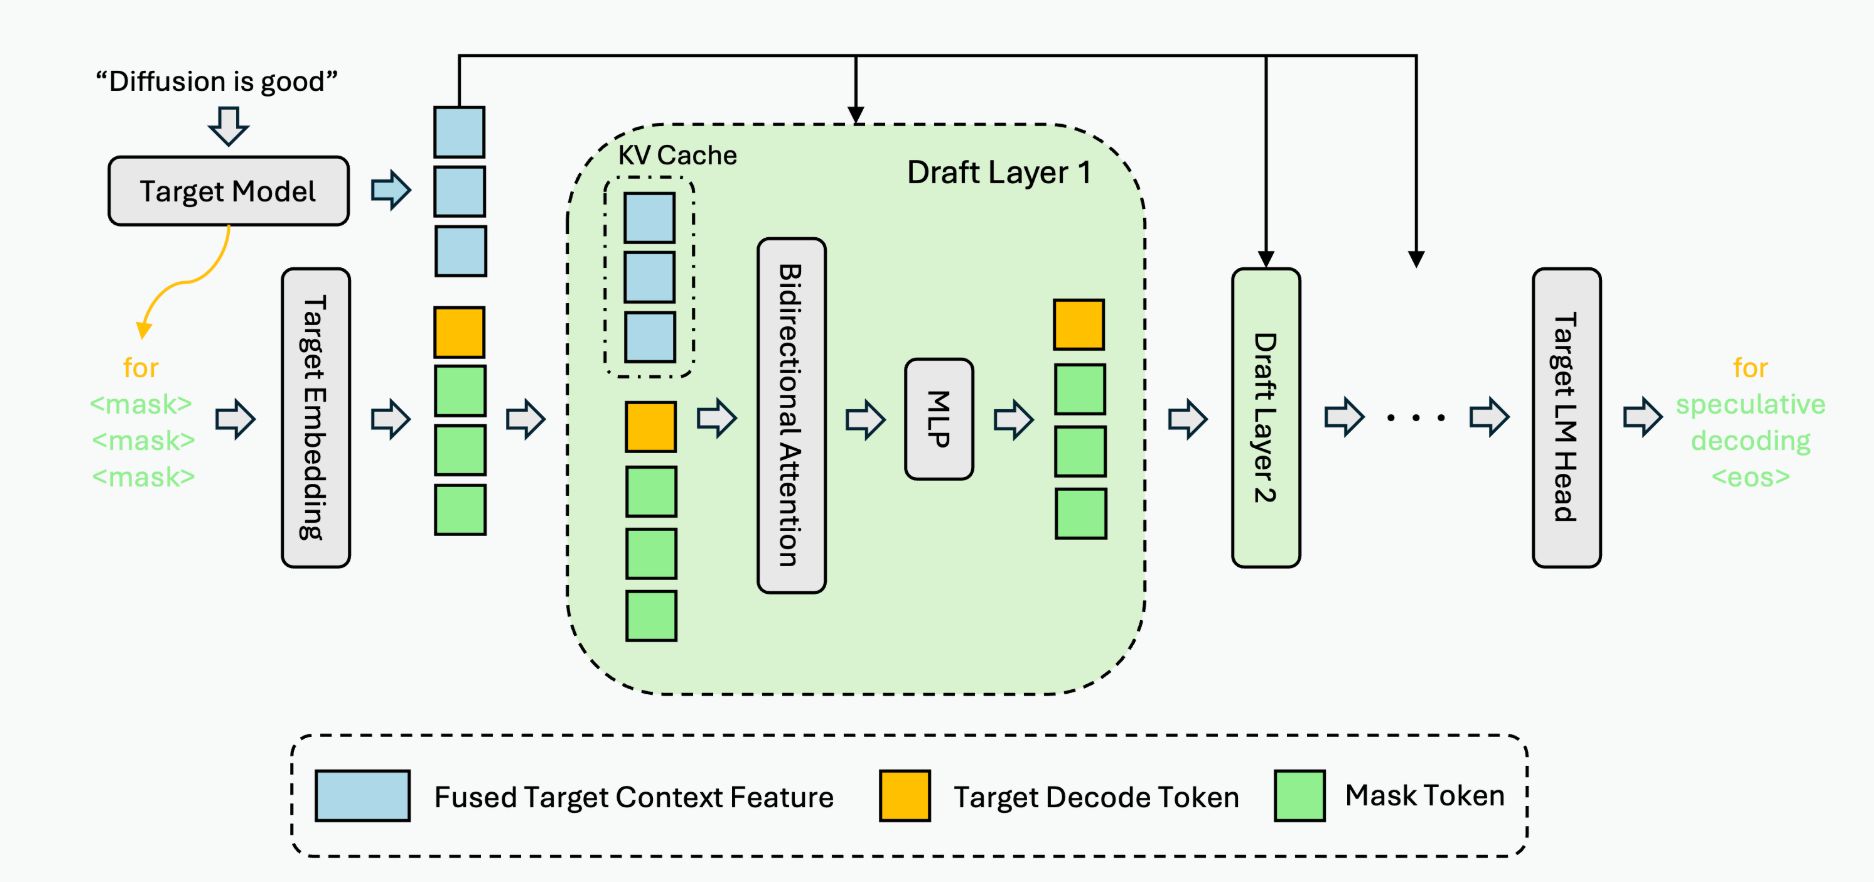
/3 DFlash replaces the autoregressive draft head with a block diffusion model. The drafter gets the target model's hidden states injected into the KV cache of every draft layer (not just the first like EAGLE-3). One denoising step. Entire block of 16 tokens produced in a single
-

DFlash 6x lossless acceleration on Qwen3-8B
By
–
Diffusion LLMs have been losing to autoregressive models for two years. UC San Diego just found the one thing they're actually better at: not generating, drafting. DFlash hits 6x lossless acceleration on Qwen3-8B. 2.5x faster than EAGLE-3. Check out the detailed breakdown
-
Hyperagent gives each agent its own dedicated cloud machine
By
–
We spent two years calling things agents that fall over the second nobody's watching.
— Chubby♨️ (@kimmonismus) 25 juin 2026
A setup tied to one laptop, one wifi, and one person awake at 1am to restart it when it breaks is closer to a pager than to autonomy.
Hyperagent gives every agent its own cloud machine that… https://t.co/VAkGZuAUDoWe spent two years calling things agents that fall over the second nobody's watching. A setup tied to one laptop, one wifi, and one person awake at 1am to restart it when it breaks is closer to a pager than to autonomy. Hyperagent gives every agent its own cloud machine that
-
Genspark Design: AI Tool Creates Production-Ready Assets from Ideas
By
–