Education and fitness in them is 10x the 2D screens we all use.
INNOVATION
-
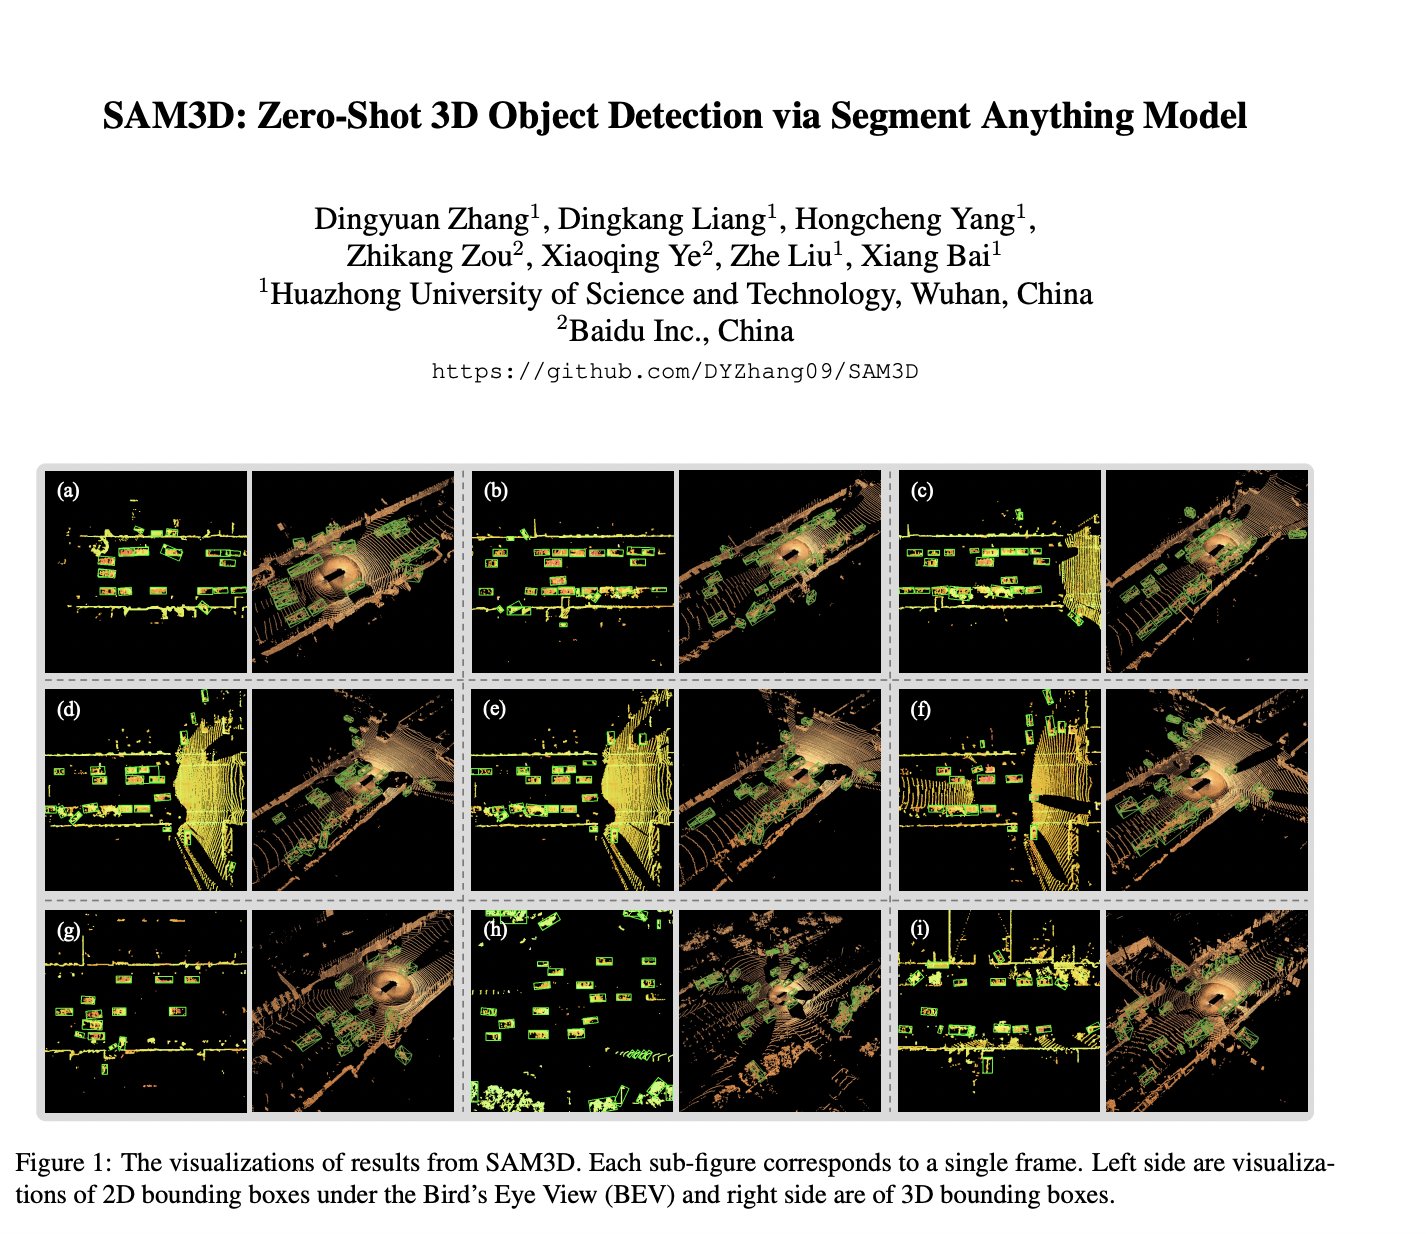
SAM3D: Zero-Shot 3D Object Detection via Segment Anything Model
By
–
SAM3D: Zero-Shot 3D Object Detection via Segment Anything Model paper page: https://
huggingface.co/papers/2306.02
245
… With the development of large language models, many remarkable linguistic systems like ChatGPT have thrived and achieved astonishing success on many tasks, showing the incredible -
Intelligent Automation Newsletter: AI Making World More Human
By
–
Intelligent Automation Newsletter #123 The latest news and insights on how Artificial Intelligence & Automation make our world more Human. Enjoy the read! https://
linkedin.com/pulse/intellig
ent-automation-newsletter-123-pascal-bornet
… #intelligentautomation -
AI-Powered Comics: Storytelling Through Endless Paper Innovation
By
–
Bringing storytelling to another (infinite) level
— Pascal Bornet (@pascal_bornet) 6 juin 2023
A mesmerizing scene pushing the boundaries of space and time, taking us on a journey through the infinite human imagination
A creative work by Greg Edwards, using Endless Paper #creativity #comics #innovation #tech pic.twitter.com/joY6XUe3JUBringing storytelling to another (infinite) level A mesmerizing scene pushing the boundaries of space and time, taking us on a journey through the infinite human imagination A creative work by Greg Edwards, using Endless Paper #creativity #comics #innovation #tech
-
Most interesting Vicuna implementations shared by community
By
–
What’s the most interesting implementation of vicuna you’ve seen so far? DMs open
-
Probabilistic Adaptation of Text-to-Video Models for High-Fidelity Generation
By
–
Probabilistic Adaptation of Text-to-Video Models
— AK (@_akhaliq) 6 juin 2023
paper page: https://t.co/pGlGHjrDpG
Large text-to-video models trained on internet-scale data have demonstrated exceptional capabilities in generating high-fidelity videos from arbitrary textual descriptions. However, adapting… pic.twitter.com/nzfYbWLflPProbabilistic Adaptation of Text-to-Video Models paper page: https://
huggingface.co/papers/2306.01
872
… Large text-to-video models trained on internet-scale data have demonstrated exceptional capabilities in generating high-fidelity videos from arbitrary textual descriptions. However, adapting -
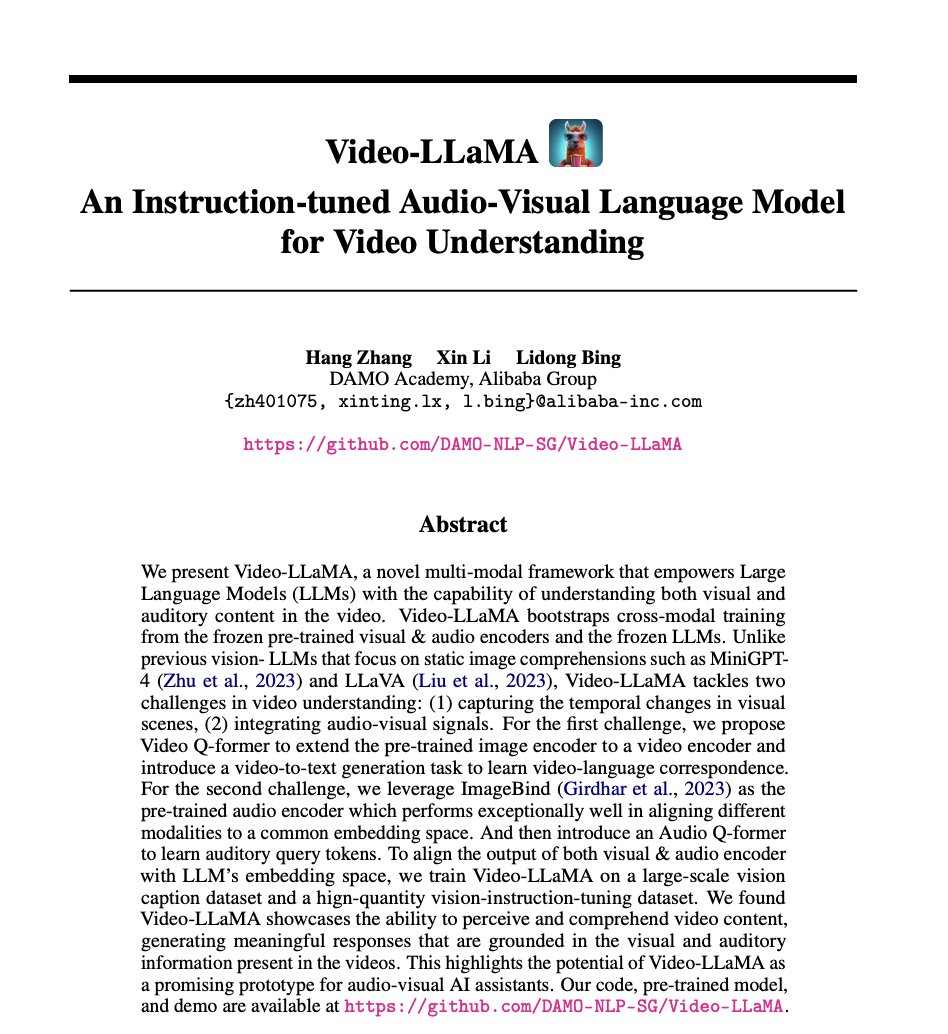
Video-LLaMA: Multi-modal Framework for Audio-Visual Understanding
By
–
-LLaMA: An Instruction-tuned Audio-Visual Language Model for Understanding paper page: https://
huggingface.co/papers/2306.02
858
… present Video-LLaMA, a multi-modal framework that empowers Large Language Models (LLMs) with the capability of understanding both visual and auditory -
Apple Delivers on Yesterday’s Announcements
By
–
Everything we talked about yesterday Apple delivered.
-

Quantum Computing Challenges Alongside AI Regulation Efforts
By
–
As we work to regulate artificial intelligence, it's critical that we not lose sight of the profound potential of quantum computing. This disruptive technology, if it lives up to its projected potential, is likely to present a complex set of challenges. Microblog @antgrasso
-

Returning to AI focus next year
By
–
Back to AI until next year. 🙂 https://t.co/P6lZcsgXsC
— Robert Scoble (@Scobleizer) 6 juin 2023Back to AI until next year. 🙂