Mes prévisions pour 2026 1 L’Europe va prendre conscience de son immense retard technologique et de sa colonisation mais elle sera incapable d’agir : à Bruxelles il y a des juristes et des bureaucrates mais aucun entrepreneur ! 2 L’Education Nationale et l’Université vont être
INNOVATION
-
AI tools collaboration in future orgs
By
–
I have Jules, Codex, Cursor and Claude Code working together on my team. All of them will have a job in AI-first orgs soon
-
Goodbot3: Proactive AI Gaming Assistant with Expert Advice
By
–
I have totally different vision for Goodbot3. It should be pro-active assistant, who understand your game context, and can give you good advice, like an experienced player/friend. Our old Goodbot was nothing like this, that was old AI 🙂
-

Exploring AI Layers: Neural Networks and Deep Learning Fundamentals
By
–
Peeling back the layers of AI! This infographic unravels the complex world from Neural Networks to Deep Learning. Dive deeper into AI with the insights from @ingliguori
's 'The Digital Edge' http://
bit.ly/3u4pILl #ArtificialIntelligence #MachineLearning #DeepLearning -
Agent stacks outperform single models
By
–
Banger thread. Single-model supremacy is dead – the real alpha is in these purpose-built agent stacks that actually ship value instead of just flexing parameter counts. MoE routing + hierarchical planning + action-oriented LAMs is the stack that's quietly eating the world right
-
Testing Advanced Technology on Complex Features Goodbot3
By
–
I don't know yet, I must try it on something more complex and bigger, e.g. the full Goodbot3 feature. But this is already amazing! I wonder what modders can do with this.
-
Vibe Coding vs Manual Coding: Which Approach for AI Development?
By
–
Great! Are you vibe coding it or coding manually?
-
MoE: From Niche to Industry Standard by 2025
By
–
Mixture of Experts went from academic curiosity (1991) → impossible to scale (2000s) → production breakthrough (2021) → industry standard (2025). Dense models are becoming legacy infrastructure. If you're building AI in 2025 and not considering MoE, you're overpaying by 10x.
-
Next-Gen MoE Innovations in 2026
By
–
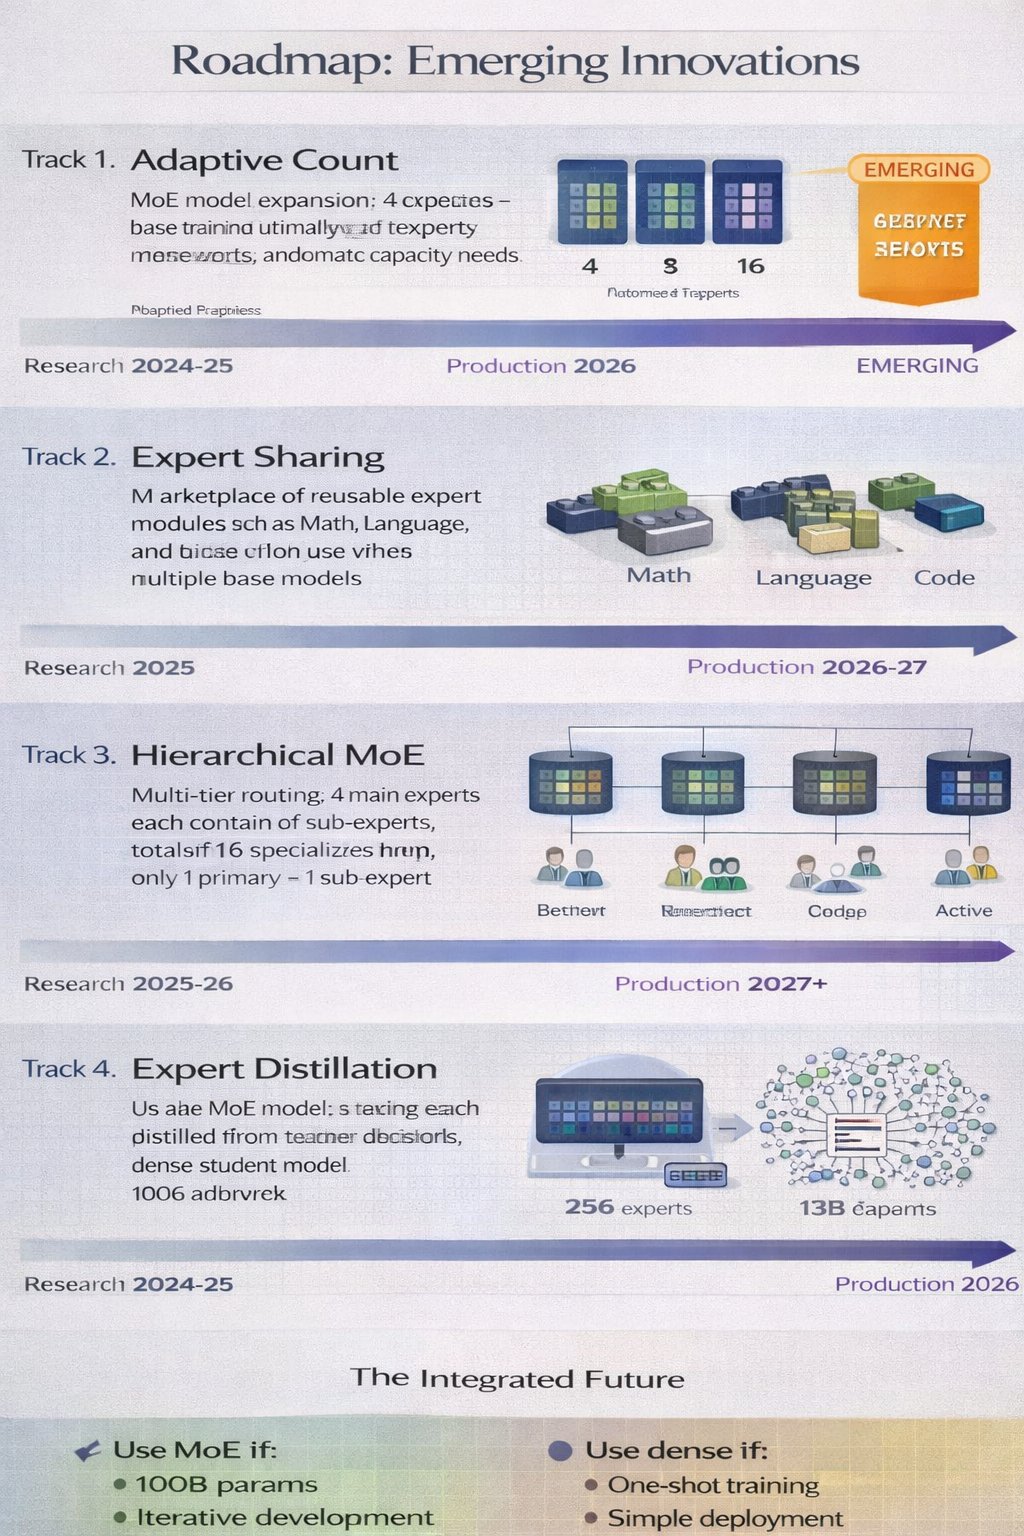
What's coming next: → Adaptive expert count (dynamically add/remove experts during training)
→ Cross-model expert sharing (reuse specialists across different models)
→ Hierarchical MoE (experts that route to sub-experts)
→ Expert distillation (compress MoE knowledge back -
Tradeoffs of modular AI architecture
By
–
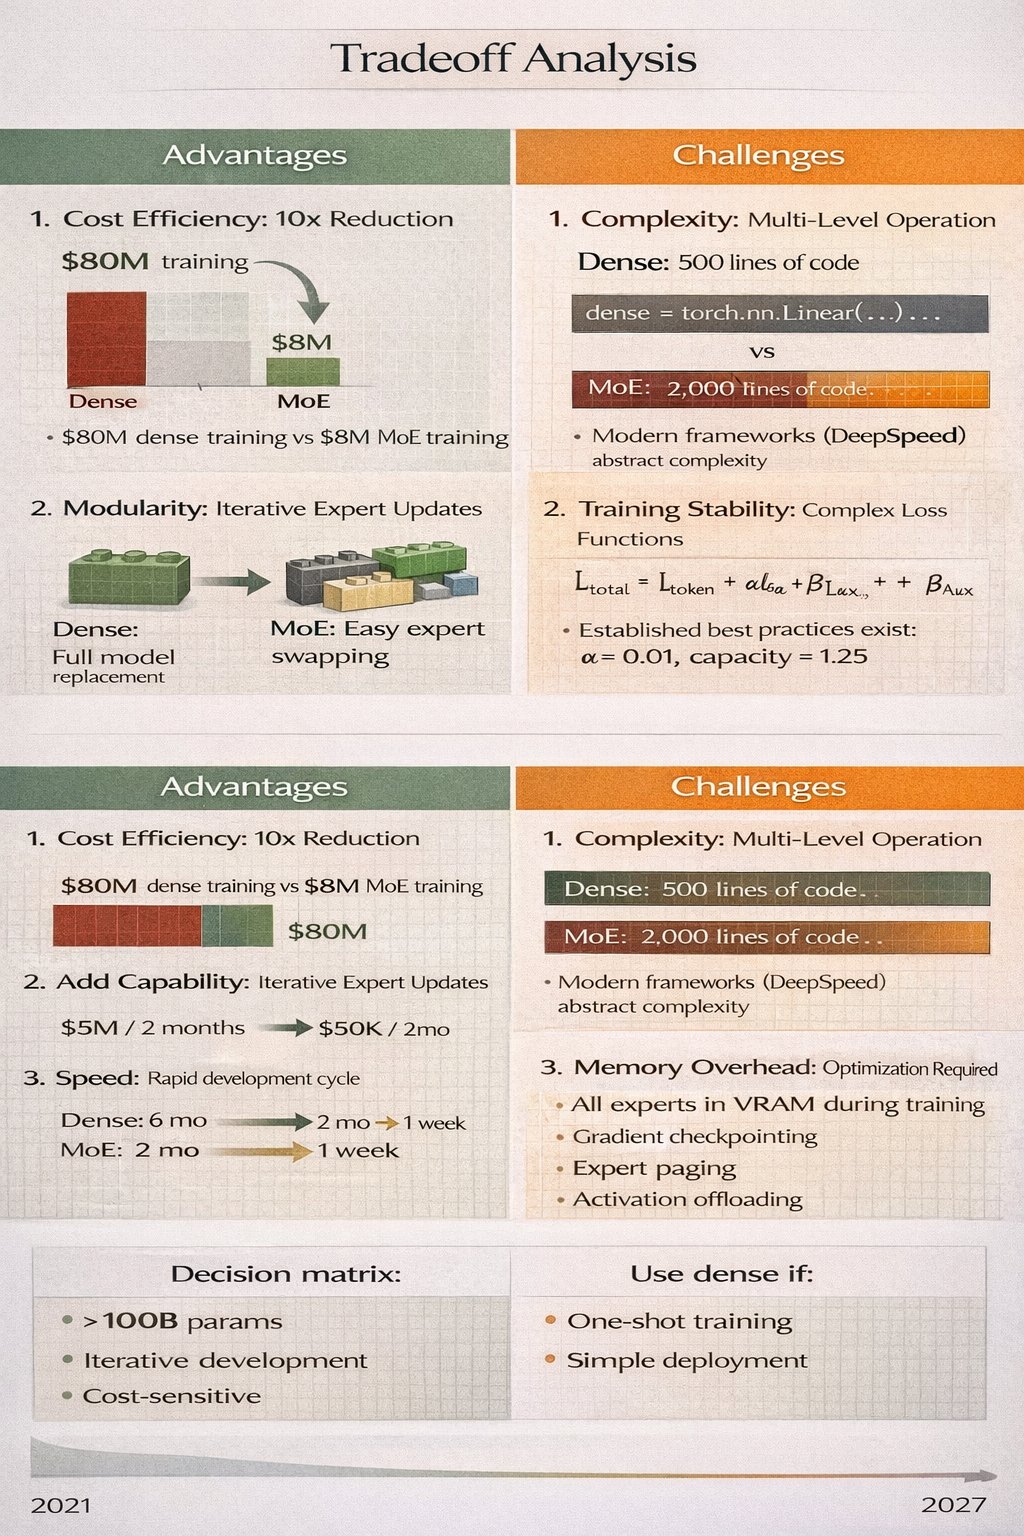
The tradeoffs are real though: 5-10x cheaper training and inference Modular, composable architecture Faster iteration cycles More complex to implement correctly Requires load balancing during training Higher memory overhead (all experts must fit in VRAM during