Run FLUX.2 [klein] on Replicate now:
INNOVATION
-
Replicate and Pruna AI Optimize Processing Speeds
By
–
We've worked with @PrunaAI again to deliver you the fastest speeds possible
-
FLUX.2 Klein: Fast Compact Image Generation Model Released
By
–
FLUX.2 [klein] is here A compact, lightning-fast image model from @bfl_ml Generate 1MP images in ~500ms or 4MP in under 2s. Supports image-to-image and precise editing with up to 5 input images.
-
How soon will AI coding bots build an entire OS?
By
–
How long before someone uses AI coding bots to build a whole OS from scratch?
-
Autonomous Memory Management in LLM Agents
By
–
Autonomous Memory Management in LLM Agents LLM agents struggle with long-horizon tasks due to context bloat. As interaction history grows, computational costs explode, latency increases, and reasoning degrades from distraction by irrelevant past errors. The standard approach
-
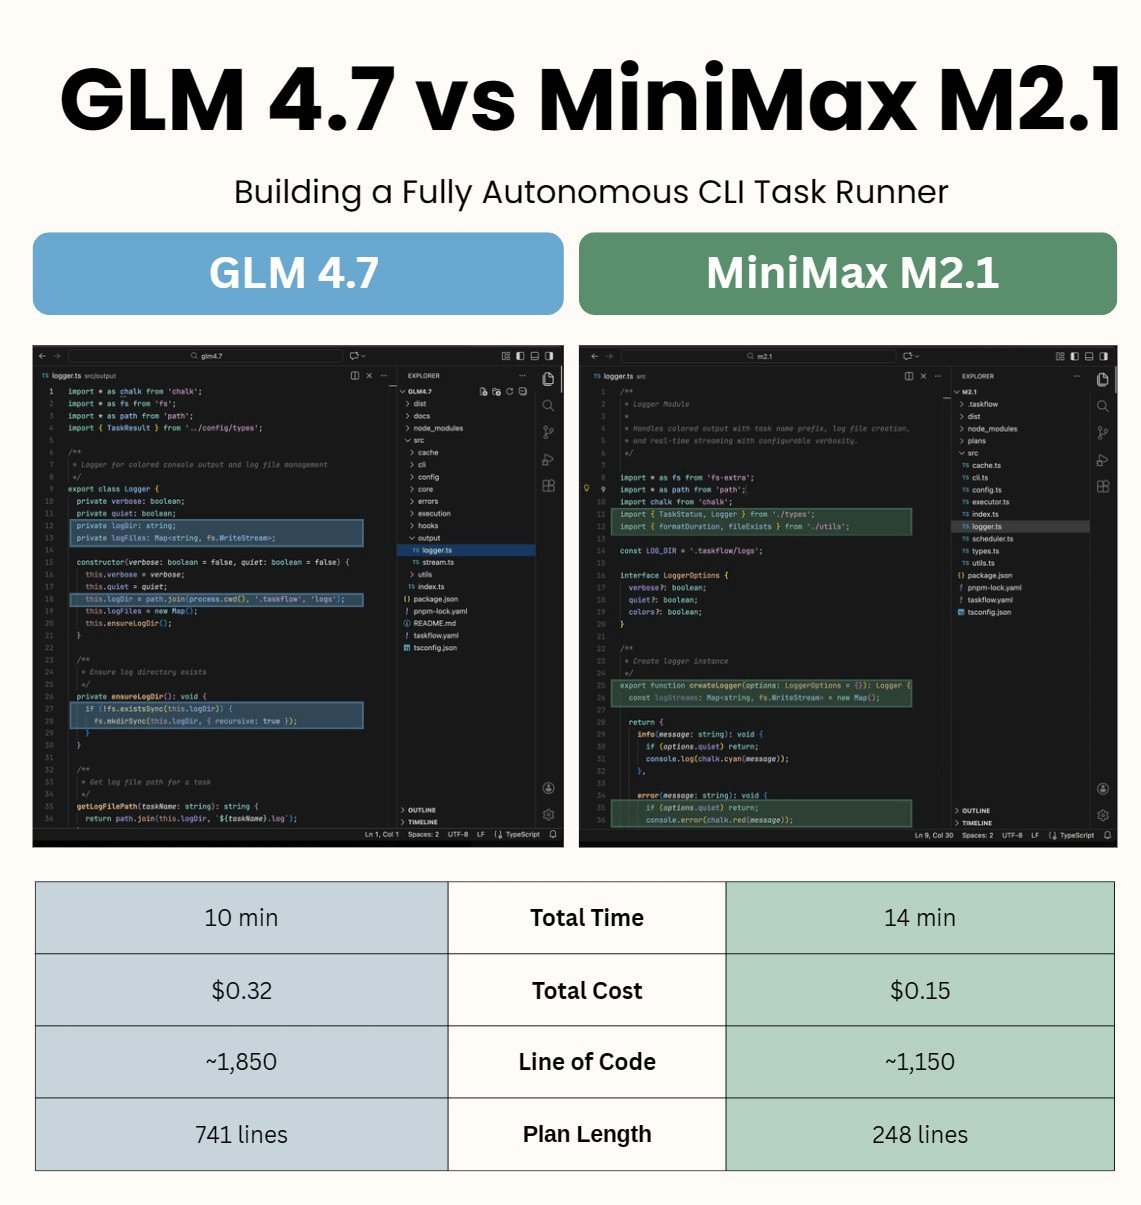
Open-Weight Models Build CLI Runner Autonomously Without Human Intervention
By
–
Open-weight models just built a 20-feature CLI runner autonomously! Kilo Code tested MiniMax M2.1 and GLM 4.7 by having them build a complete CLI task runner from scratch. Both models succeeded. No human intervention for 10-14 minutes straight. The test was realistic: build a
-

Test-time compute scaling makes large training runs obsolete
By
–
The brutal truth: The future isn't bigger models trained on more data. It's smarter inference strategies that make small models think deeper. Test-time compute scaling just made the $100M training run obsolete. Intelligence is no longer about size—it's about how long you let
-
DeepSeek-R1 beats 10x larger models by thinking longer
By
–
This explains why DeepSeek-R1 beats models 10x its size. It's not bigger. It's not trained on more data. It just thinks longer and verifies harder. 32B parameters thinking for 30 seconds > 405B parameters answering instantly. The scaling law just changed from "bigger" to
-
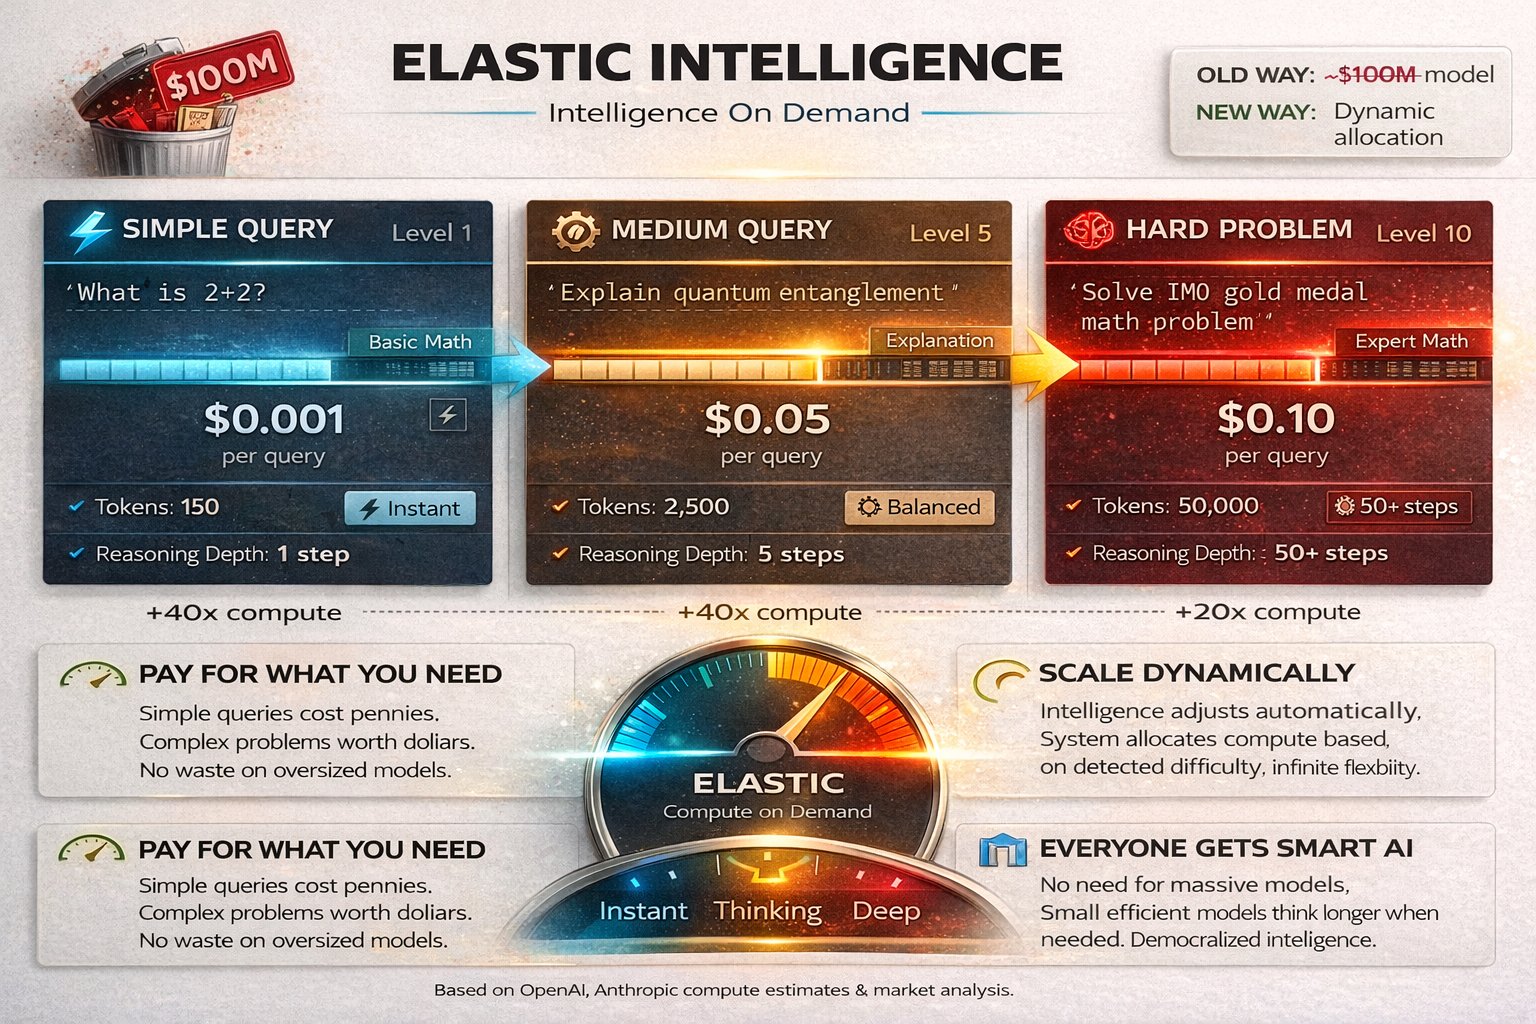
Dynamic compute allocation adjusts thinking time based on query difficulty
By
–
Dynamic compute allocation is the killer feature. Easy query: 0.1 seconds, minimal cost
Medium complexity: 2 seconds, moderate cost
Hard problem: 60 seconds, deep reasoning The model automatically adjusts thinking time based on difficulty. Pay for intelligence only when you