This is exactly how we bridge the gap between legacy content and the future of fan engagement. I can't wait to see GRAMMY IQ in action! #GRAMMYs #watsonx #AgenticAI @IBMwatsonx @IBM
INNOVATION
-

Leadership Shapes Productivity Growth and Competitive Advantage
By
–
Productivity growth is being reconsidered through new lenses, where leadership choices, strategic focus, and the ability to scale what already works shape performance. The focus moves toward deliberate moves that sustain competitiveness. @McKinsey_MGI via @antgrasso
-
AI Adoption Scaling Faster Than Organizational Foundations
By
–
Trust in AI is rising, and that sounds like progress, until you look at how many organizations are scaling faster than their foundations. #Sponsored Informatica’s CDO Insights 2026 report captures a reality I am seeing everywhere. AI adoption is moving from pilots to everyday
-
Is Vibe Coding Real Coding? Exploring AI-Assisted Development
By
–
Is vibe coding real coding? https://
youtu.be/w9rF280wlwA?si
=6bGmJWmihmF2Nm2O
… via @YouTube #vibe #vibecoding #Coding #developer #artificialintelligence #100DaysOfCode @AlbertoEMachado @Eli_Krumova @postoff25 @Khulood_Almani @anand_narang @NutritiousMind @baski_LA @TanyaSinha_ @devaang @AlAmadi1 -

Anthropic CEO warns of AI civilizational risks and new tools
By
–
Top stories in AI today: Anthropic CEO on AI’s ‘civilizational’ danger
Anthropic embeds interactive apps inside Claude
Build your own design system for AI
Microsoft's powerful new Maia 200 AI chip
4 new AI tools, community workflows, and more Read more: https://
therundown.ai/p/anthropic-ce
o-confronts-ais-dangers
… -
UK Government Partners to Build AI Assistant for GOV.UK Services
By
–
We’re partnering with the UK's Department for Science, Innovation and Technology to build an AI assistant for http://
GOV.UK. It will offer tailored advice to help British people navigate government services. Read more about our partnership: -

Attention quadratic vs Grassmann linear scaling complexity gap
By
–
The complexity story is WILD: Standard attention: O(L²d) – quadratic scaling with sequence length
Grassmann mixing: O(Ld²) – LINEAR scaling (for fixed rank r) This isn't just theoretical. As sequences get longer, the gap becomes exponential. -
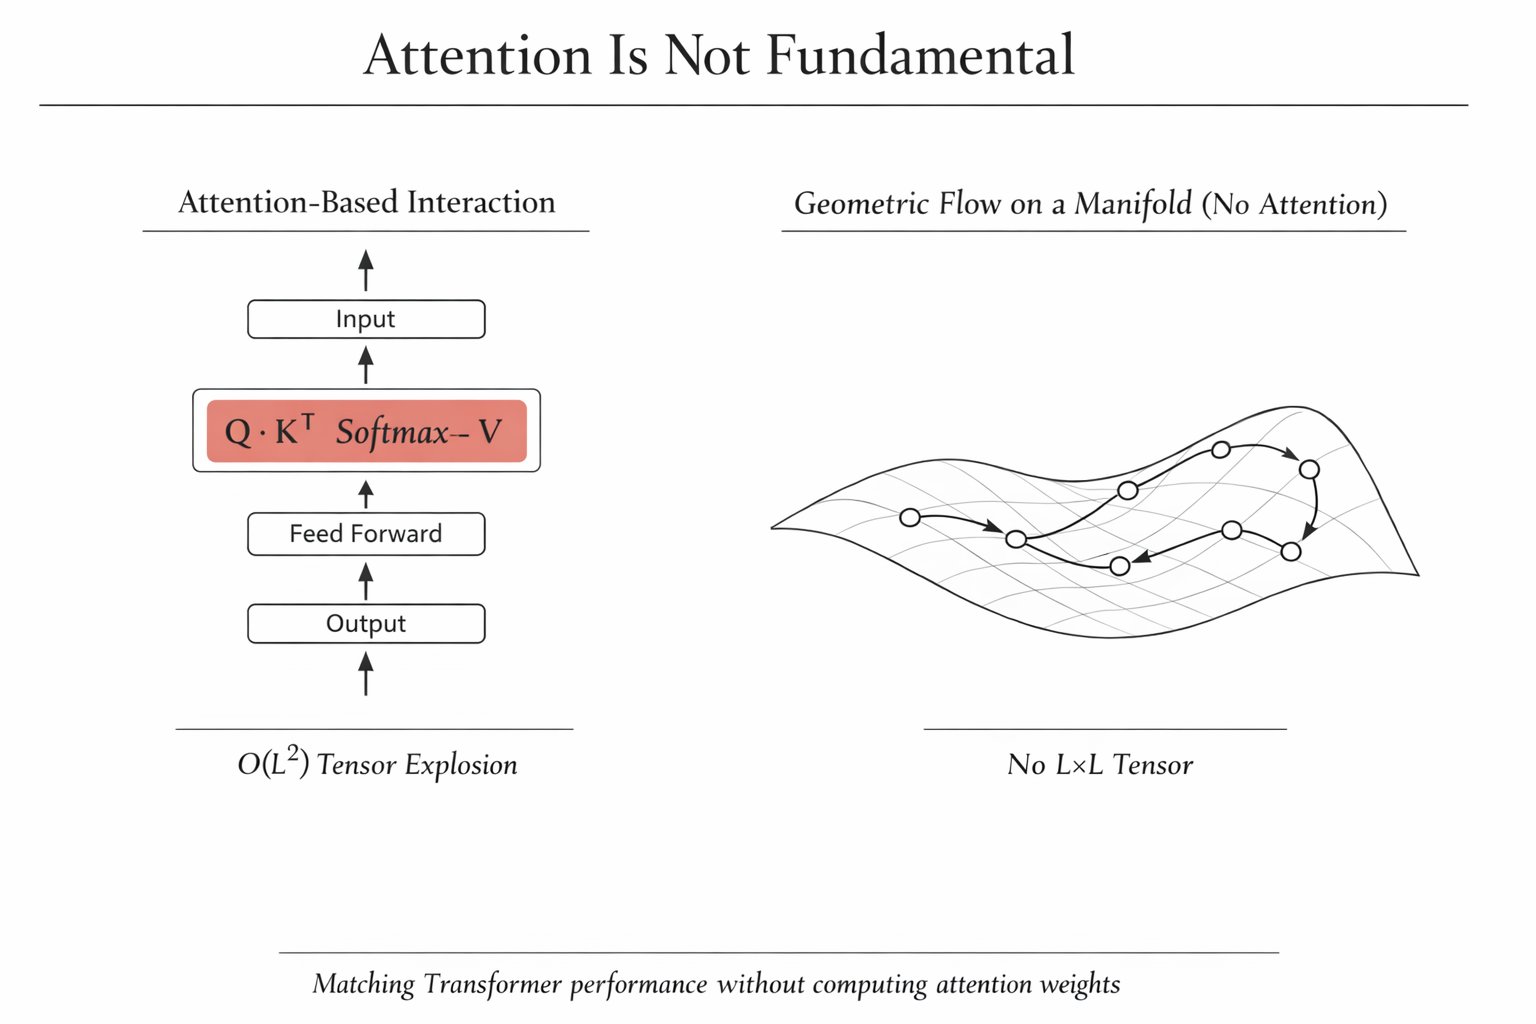
Transformer performance matched without computing attention weights
By
–
This paper just murdered the foundation of every AI model you've ever used. A researcher proved you can match Transformer performance WITHOUT computing a single attention weight. Here's what changed (and why this matters now):
