
Google's new KV-cache optimization broke the DRAM stocks, but how does it work? Let's take quick a look. "TurboQuant: Online Vector Quantization with Near-optimal Distortion Rate" TurboQuant combines 2 ideas from 2 earlier lines of work: PolarQuant and Quantized
INNOVATION
-
TurboQuant, QJL, PolarQuant: Advanced AI Model Quantization Methods
By
–
TurboQuant: https://
alphaxiv.org/abs/2504.19874 QJL: https://
alphaxiv.org/abs/2406.03482 PolarQuant: https://
alphaxiv.org/abs/2502.02617 -
Miami’s entrepreneurial AI ecosystem attracting innovation leaders
By
–
Miami’s got some very cool entrepreneurial and AI energy! Awesome to visit your Miami office @ClementDelangue
-
KUKA Industrial Robot Transformed into Immersive Gaming Station
By
–
KUKA Industrial #Robot Transformed into an Immersive Gaming Station
— Ronald van Loon (@Ronald_vanLoon) 26 mars 2026
by @JeroenBartelse
#EmergingTech #Technology #Innovation #Tech #TechForGood pic.twitter.com/FQBVX9ivdqKUKA Industrial #Robot Transformed into an Immersive Gaming Station
by @JeroenBartelse #EmergingTech #Technology #Innovation #Tech #TechForGood -
DGX Spark Powered by Toaster for Meme Potential
By
–
we should wire up a dgx spark with a toaster just for the meme potential of saying “this thing runs on a toaster”
-
Congratulations to Mistral AI for their amazing model release
By
–
Congrats to the @MistralAI team for their amazing work on this model and release!
→ View original post on X — @guillaumelample, 2026-03-26 21:03 UTC
-
Mistral Launches Voxtral-4B, a New TTS Model
By
–
Blog post: mistral.ai/news/voxtral-tts Playground: console.mistral.ai/build/audio/text-to-speech Technical report: mistral.ai/static/research/voxtral-tts.pdf Model weights: huggingface.co/mistralai/Voxtral-4B-TTS-2603 [Translated from EN to English]
→ View original post on X — @guillaumelample, 2026-03-26 21:03 UTC
-
Mistral AI Launches Voxtral TTS: Fast, Cost-Effective Speech Model
By
–
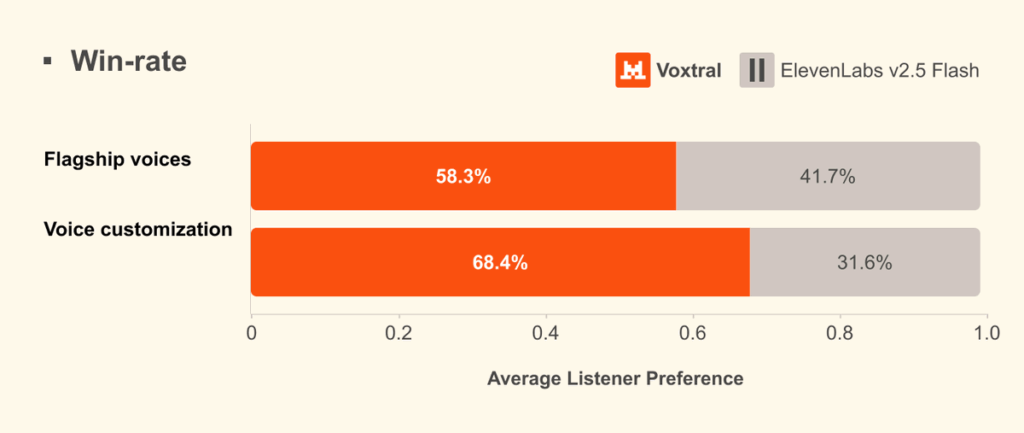
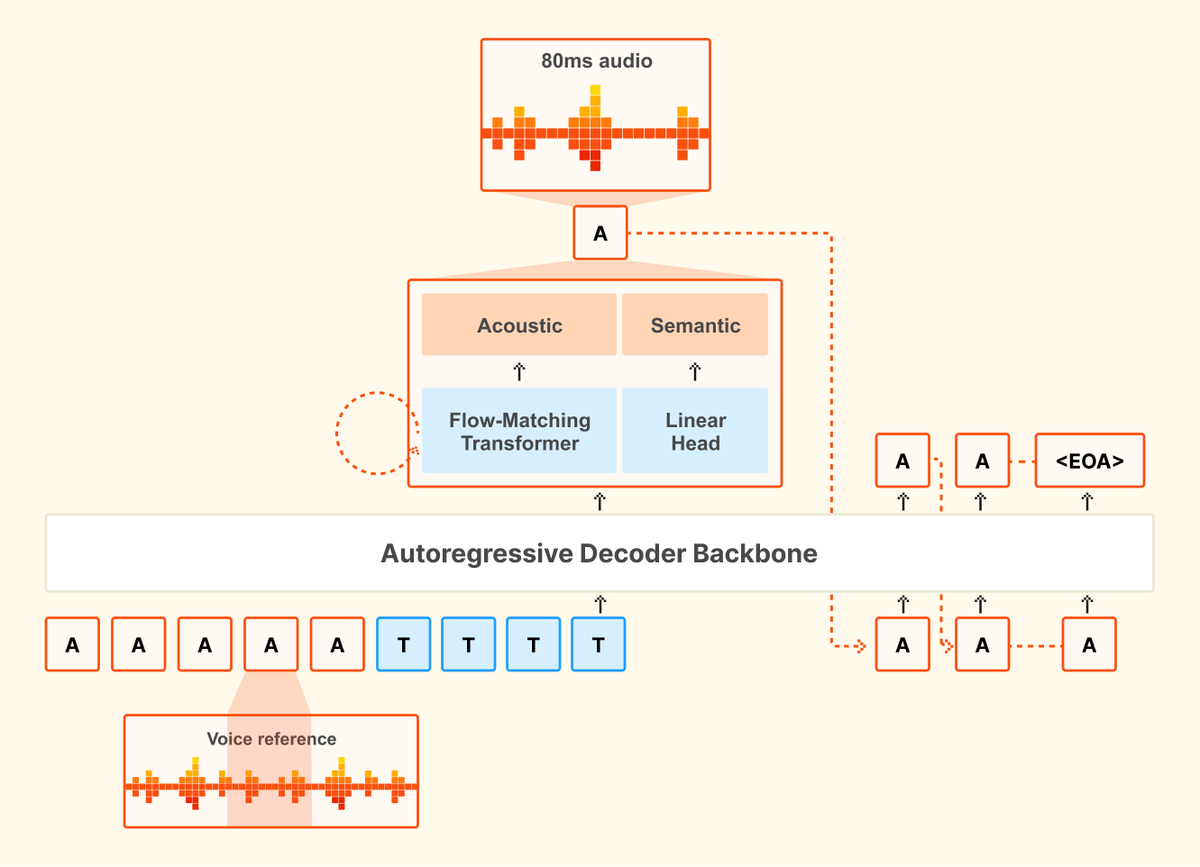
Our first speech model, Voxtral TTS, is out. It delivers SOTA performance while significantly reducing cost compared to existing solutions, and it operates with very low latency. It uses a new architecture that combines auto-regressive generation of semantic speech tokens with flow-matching for acoustic tokens. We are also releasing a technical report sharing all our training methodology and insights. Much more to come in audio — stay tuned ! Mistral AI (@MistralAI) 🔊Introducing Voxtral TTS: our new frontier open-weight model for natural, expressive, and ultra-fast text-to-speech 🎭Realistic, emotionally expressive speech. 🌍Supports 9 languages and accurately captures diverse dialects. ⚡Very low latency for time-to-first-audio. 🔄Easily adaptable to new voices — https://nitter.net/MistralAI/status/2037183026539483288#m
→ View original post on X — @guillaumelample, 2026-03-26 21:03 UTC
-
MiniMax 2.5 Powers Fast Agentic Workflows on SambaCloud
By
–
@openclaw is unstoppable…when powered by the right model. Big, slow LLMs kill agentic workflows. The secret? MiniMax 2.5 + SambaCloud’s lightning-fast inference. Try it on http://
cloud.sambanova.ai Read more in our blog -
OpenAI Doubles Codex Rate Limits for One Week
By
–
meanwhile, you can enjoy Codex with 2x rate limits for the next week 24×7 across all ChatGPT subscriptions! npm i -g @openai/codex time to build is NOW!!