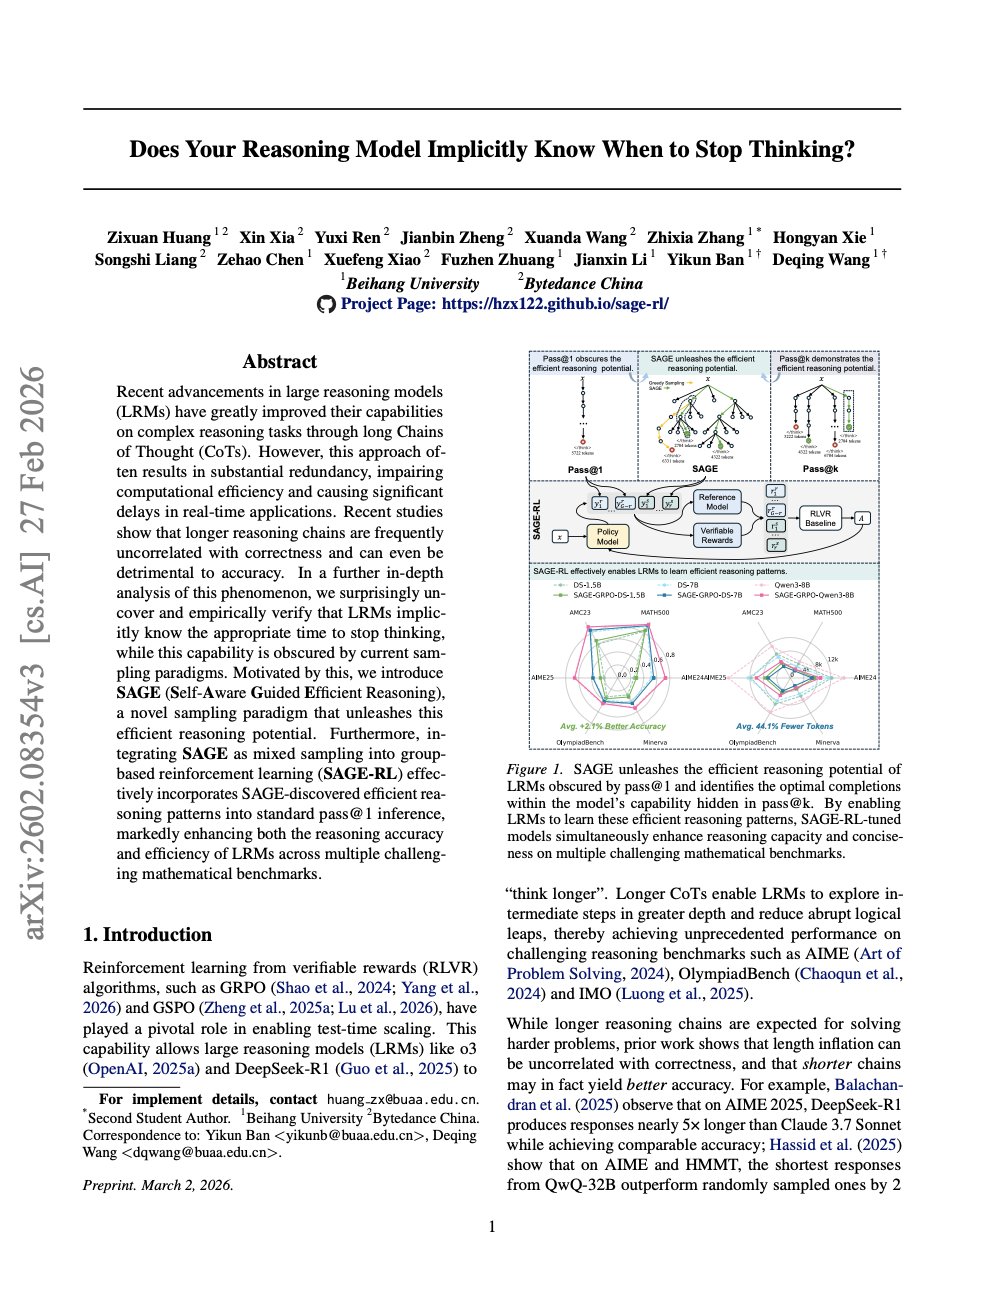
reasoning models already know when they've solved the problem. we just don't let them stop. new paper from Beihang University and ByteDance shows that the overthinking problem in models like DeepSeek-R1 and Qwen3 isn't a training failure. it's a sampling failure. the fix cuts
HEALTHCARE AI
-
AI does good: ChatGPT saves life with rare diagnosis
By
–
What good things is AI doing? Here's 10 things my AI agents found here on X that are examples of good things AI has done for humans. +++++ 1. "ChatGPT saved my life" — grocery store conversation about an ultra-rare diagnosis "Doctors couldn't figure it out. AI did. Turns out
-
WordPress Categories for AI News Aggregator
By
–
This is my first attempt at subscribers thread. 1/2
-

GPT-5.4 scores 74% on ARC-AGI-2
By
–

GPT-5.4 scored 74.0% on ARC-AGI-2 GPT-5.4 Pro got 83.3%, getting close to a level of Gemini 3 Deep Think.
-

Life Sciences Teams Transform RWE Workflows with Governed Insight Engines
By
–
At PHUSE US, @DominoDataLab
's Agnes Younes demonstrates how life sciences teams are moving from fragmented RWE workflows to governed, end-to-end insight engines. See "Reproducible RWE at Scale: From Fragmented Data to Regulatory-Ready Insight" Details: https://
domino.buzz/4lbyTjJ -
ChatGPT Health Underestimates Severity of Medical Cases
By
–
The health-focused chatbot from ChatGPT, used by 40M users, would underestimate the severity of cases more than 1 in 2 times. A law is being studied in NY state to ban automated medical advice. statescoop.com/new-york-bill… gizmodo.com/chatgpt-health-u… [Translated from EN to English]
→ View original post on X — @flashtweet, 2026-03-05 07:20 UTC
-
OpenAI Tests Potential GPT-5.4 Model ‘Galapagos’
By
–
BREAKING : OpenAI has started testing a new model named “Galapagos” on Arena which potentially could be a GPT-5.4 low effort version. “Sooner than you think”
-
Retrieval Method Trumps Memory Writing in AI Agents
By
–
most people building AI agents obsess over how they WRITE memories
turns out that's basically irrelevant new research analyzed 9 different memory systems across 1,540 questions the finding?
retrieval method drives 20-point accuracy swings
write strategy? 3–8 points max raw -
Leading enterprises move AI from pilots to production
By
–
In @WSJ
, learn how leading enterprises are escaping pilot purgatory and moving AI into production. Proud to support that work at @BMSnews and @NewYorkLife two of the most forward-thinking AI innovators in life sciences and insurance. https://
domino.buzz/4761rFr -
DeepSeek and Qwen3 performance improvements
By
–
specific numbers worth sitting with: > DeepSeek-R1-7B on MATH-500: 93% accuracy (up from 91.6%), tokens cut from 3,871 to 2,141 > DeepSeek-R1-1.5B on AIME 2025: accuracy jumps 6.2 percentage points > Qwen3-8B: response length halved from 18,342 to 9,183 tokens with no accuracy