Neuralink will start high-volume production of brain-computer interface devices and move to a streamlined, almost entirely automated surgical procedure in 2026. Device threads will go through the dura, without the need to remove it. This is a big deal. x.com/SERobinsonJr/s…
HEALTHCARE AI
-
Neuralink Claims Full Body Function Restoration Possible, Scales Up 2026
By
–
🚨Percée pour neuralink !
— VISION IA (@vision_ia) 3 janvier 2026
Elon Musk :
« Il est physiquement possible de restaurer l’intégralité des fonctions du corps »
De plus, Elon Musk assure que Neuralink lancera la production à grande échelle de ses implants cérébraux en 2026. pic.twitter.com/k24htxeg43Percée pour neuralink ! Elon Musk : « Il est physiquement possible de restaurer l’intégralité des fonctions du corps » De plus, Elon Musk assure que Neuralink lancera la production à grande échelle de ses implants cérébraux en 2026.
-
Tech breakthroughs: Brain implants, Starlink, antibodies, EV records
By
–
Top stories in tech today: – Musk will soon mass-produce brain implants
– SpaceX to lower Starlink satellites
– MIT shrinks IV antibody infusions into one shot
– Norway’s EV revolution hits new record
– Quick hits on other tech news Read more: https://
tech.therundown.ai/p/neuralinks-b
et-to-scale-brain-surgery
… -
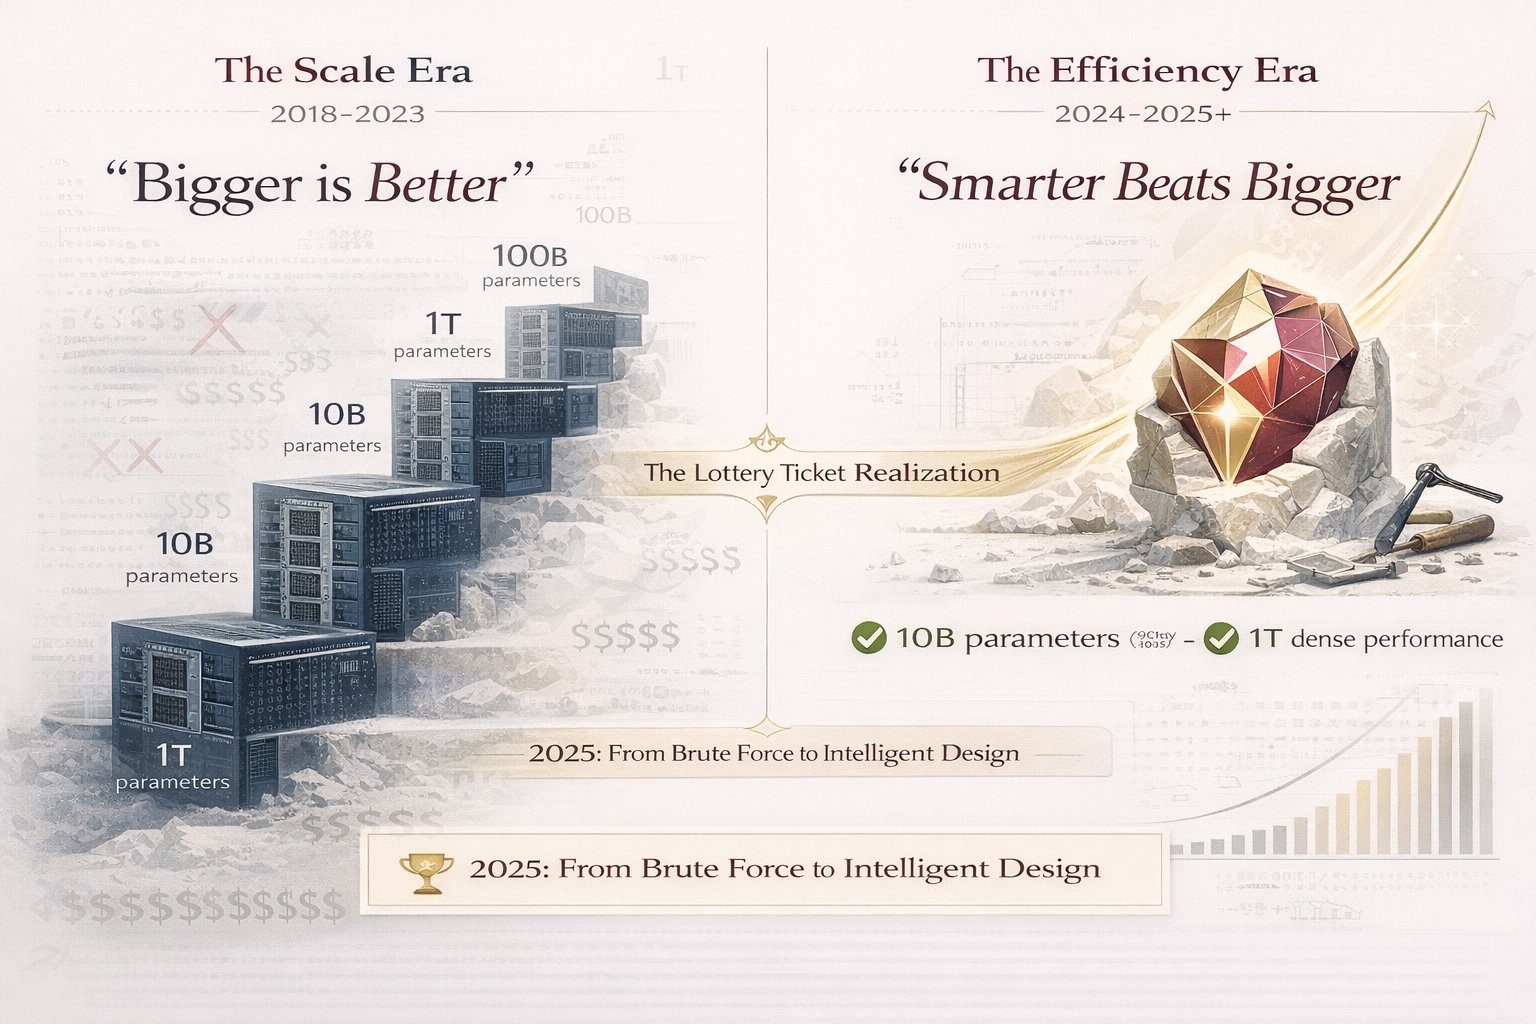
The Efficiency Era of AI Models
By
–
The lottery ticket hypothesis wasn't wrong. We just weren't ready for it. In 2025, sparse models are no longer academic curiosities. They're production infrastructure. The future isn't bigger models. It's smarter pruning. Welcome to the efficiency era. Read it here if you
-
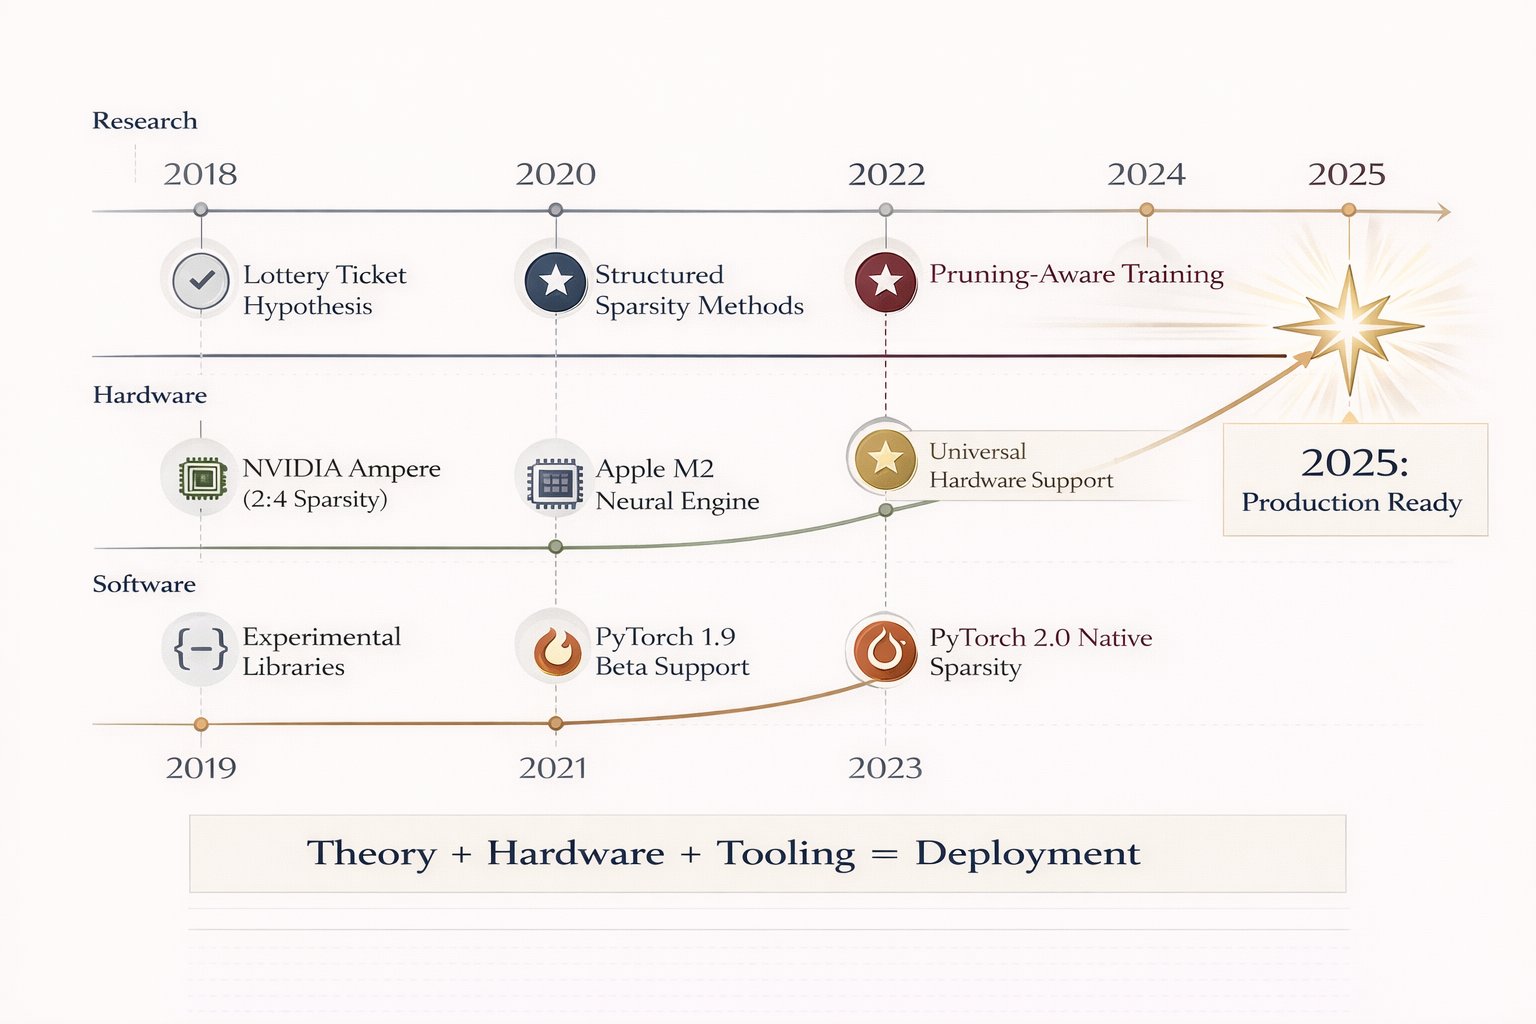
2026 Breakthroughs Made AI Production-Ready
By
–
Three breakthroughs made this production-ready in 2026: 1. Pruning-aware training (train sparse from the start)
2. Hardware support (NVIDIA Ampere+, Apple Neural Engine)
3. Framework integration (PyTorch 2.0 native sparsity) The tooling finally caught up to the theory. -
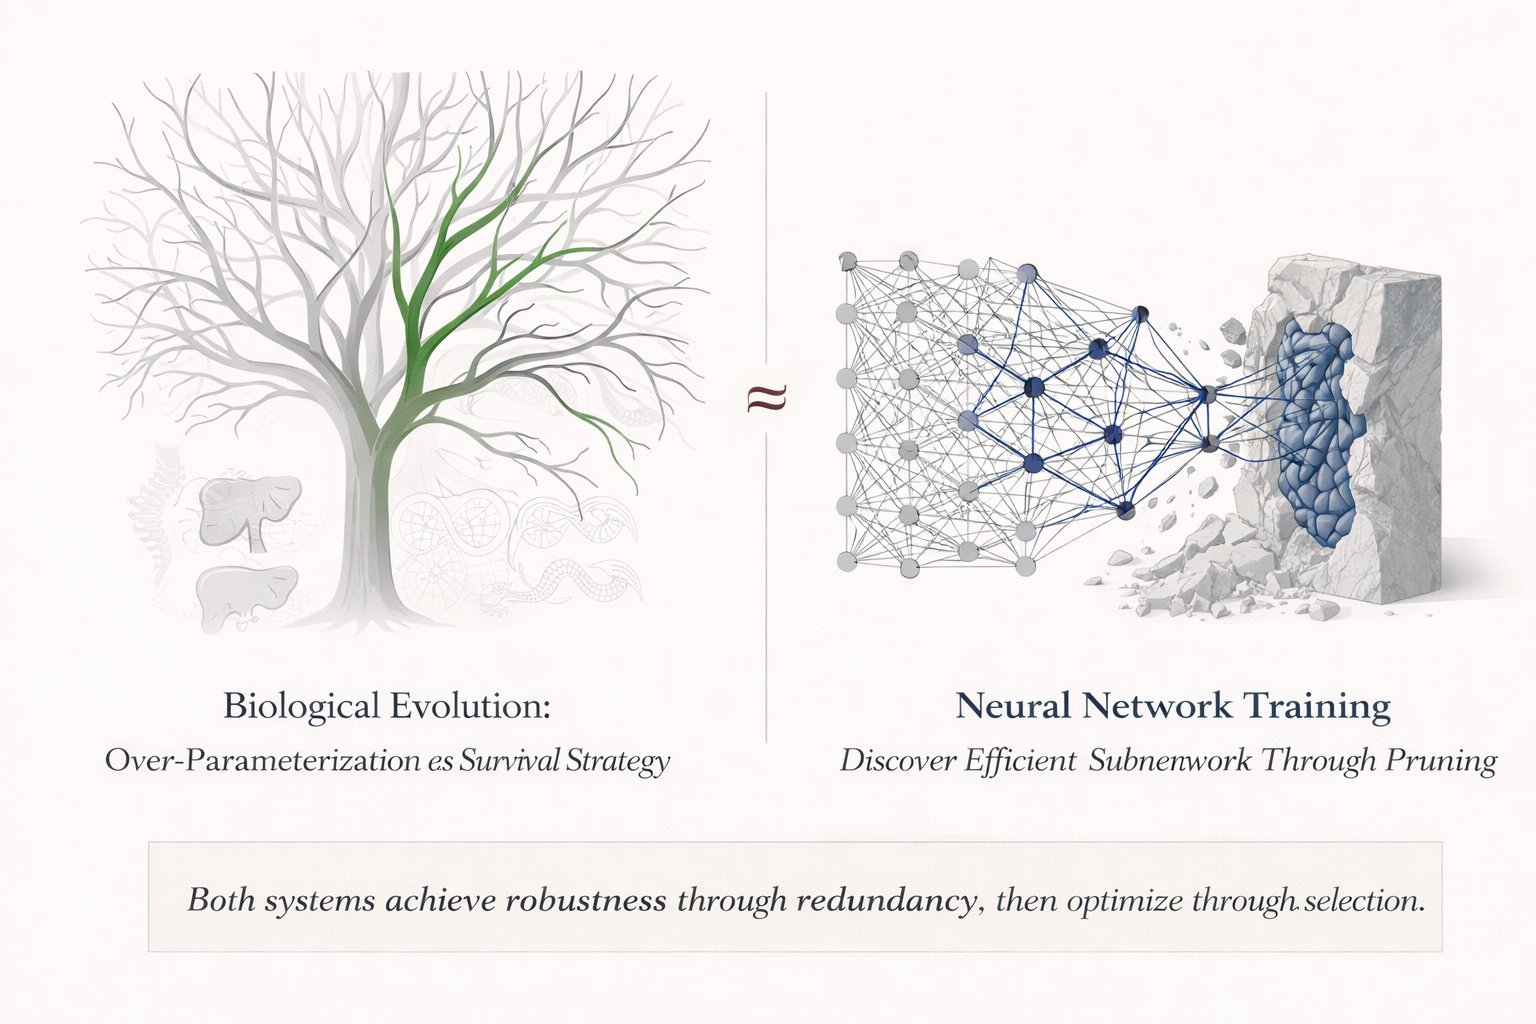
Neural networks are 90% redundant by design
By
–
The academic papers missed the real story. It's not about finding "winning tickets" in random initialization. It's about discovering that neural networks are 90% redundant by design, and modern hardware finally lets us exploit that. Evolution over-parameterizes. We can prune.
-

Transformational AI Model Efficiency Gains
By
–
The deployment implications are massive: – GPT-3 scale models (175B params) → 17.5B params at same accuracy
– Monthly inference costs: $500K → $50K
– Latency: 2 seconds → 200ms
– Memory requirements: 350GB → 35GB This isn't incremental. It's transformational. -
NVIDIA’s Block Sparsity Breakthrough Speeds AI
By
–
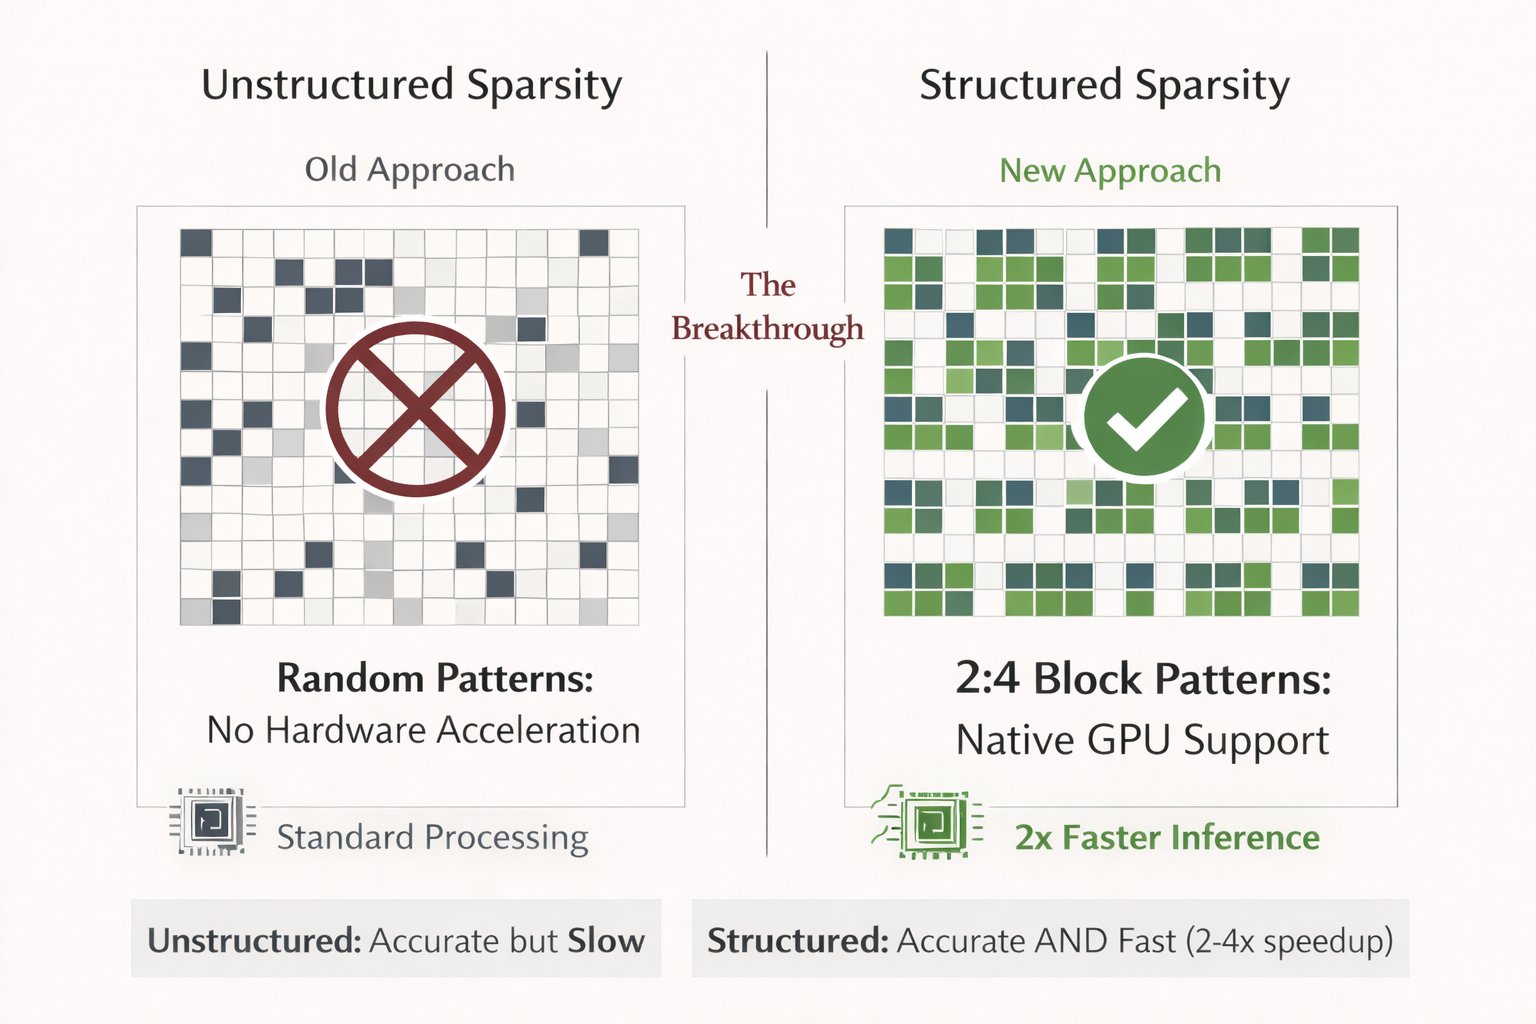
Then came the breakthrough nobody expected: Structured sparsity + modern hardware. NVIDIA proved you don't need random sparse patterns. Block sparsity (2:4, 4:8 patterns) runs NATIVELY on modern GPUs. Suddenly the lottery ticket isn't just accurate. It's actually faster.
-
2018 Paper: Pruning Neural Networks Without Accuracy Loss
By
–
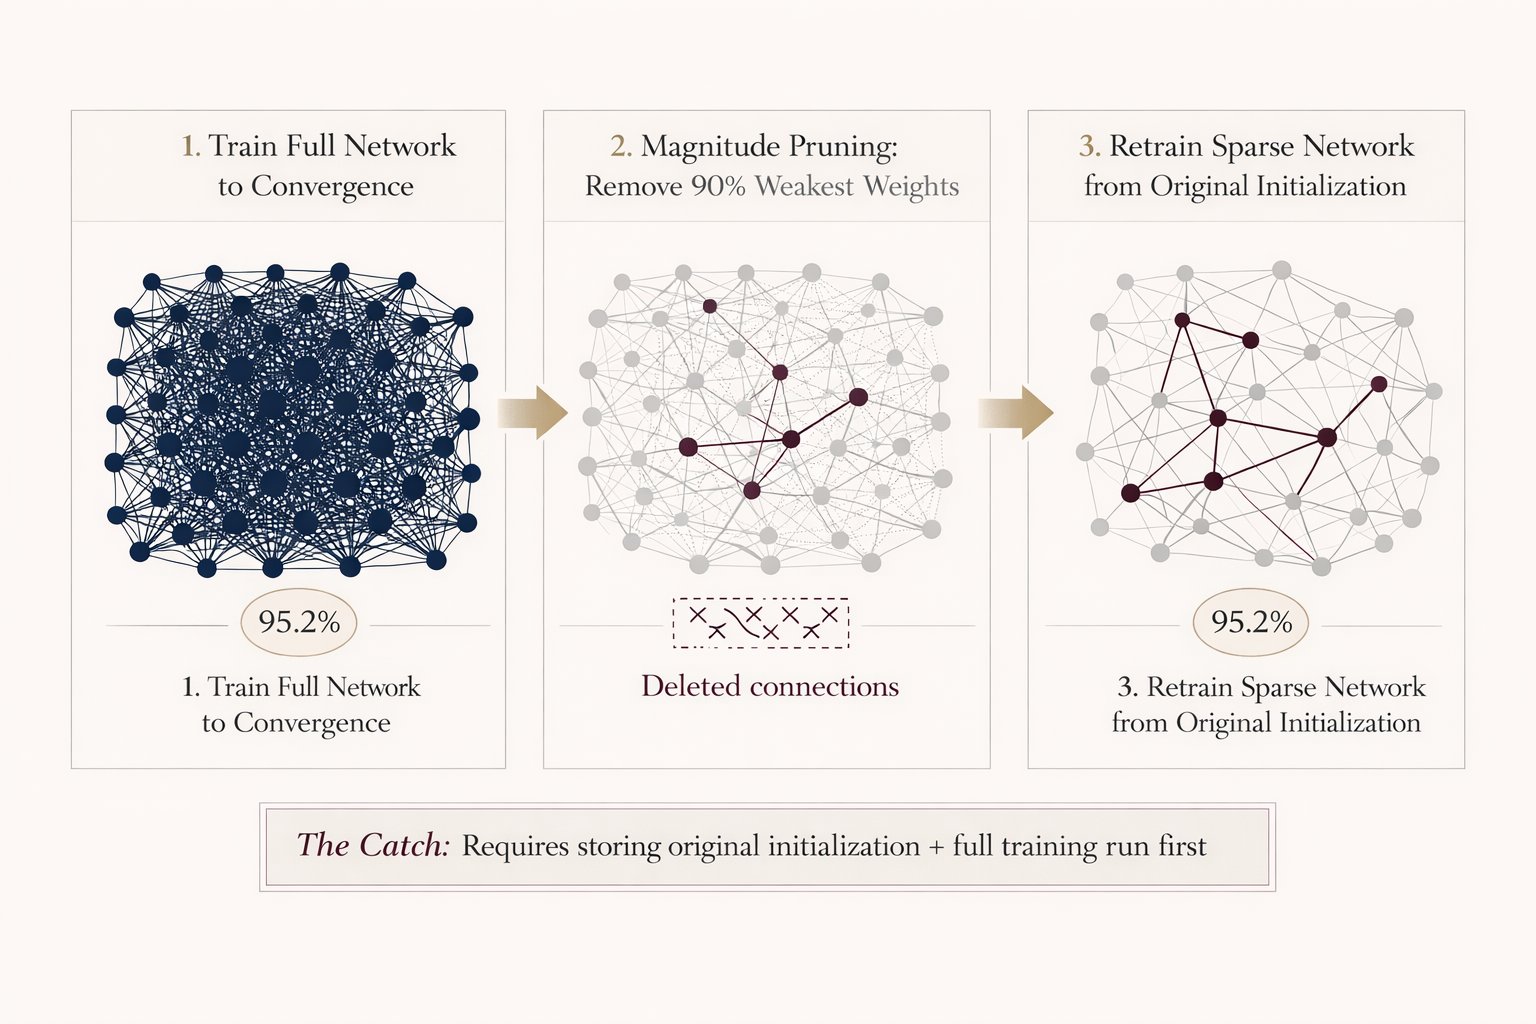
The original 2018 paper was mind-blowing: Train a massive neural network. Delete 90% of it based on weight magnitudes. Retrain from scratch with the same initialization. Result: The pruned network matches the original's accuracy. But there was a catch that killed adoption.
-

MIT’s 90% Neural Network Deletion Breakthrough Ignored
By
–
MIT proved you can delete 90% of a neural network without losing accuracy. Five years later, nobody implements it. "The Lottery Ticket Hypothesis" just went from academic curiosity to production necessity, and it's about to 10x your inference costs. Here's what changed (and