
This is a powerful example of technology doing what it should do best: support recovery, not replace people. Rehabilitation robots like this one help patients regain mobility after injuries by providing consistent, adaptive, and repeatable movements – something that’s hard to
HEALTHCARE AI
-
Opus 4.5 Analyzes Genetic Data, Reshaping Healthcare AI
By
–
I'm amazed at Opus 4.5's ability to parse my genetic data file (a massive 25mb txt). It even wrote little analysis tools for itself to answer my questions! Pretty clear this is how we'll be going through all health data soon.
-

Opus 4.5 Analyzes Genetic Data Better Than 23andMe
By
–
Chatting with Opus 4.5 about my genetic data & it's surfacing all kinds of interesting things 23andMe never told me. Strongly recommend if you have your genome data.
-
CES Report: AI detects breast cancer earlier with free app
By
–
CES Report #1 (Will be doing then all week).
— Robert Scoble (@Scobleizer) 5 janvier 2026
AI helps detect breast cancer earlier thanks to https://t.co/JUyaGOd5KN
Free app. pic.twitter.com/z3tHaPSnViCES Report #1 (Will be doing then all week). AI helps detect breast cancer earlier thanks to https://
hopevalley.ai Free app. -
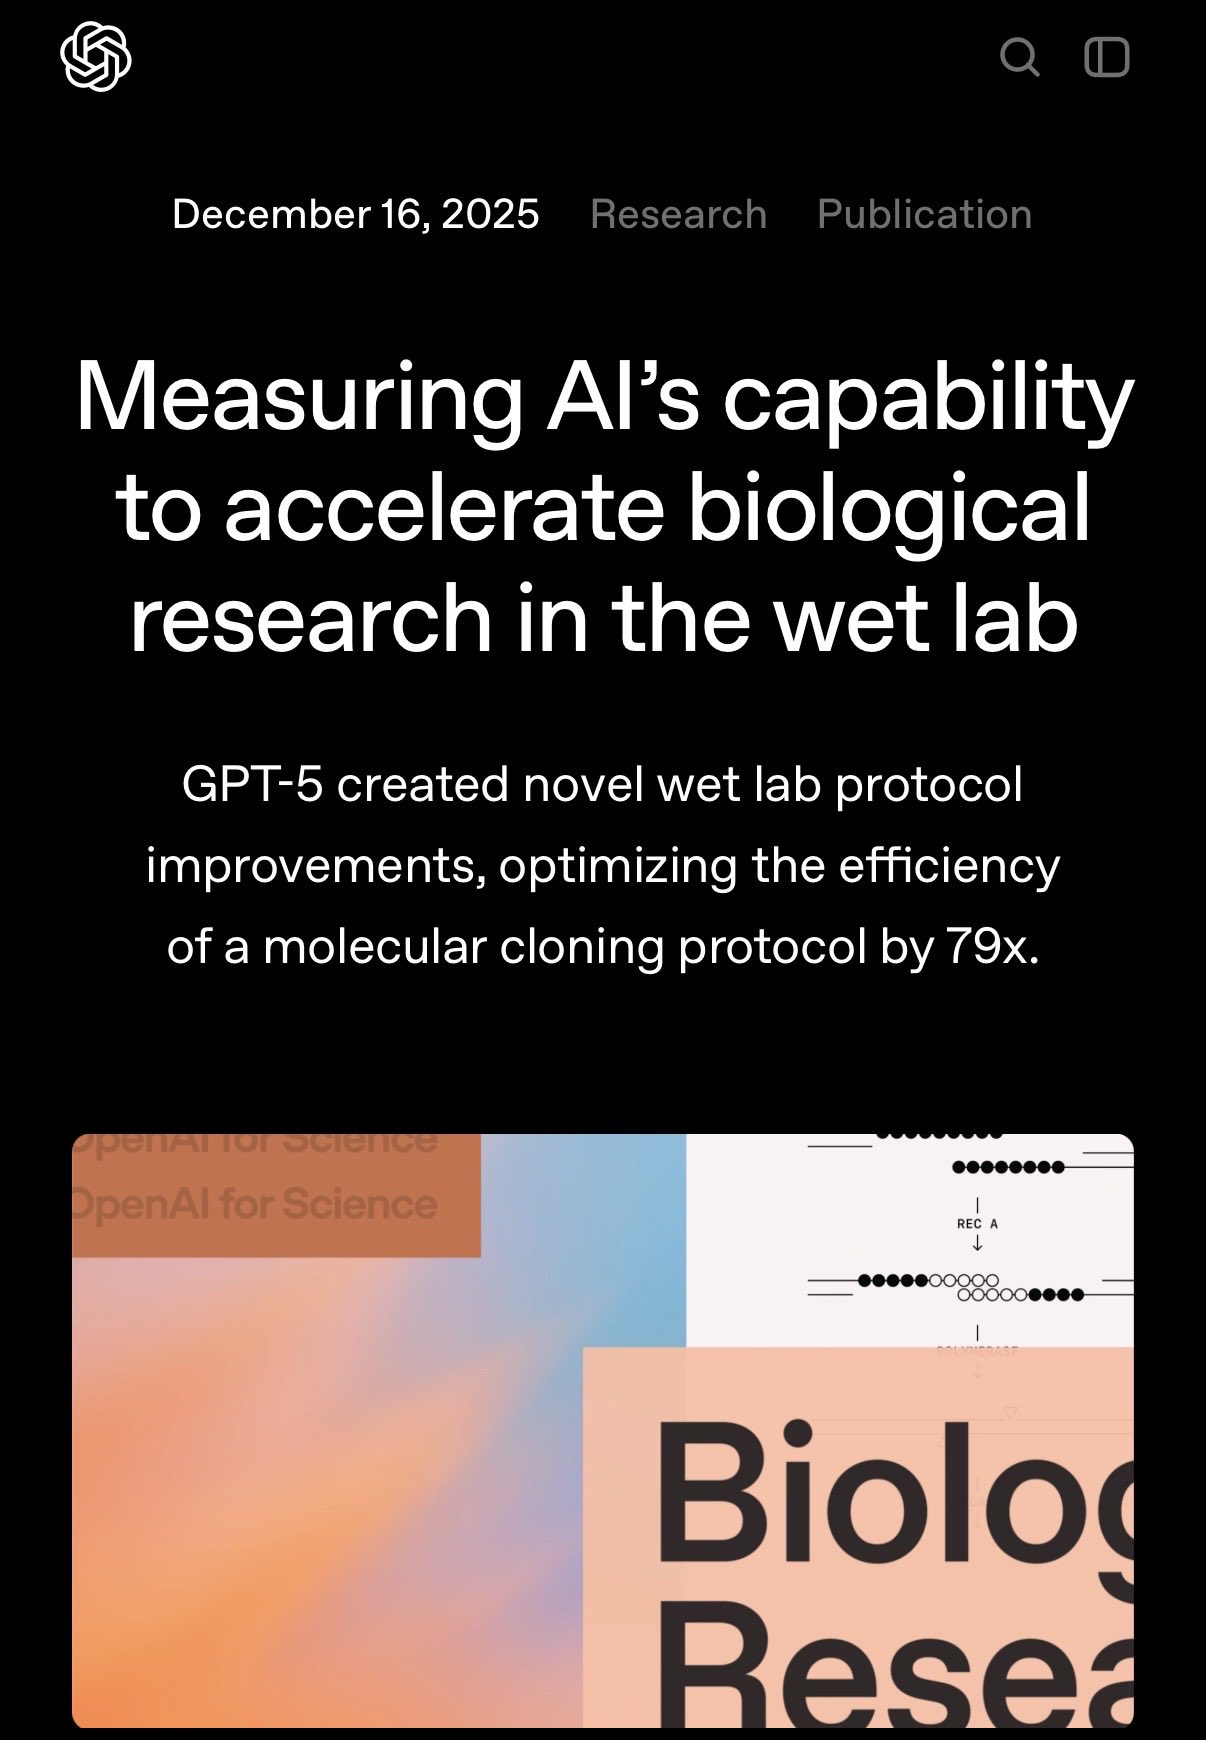
GPT-5 boosts gene-editing efficiency 79x
By
–
OpenAI’s lab experiment with GPT-5 via Red Queen Bio optimized an actual gene-editing protocol and achieved a 79× efficiency gain . This is AI actually doing wet-lab biology, not just simulations. First real AI-augmented experimentation mixing predictions with robotic
-
MoE: From Niche to Industry Standard by 2025
By
–
Mixture of Experts went from academic curiosity (1991) → impossible to scale (2000s) → production breakthrough (2021) → industry standard (2025). Dense models are becoming legacy infrastructure. If you're building AI in 2025 and not considering MoE, you're overpaying by 10x.
-
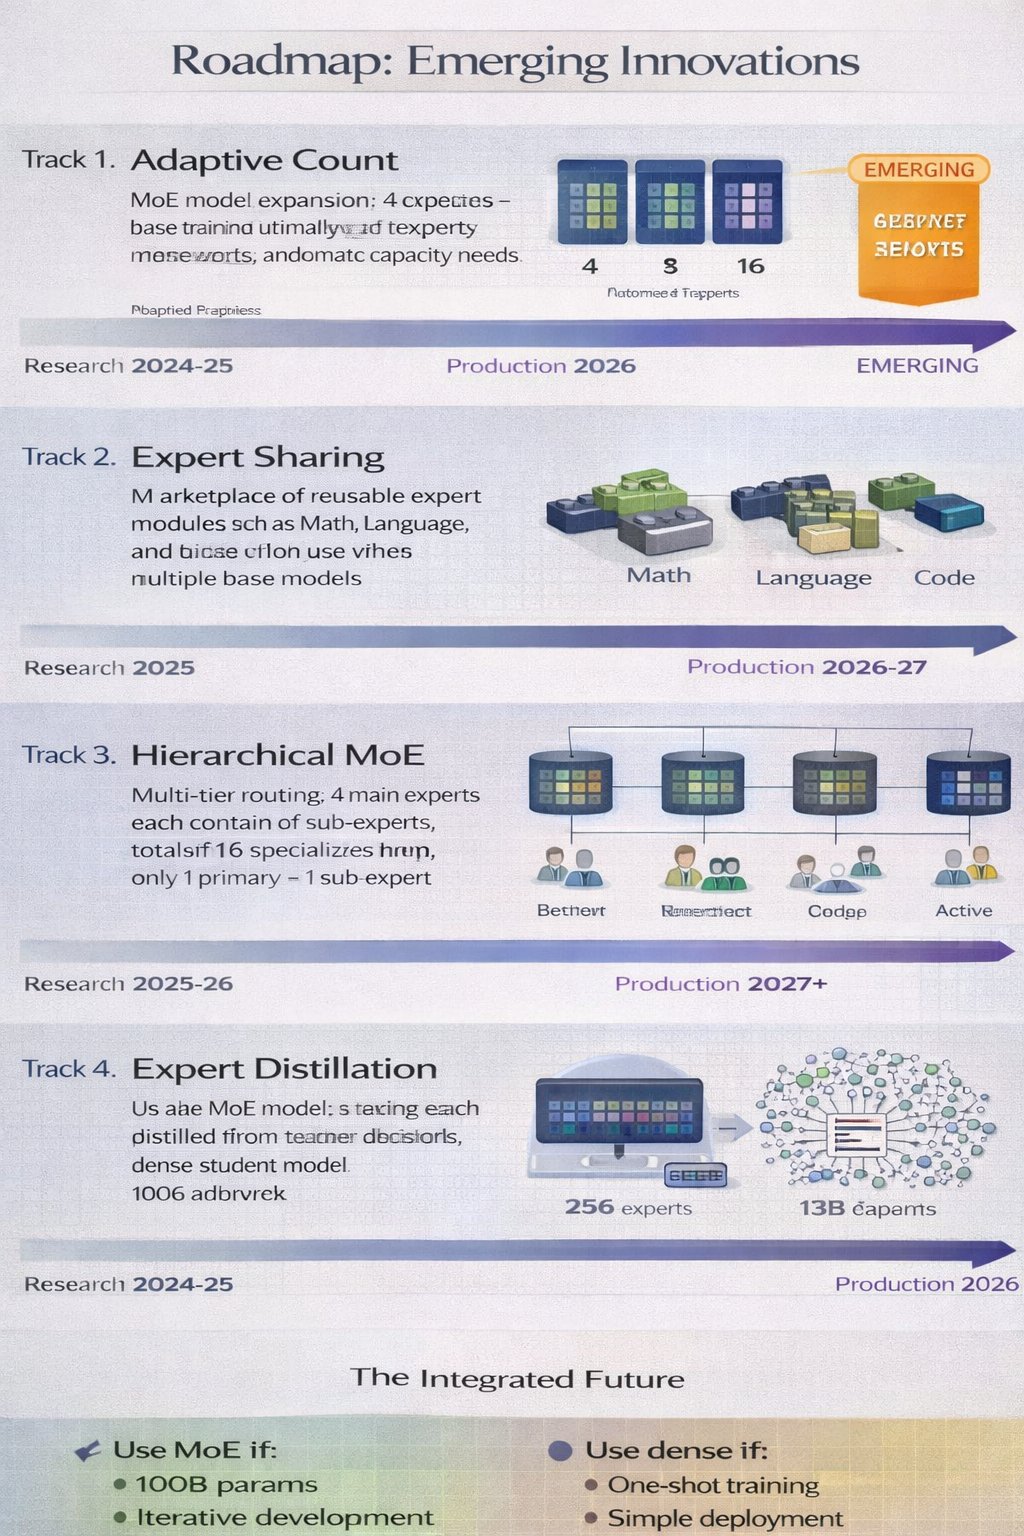
Next-Gen MoE Innovations in 2026
By
–
What's coming next: → Adaptive expert count (dynamically add/remove experts during training)
→ Cross-model expert sharing (reuse specialists across different models)
→ Hierarchical MoE (experts that route to sub-experts)
→ Expert distillation (compress MoE knowledge back -
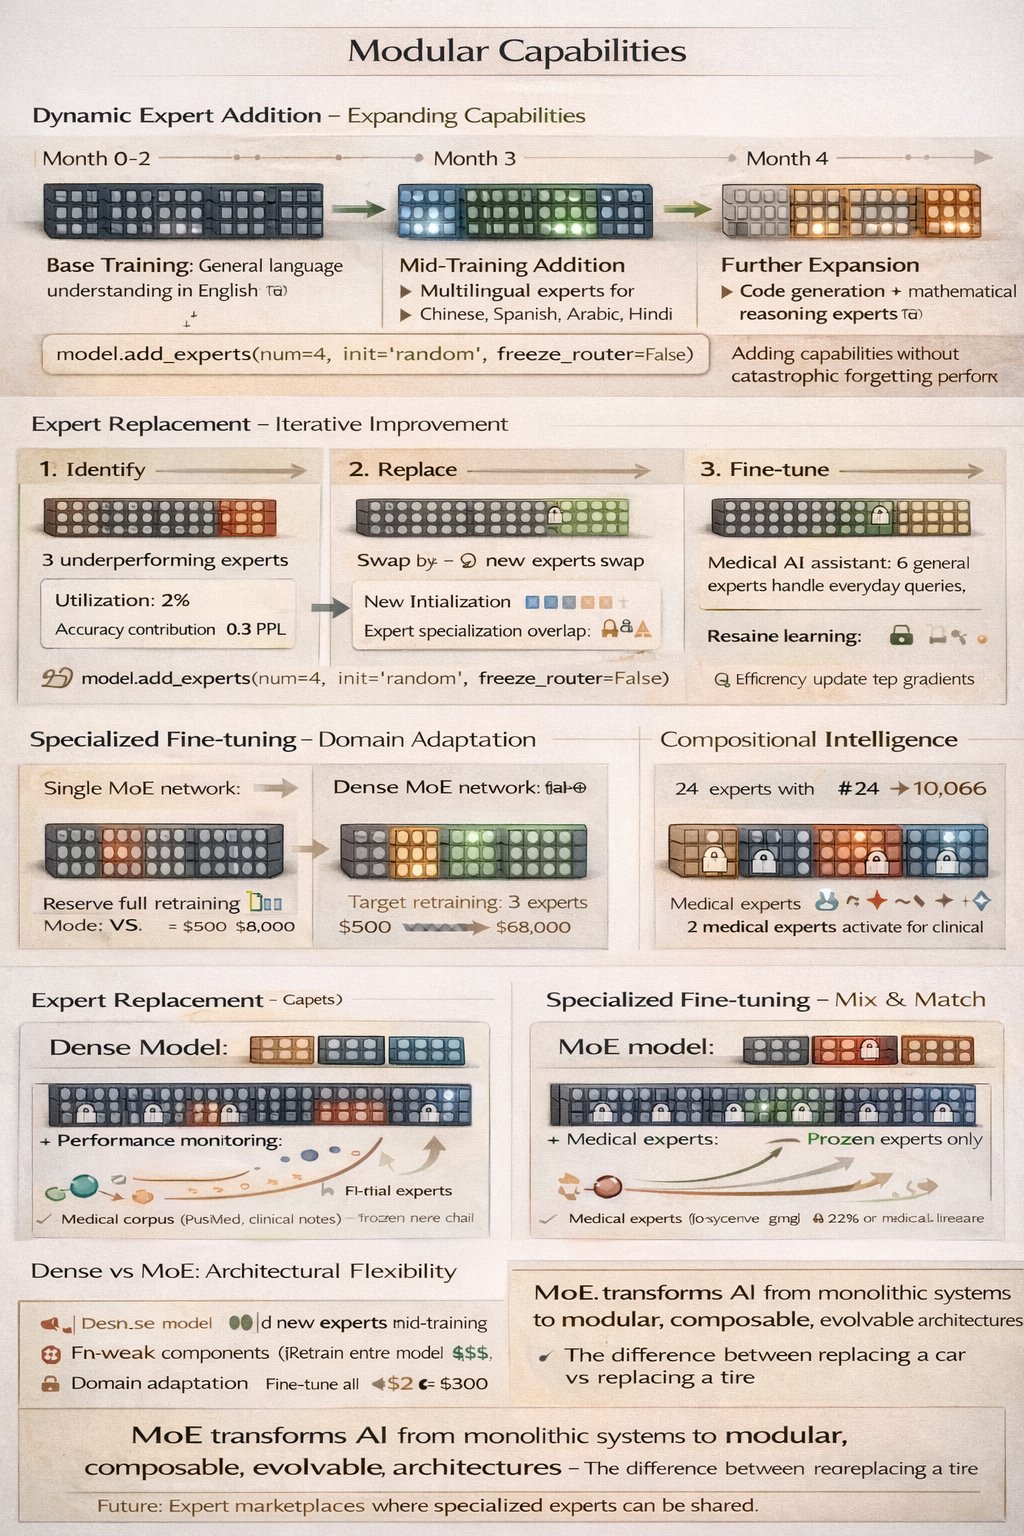
MoE’s Hidden Potential: New Training Strategies
By
–
Here's the part nobody talks about: MoE doesn't just save compute. It enables entirely new training strategies. You can: → Add experts mid-training for new capabilities
→ Replace underperforming experts without retraining everything
→ Fine-tune individual experts on -

MoE Architecture: 5-10x More Parameters
By
–
The modern MoE architecture is insane: > Mixtral 8x7B: 47B total params, only 13B active per token
> DeepSeek-V3: 671B params, 37B active – beats GPT-4 at 1/10th cost
> Grok-1: 314B params, trained faster than any dense model of similar quality Pattern: 5-10x more parameters. -
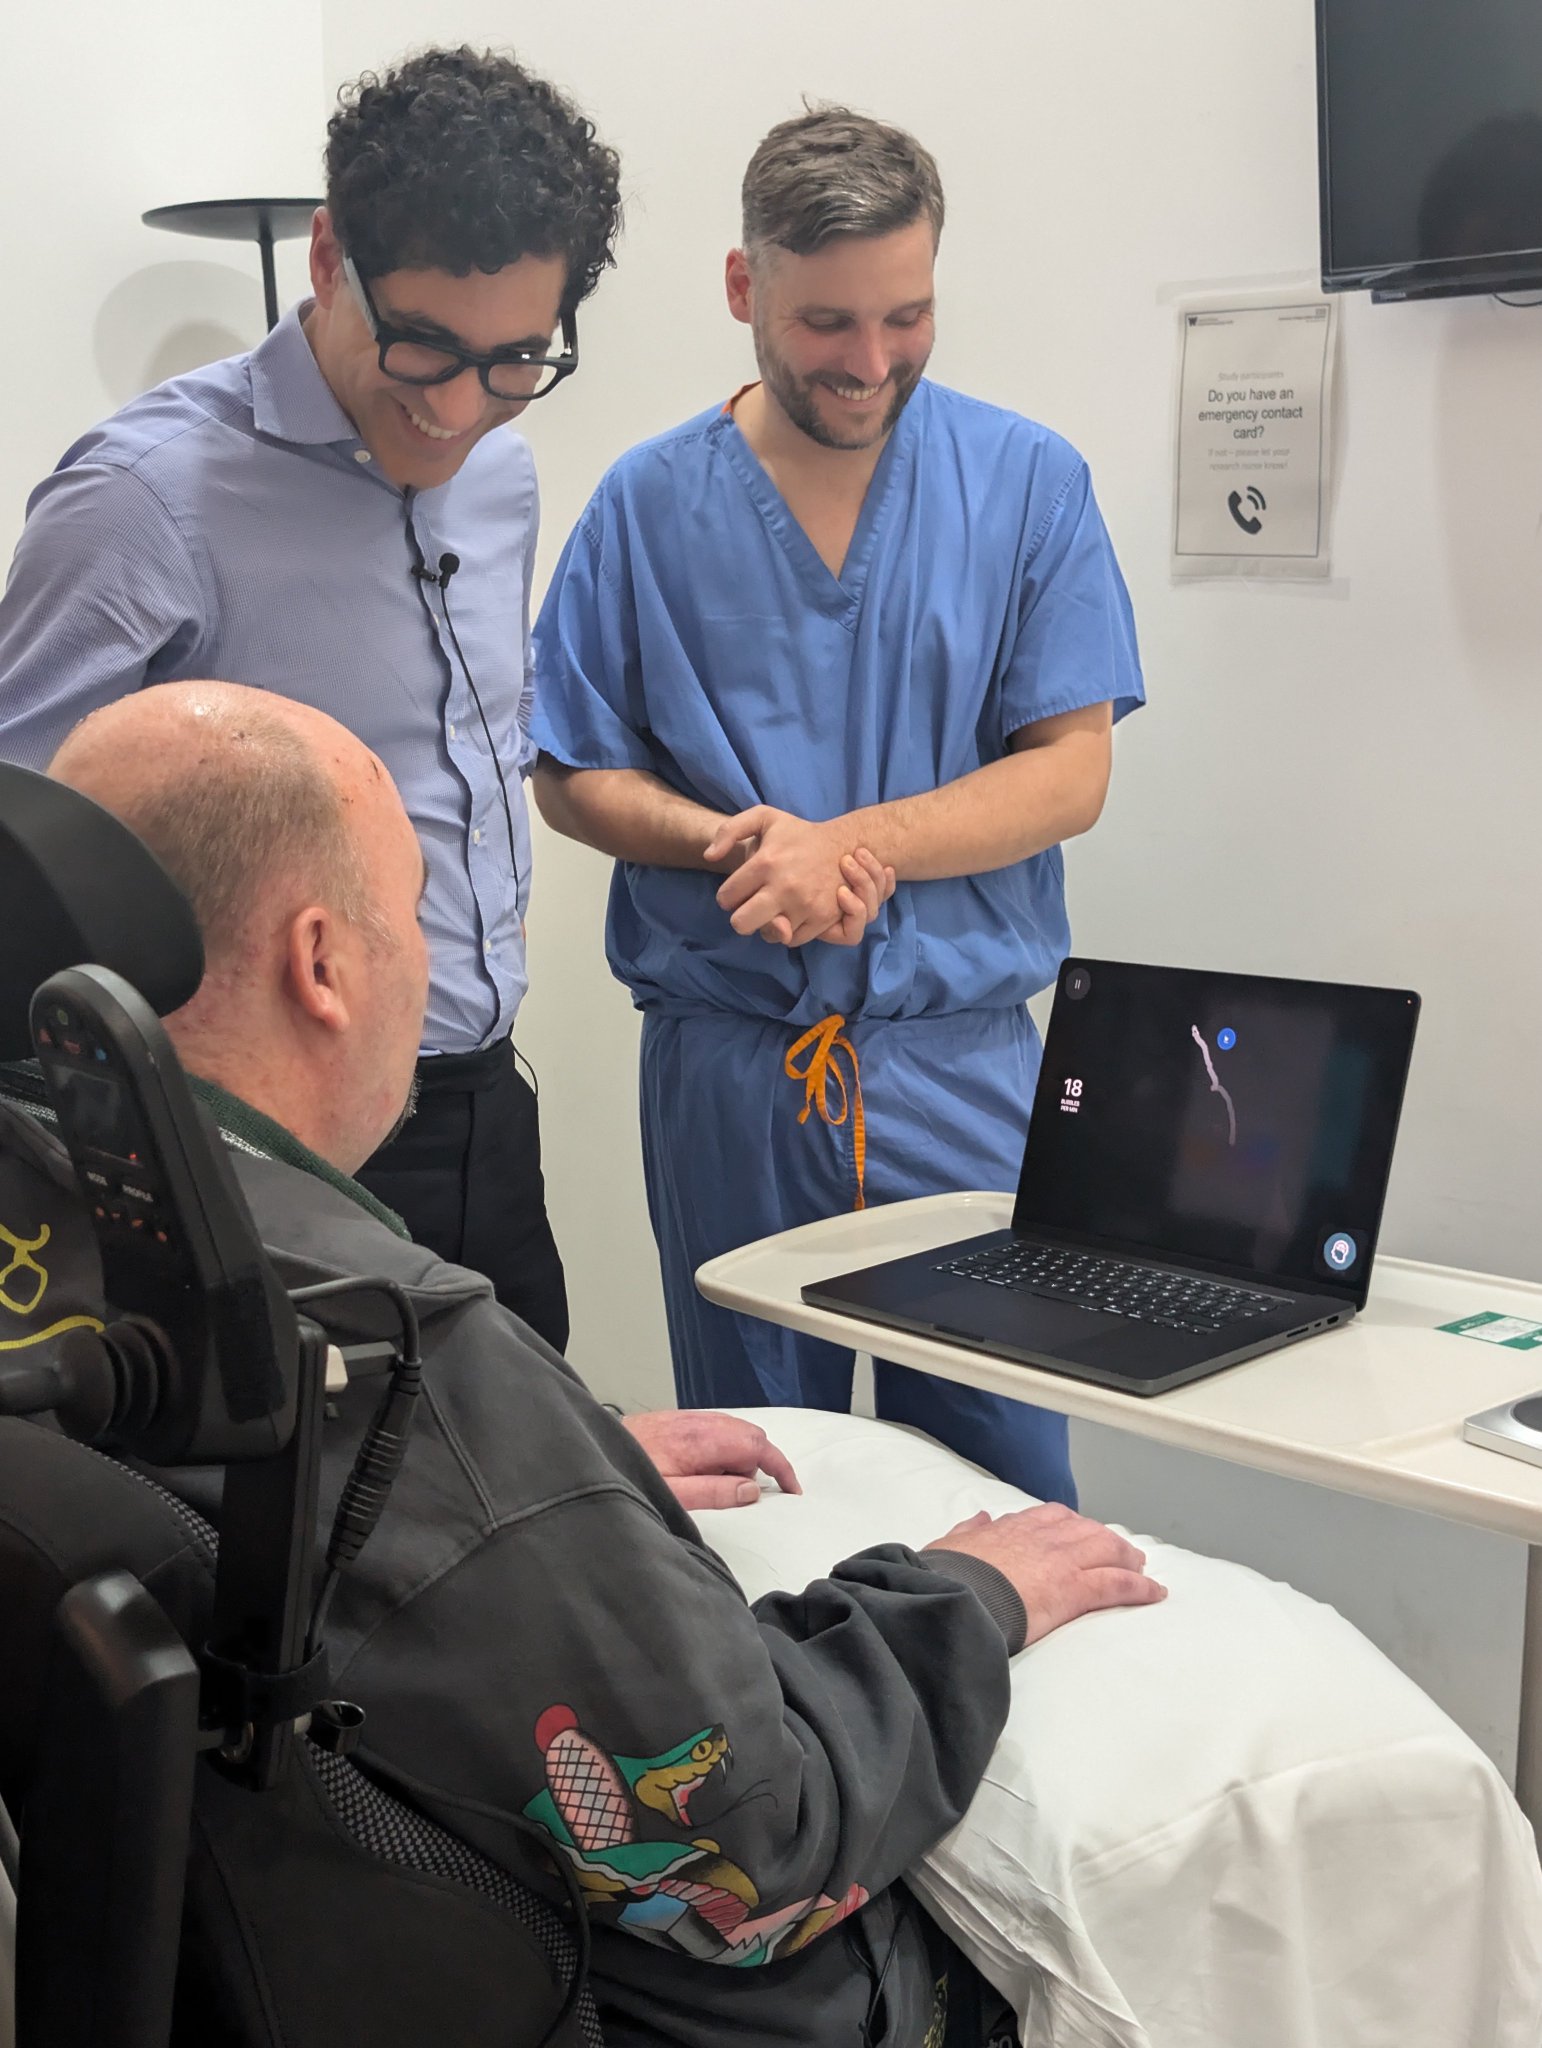
Neuralink 2025: FDA Breakthrough Designation and UAE Clinical Trial
By
–
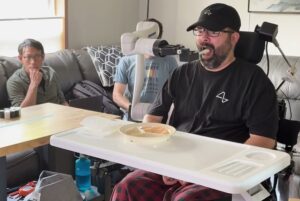
NEURALINK 2025: – Received FDA Breakthrough Device Designation for its speech restoration technology targeting severe speech impairments. – Launched its first clinical trial in the Middle East (UAE-PRIME) at Cleveland Clinic Abu Dhabi in partnership with the Department of