Artificial Analysis measured the time to first token of every reasoning model from o3 to R1. DeepSeek R1 = 103 sec
Qwen3-32B on Cerebras = 1.1 sec We give you R1 level intelligence with 99% latency reduction. Try it: https://
inference.cerebras.ai
HARDWARE
-
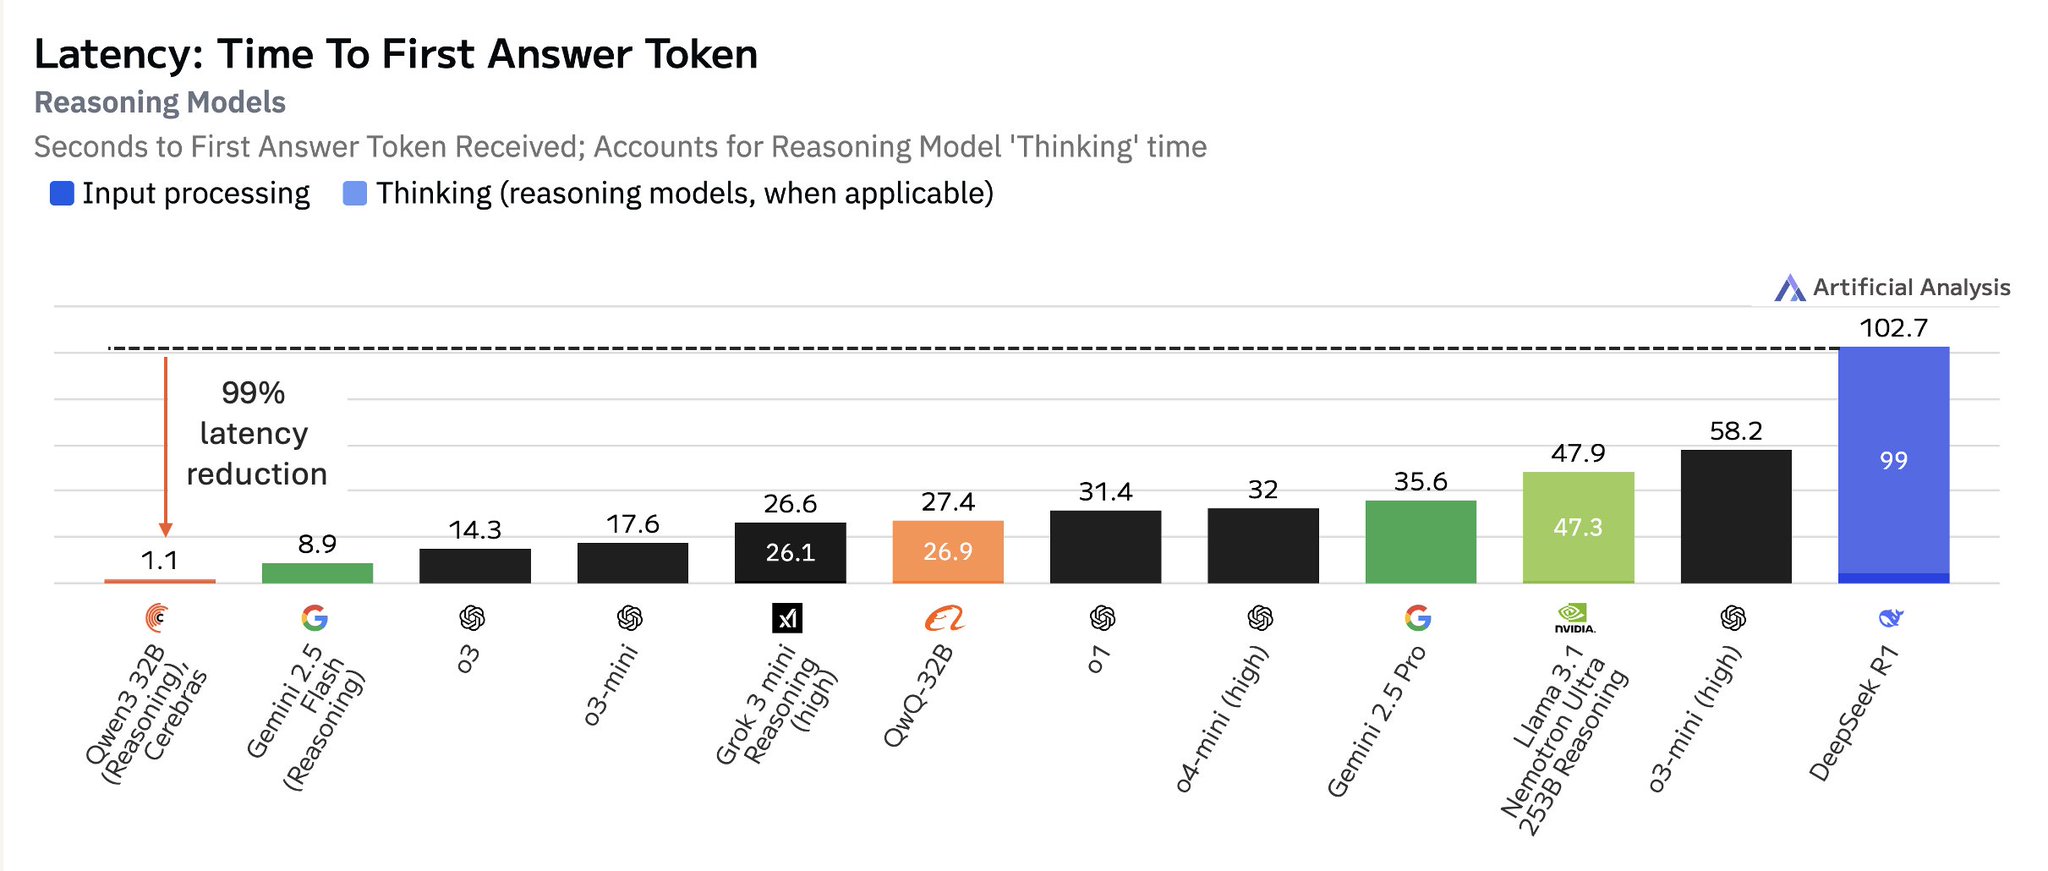
Cerebras Qwen3 achieves 99% latency reduction versus o3
By
–
-
Cerebras Delivers Fastest AI Inference on Poe Platform
By
–
Live on @poe_platform – Cerebras, delivering the fastest inference in the world.
— Cerebras (@cerebras) 20 mai 2025
Build a bot, drop the link below, and we’ll share our favorites. pic.twitter.com/Npkmc294ThLive on @poe_platform – Cerebras, delivering the fastest inference in the world.
Build a bot, drop the link below, and we’ll share our favorites. -
Cerebras Cloud Platform Enables AI Building Today
By
–
Don't wait for the future. Build it: http://
cloud.cerebras.ai -
On-demand 64-GPU clusters offer immense computing power for budget-conscious developers.
By
–
You can even deploy clusters with 64 GPUs on-demand…
— AI Breakfast (@AiBreakfast) 20 mai 2025
This opens up an insane amount of computing power for developers who can’t afford long term contracts. pic.twitter.com/7VfjKDY75HYou can even deploy clusters with 64 GPUs on-demand… This opens up an insane amount of computing power for developers who can’t afford long term contracts.
-
Google Beam: Project Starline Evolves Into 3D Video Communications
By
–
Hi Google Beam👋! What started as Project Starline has evolved into a revolutionary 3D video communications platform. The combination of our AI video model and light field display allows you to make eye contact and read subtle cues as if you were face-to-face 🤯… pic.twitter.com/VlsIZz9Uzx
— Google AI (@GoogleAI) 20 mai 2025Hi Google Beam! What started as Project Starline has evolved into a revolutionary 3D video communications platform. The combination of our AI video model and light field display allows you to make eye contact and read subtle cues as if you were face-to-face
-

NVIDIA Accelerates Enterprise AI Factory Infrastructure Shift
By
–
We are accelerating the trillion-dollar #IT infrastructure shift to enterprise #AIfactories with RTX PRO™ Servers and a new NVIDIA Enterprise AI Factory validated design for data centers that boost AI, design, engineering, and business applications. Learn more in our newsroom:
-
Voyager SDK Enables Edge AI Computer Vision Deployment
By
–
Build #AI at the edge without the complexity.
The Voyager SDK from @AxeleraAI makes it easy to deploy high-performance computer vision apps using our #modelzoo or your own models. New video: Quick intro, demos, real-time inference & more – https://
eu1.hubs.ly/H0kfpHm0 -
Metal Kernels Datasets for Machine Learning Computing
By
–
That's super cool. Have you seen datasets of not Triton kernels but Metal?
-
Enterprise AI Scaling: Dell’s AI Factory with Gaudi 3
By
–
Why is enterprise AI so hard to scale and what if it didn’t have to be?
— Helen Yu (@YuHelenYu) 20 mai 2025
In this clip, Chad Dunn of @DellTech explains how the AI Factory, built in partnership with @Intel and powered by Gaudi 3 accelerators, is removing the complexity from scaling GenAI in the enterprise.
🤝… pic.twitter.com/ahCW713Op3Why is enterprise AI so hard to scale and what if it didn’t have to be? In this clip, Chad Dunn of @DellTech explains how the AI Factory, built in partnership with @Intel and powered by Gaudi 3 accelerators, is removing the complexity from scaling GenAI in the enterprise.
-

Axelera AI Showcases Real-time Analytics and 8K Inference Hardware
By
–
Meet Axelera AI at #COMPUTEX2025 | We're live and ready! 20–23 May | Taipei Aetina (J0118): 4x4K real-time analytics + IC sorting Microip (I1413c): 8K inference demo AI for real-world results.
#AxeleraAI #EdgeAI #AIHardware