Zuck's Personal Superintelligence.
First iron-air battery connected to grid.
Profluent Bio releases OpenCRISPR-1 model.
Figma crushes IPO, currently trading at 4 Linas.
Abundance x Jason Carman drop Zipline video. + Means & Meaning What a week for the optimists.
HARDWARE
-
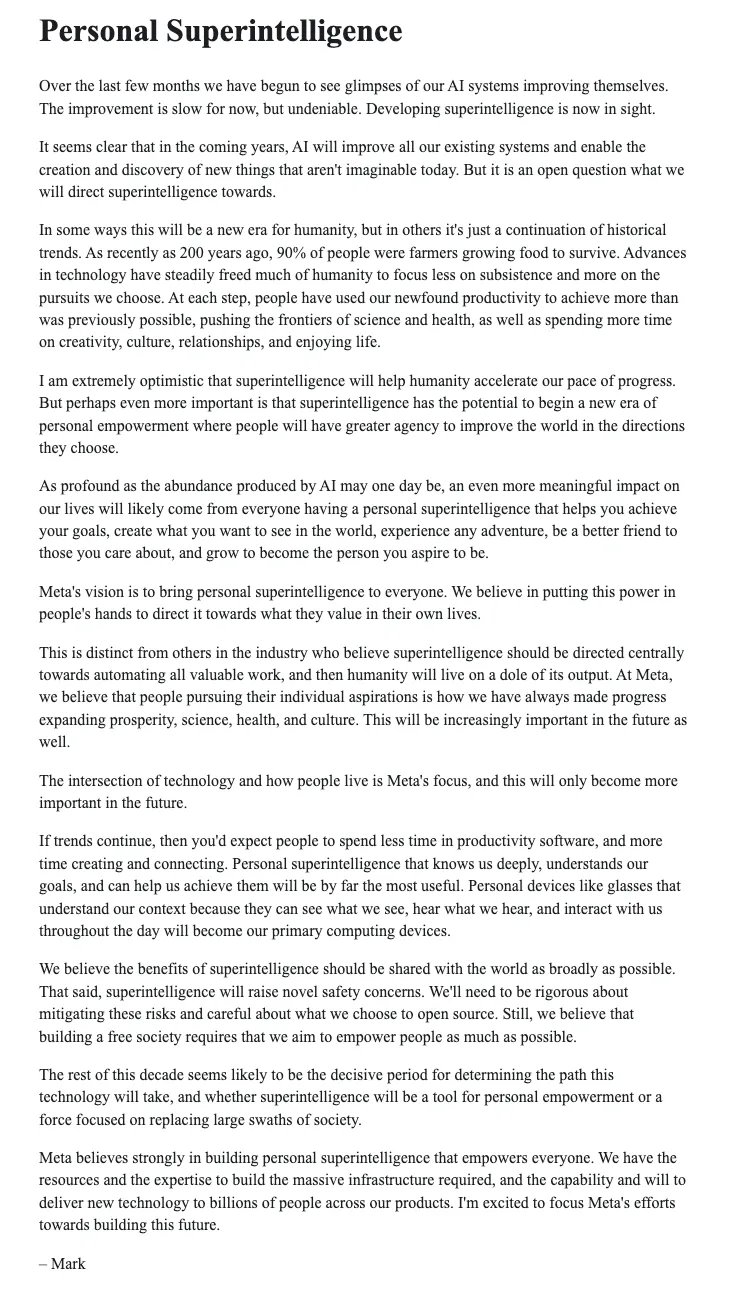
Week of AI breakthroughs: superintelligence, batteries, CRISPR, IPO
By
–
-
Qwen 4bit and 6bit Model Memory Requirements Guide
By
–
The 4bit model should work comfortably on 32GB, the 6bit might just fit on that too If you have 16GB or less you're out of luck for this particular Qwen model
-
Context Window Performance and RAM Requirements for AI Models
By
–
60 tokens a second, context window is supposedly up to 262,144 but that will use a ton more RAM, probably more than my Mac can handle (I've not tried though)
-
Running Qwen3-Coder-Flash 30B on M2 MacBook Pro
By
–
Here's the pelican riding a bicycle and the implementation of space invaders I got from running the 24.82GB 6bit MLX version of Qwen3-Coder-30B-A3B-Instruct – aka Qwen3-Coder-Flash – on my 64GB M2 MacBook Pro
-

NVIDIA RTX Rendering Day showcases AI-powered real-time ray tracing
By
–
Join us for NVIDIA #RTXRenderingDay on Tuesday, August 12th, at #SIGGRAPH and experience the latest breakthroughs in real-time ray tracing, AI-powered denoising, and next-gen rendering workflows. From photorealistic lighting and shadows to faster, smarter 3D content creation,
-
M2 Mac Experience and LocalLLaMA Community Recommendations
By
–
I have no idea I'm afraid – I don't have any personal experience with anything other two my M2 Mac I'd hit up r/LocalLLaMA for opinions on that
-
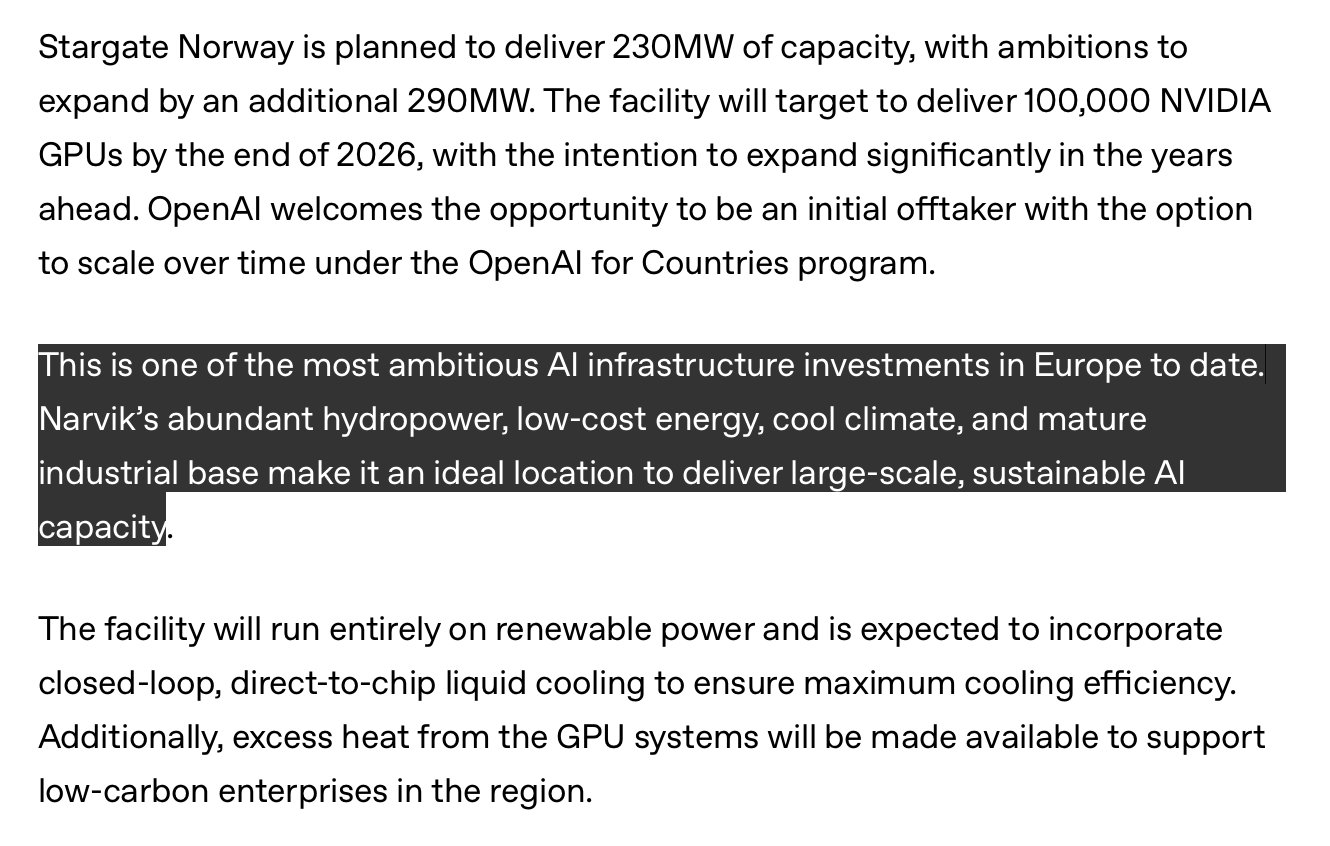
Stargate Norway to Deliver 100k NVIDIA GPUs by 2026
By
–
100k NVIDIA GPUs for Europe Stargate Norway is planned to deliver 230MW of capacity, with ambitions to expand by an additional 290MW. The facility will target to deliver 100,000 NVIDIA GPUs by the end of 2026, with the intention to expand significantly in the years ahead.
-
MLX Model Requires 96GB RAM, Runs Space Invaders Game
By
–
This full precision MLX model needs 63.5GB of RAM while running (so likely needs a Mac with 96GB or 128GB) – but its space invaders is fully functional! https://t.co/0TVkYrAIxV
— Simon Willison (@simonw) 31 juillet 2025This full precision MLX model needs 63.5GB of RAM while running (so likely needs a Mac with 96GB or 128GB) – but its space invaders is fully functional!
-

Running 30B Model on Mac via MLX Framework
By
–
Since this is a 30B model it should be possible to run it on a 64GB or maybe even a 32GB Mac via MLX
-
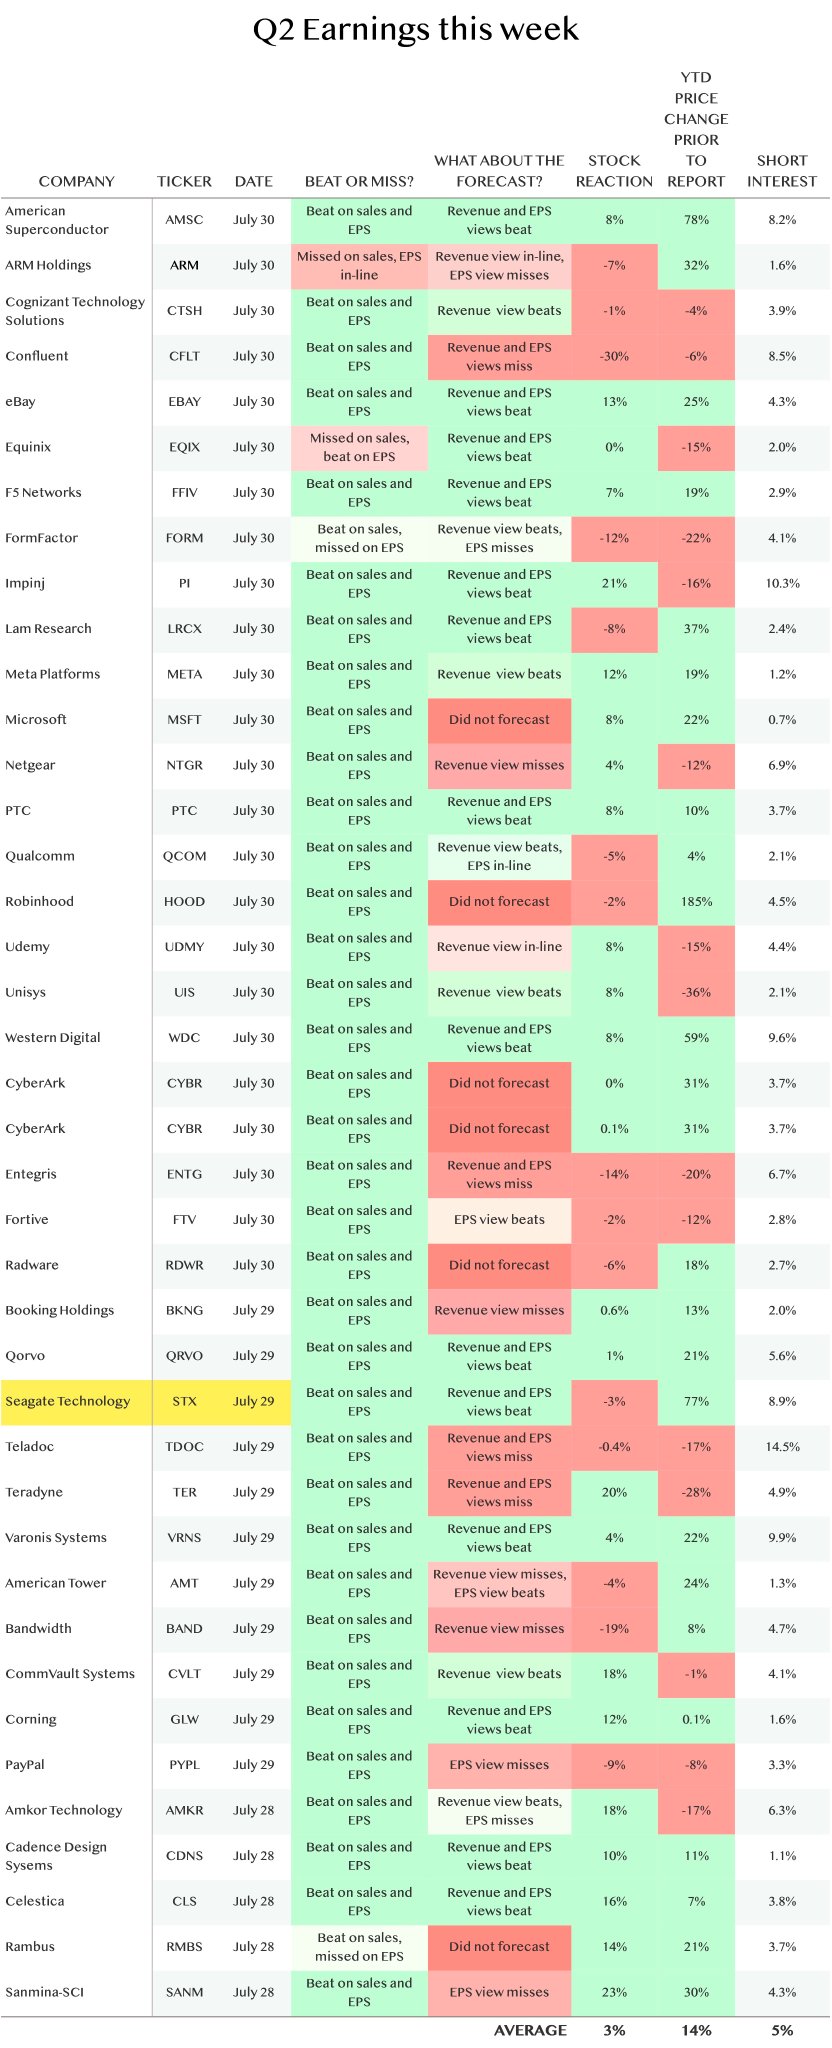
Microsoft Meta outspend ARM on AI chip capital investment
By
–
Spend big if you’re Microsoft, Meta, not so much for ARM Microsoft and Meta continued a streak of demolishing any doubts about their enormous capital spending, while ARM has a problem, as its intent to invest more deeply into actual chips threatens to up-end what had been a