Breakthrough: @moderna_tx and @IBM are teaming up to supercharge mRNA drug design using quantum computing. By leveraging variational quantum algorithms (VQAs), they’re tackling the challenge of predicting #mRNA secondary structures—key to accelerating next-gen therapies.
HARDWARE
-
Humanoid Robot Masters Fried Rice Cooking From Scratch
By
–
Look at this robot make fried rice from scratch!
— Amitav Bhattacharjee (@bamitav) 17 août 2025
pic.twitter.com/Zk8N1tmJk8#Cooking #chef #AI #ArtificialIntelligence #technology #tech #robotech #Robots #robotics #humanoidrobot #humanoid @sonu_monika @enilev @Jagersbergknut @TysonLester @chidambara09 @labordeolivier…Look at this robot make fried rice from scratch! #Cooking #chef #AI #ArtificialIntelligence #technology #tech #robotech #Robots #robotics #humanoidrobot #humanoid @sonu_monika @enilev @Jagersbergknut @TysonLester @chidambara09 @labordeolivier
-
SLMs offer efficiency; LLMs require massive resources. Keep improving.
By
–
clean point, slms got that efficiency while llms need a whole server farm to stretch, keep stacking those gains
-
Chinese Robot Decompresses After Hard Work Day
By
–
🇨🇳 A robot in China decompressing after a hard day at work!
— Amitav Bhattacharjee (@bamitav) 17 août 2025
pic.twitter.com/80RNIKL0p8#AI #ArtificialIntelligence #technology #tech #robotech #Robots #robotics #HumanoidRobots #humanoid @sonu_monika @enilev @Jagersbergknut @TysonLester @chidambara09 @labordeolivier @BetaMoroney…A robot in China decompressing after a hard day at work! #AI #ArtificialIntelligence #technology #tech #robotech #Robots #robotics #HumanoidRobots #humanoid @sonu_monika @enilev @Jagersbergknut @TysonLester @chidambara09 @labordeolivier @BetaMoroney
-
Multi-GPU Training Strategies for Deep Learning Models
By
–
By default, deep learning models only utilize a single GPU for training, even if multiple GPUs are available.
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
An ideal way to train models is to distribute the training workload across multiple GPUs.
The graphic depicts four strategies for multi-GPU training👇 pic.twitter.com/rEKkFw3pF3By default, deep learning models only utilize a single GPU for training, even if multiple GPUs are available. An ideal way to train models is to distribute the training workload across multiple GPUs. The graphic depicts four strategies for multi-GPU training
-
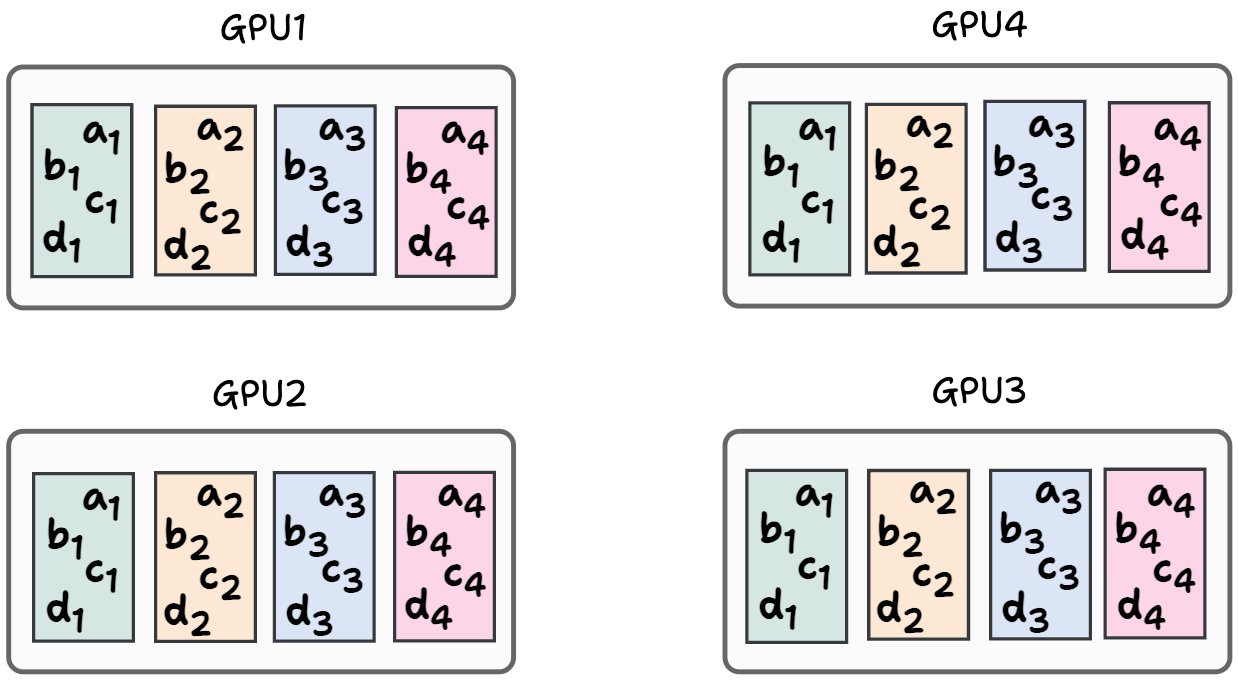
Ring Approach for Scalable Model Weight Synchronization Across GPUs
By
–
And there you go! Model weights across GPUs have been synchronized. While the total elements transferred is still the same as we had in the “single-GPU-master” approach, this ring approach is much more scalable since it does not put the entire load on one GPU. Check this
-
Phase 2: Share-only segment transfer across GPUs
By
–
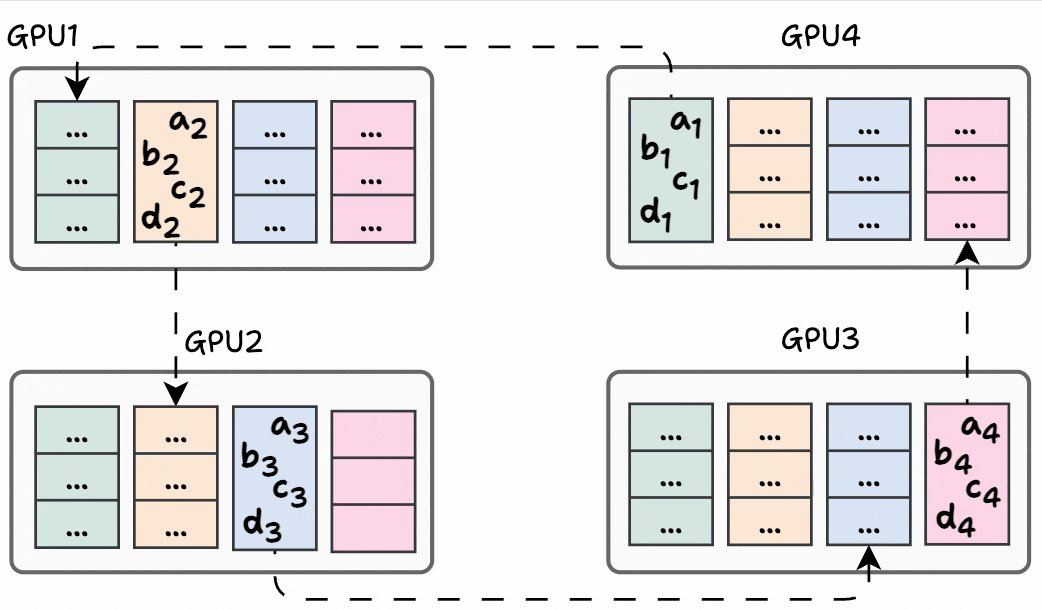
Phase #2) Share-only
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
Now that each GPU has one entire segment, we can transfer these complete segments to all other GPUs.
The process is carried out similarly to what we discussed above, so we won’t go into full detail.
Iteration 1 is shown below👇 pic.twitter.com/7MssxcJfoEPhase #2) Share-only Now that each GPU has one entire segment, we can transfer these complete segments to all other GPUs. The process is carried out similarly to what we discussed above, so we won’t go into full detail. Iteration 1 is shown below
-
GPU Segment Transfer and Distribution Strategy
By
–
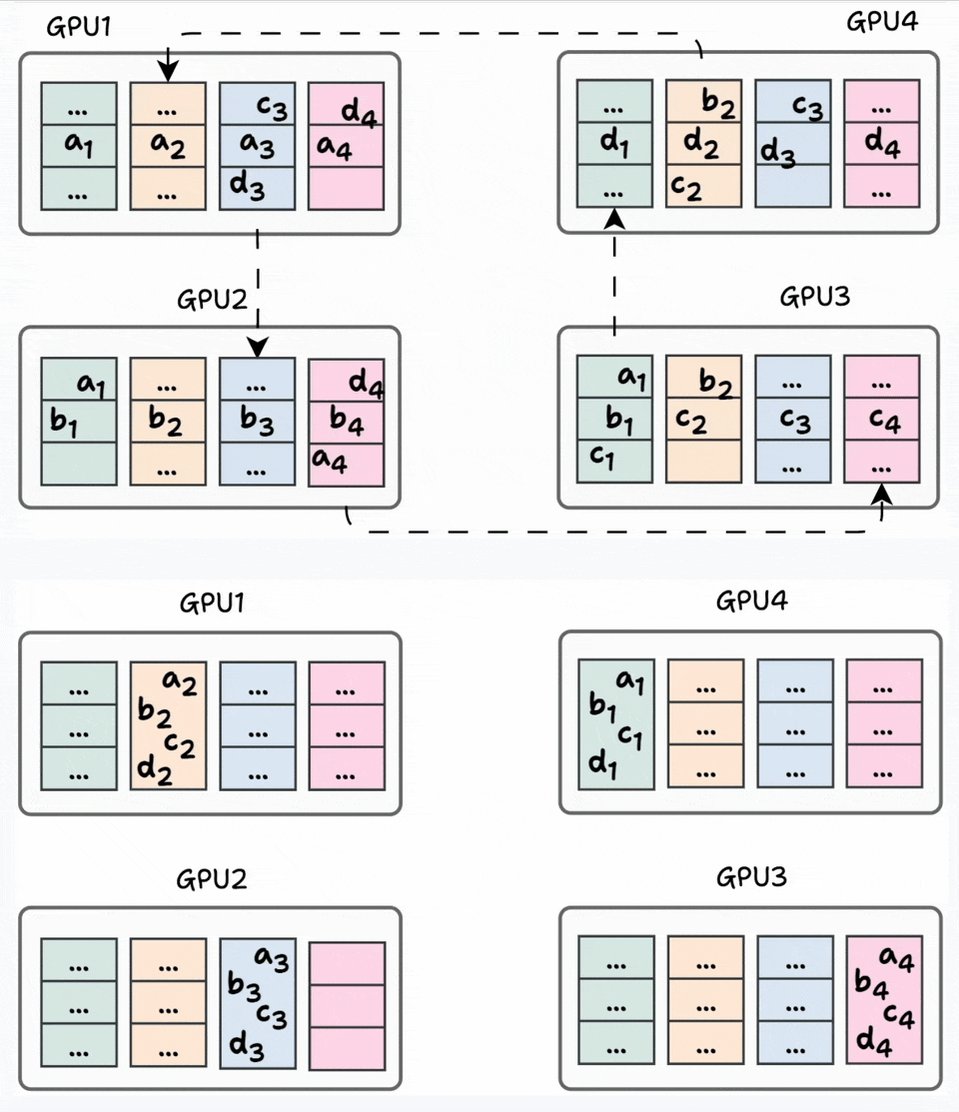
In the final iteration, the following segments are transferred to the next GPU.
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
This leads to a state where every GPU has one entire segment, and we can transfer these complete segments to all other GPUs.
Check this 👇 pic.twitter.com/0EknVEN7IvIn the final iteration, the following segments are transferred to the next GPU. This leads to a state where every GPU has one entire segment, and we can transfer these complete segments to all other GPUs. Check this
-
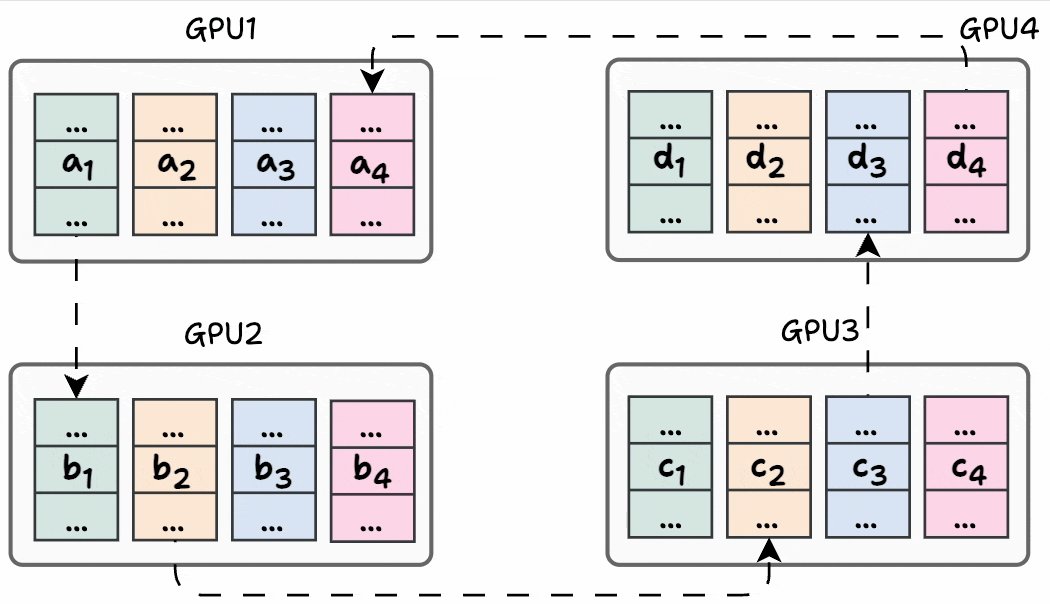
GPU Ring Communication: Data Segment Distribution Pattern
By
–
In an iteration, each GPU sends a segment to the next GPU:
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
– GPU1 sends a₁ to GPU2, where it is added to b₁
– GPU2 sends b₂ to GPU3, where it is added to c₂
– GPU3 sends c₃ to GPU4, where it is added to d₃
– GPU4 sends d₄ to GPU1, where it is added to a₄
Check this 👇 pic.twitter.com/aMc08xJwhpIn an iteration, each GPU sends a segment to the next GPU: – GPU1 sends a₁ to GPU2, where it is added to b₁
– GPU2 sends b₂ to GPU3, where it is added to c₂
– GPU3 sends c₃ to GPU4, where it is added to d₃
– GPU4 sends d₄ to GPU1, where it is added to a₄ Check this -

GPU Optimization: Scaling Challenges in Distributed Gradient Communication
By
–
We can optimize this by transferring all elements to one GPU, computing the final value, and sending it back to all other GPUs.
— Akshay 🚀 (@akshay_pachaar) 17 août 2025
This is a significant improvement.
But now a single GPU must receive, compute, and communicate back the gradients, so this does not scale. pic.twitter.com/xgZJ5FdymfWe can optimize this by transferring all elements to one GPU, computing the final value, and sending it back to all other GPUs. This is a significant improvement. But now a single GPU must receive, compute, and communicate back the gradients, so this does not scale.