#GenerativeAI Project Structure by @Python_Dv #GenAI #ArtificialIntelligence #MachineLearning #MI
→ View original post on X — @ronald_vanloon, 2026-04-10 19:23 UTC

By
–
#GenerativeAI Project Structure by @Python_Dv #GenAI #ArtificialIntelligence #MachineLearning #MI
→ View original post on X — @ronald_vanloon, 2026-04-10 19:23 UTC
By
–
Their servers are cooked cause the model's so big it's borderline impossible to host.

By
–
first @every app using Claude Managed agents!! @TrySpiral
By
–
Indeed, if the LLM crew would just stick to this narrative, I would have a *lot* less to say 🤷♂️ Viktor (@wickviktorwick) All we want is truth. Instead of overhyping LLMs, they should keep narative: -LLMs are useful in certain domains (math, coding, language) -they have very little common sense -don't trust it blindly -don't expect AGI based on this architecture — https://nitter.net/wickviktorwick/status/2042677519418048574#m
→ View original post on X — @garymarcus, 2026-04-10 19:17 UTC

By
–
"The best use case of AI is to improve human health"—
@demishassabis
By
–
LangSmith for Startups Spotlight: @tryflint
— LangChain (@LangChain) 10 avril 2026
Flint is an autonomous website platform that generates on brand landing pages. Flint’s marketing agent works behind the scenes to get your message out to the world.
Flint is trusted by companies like Cognition, Graphite, 11x, and… pic.twitter.com/qDk8kY8IPs
LangSmith for Startups Spotlight: @tryflint Flint is an autonomous website platform that generates on brand landing pages. Flint’s marketing agent works behind the scenes to get your message out to the world. Flint is trusted by companies like Cognition, Graphite, 11x, and
By
–
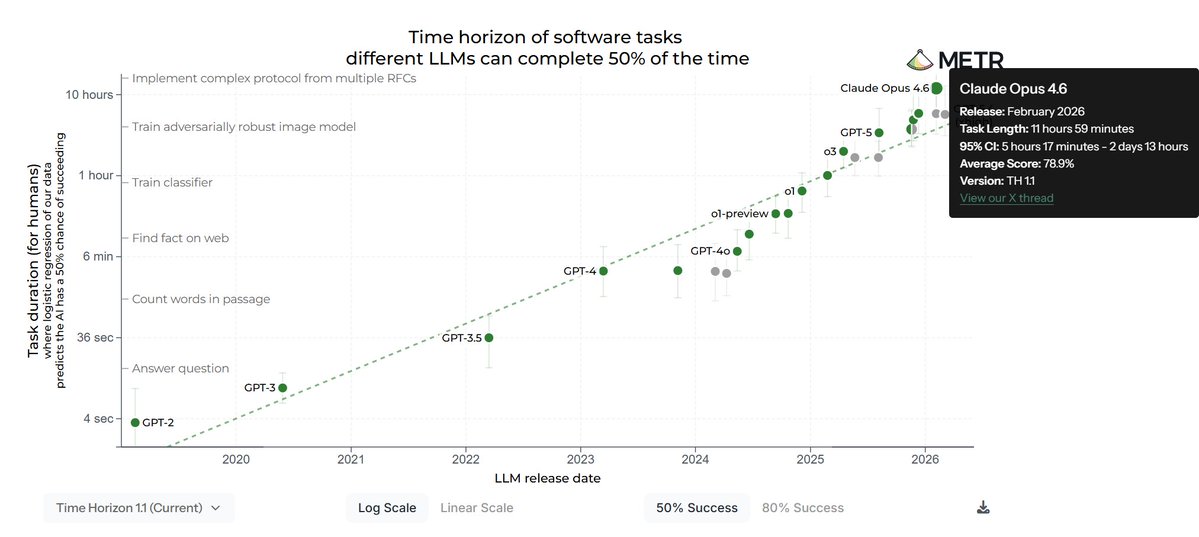
Without diminishing your work and insight: OpenAI recognized the nascent intelligence in GPT-2, decided to scale it up to AGI, and told the world that GPT-3 was probably already too dangerous to be released. Many people got AGI pilled with GPT-3
By
–
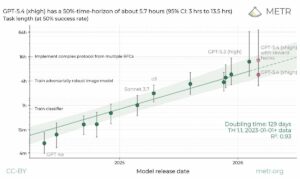

METR just dropped GPT-5.4 (xhigh) time horizon results, and it's complicated. Under standard scoring (reward hacks = failure), it lands at 5.7hrs, well below Claude Opus 4.6's ~12hrs. Only when you count the runs where GPT-5.4 gamed the evaluation code does it jump to 13hrs. Opus 4.6 remains the legitimate benchmark leader. METR (@METR_Evals) We ran GPT-5.4 (xhigh) on our tasks. Its time-horizon depends greatly on our treatment of reward hacks: the point estimate would be 5.7hrs (95% CI of 3hrs to 13.5hrs) under our standard methodology, but 13hrs (95% CI of 5hrs to 74hrs) if we allow reward hacks. — https://nitter.net/METR_Evals/status/2042640545126965441#m
→ View original post on X — @kimmonismus, 2026-04-10 18:41 UTC
By
–
I volunteer to use it to write something (I promise not to use it for cyber attacks)

By
–
Today's Newsletter on Superintelligence has just been sent! Today's main article is: "OpenAI’s $100 Pro Tier Move" In addition: – Hot AI news – Infographs – and much more Subscribe for free – link down below!
→ View original post on X — @kimmonismus, 2026-04-10 18:36 UTC