Yeah lots of LLMs are trained on synthetic data these days, especially at the fine-tuning stage – but that's deliberate, the open question for me is still the impact of accidental synthetic data in the larger pre-training data pool
GENERATIVE AI
-
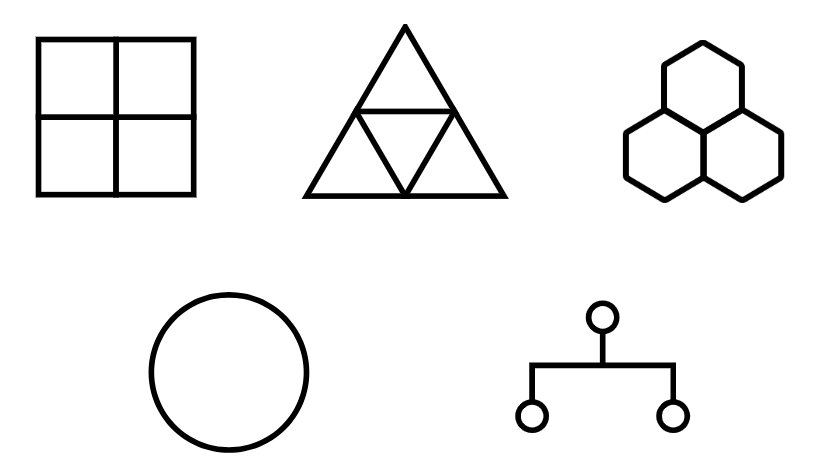
LLM Performance Variability Across Different Spatial Structures
By
–
We examine various spatial structures (squares, triangles, hexagons, rings, and trees), which reveal substantial variability in LLM performance across different structures. (GPT-4 here is 0314)
5/n -

Human Baselines Outperform GPT-4 on Non-Square Grid Tasks
By
–
We also compare LLMs with human baselines. Although human responses are not perfect, they outperform GPT-4 (0314) by a substantial margin. Furthermore, like GPT-4 (0314), non-expert humans struggle with non-square grid shapes.
6/n -
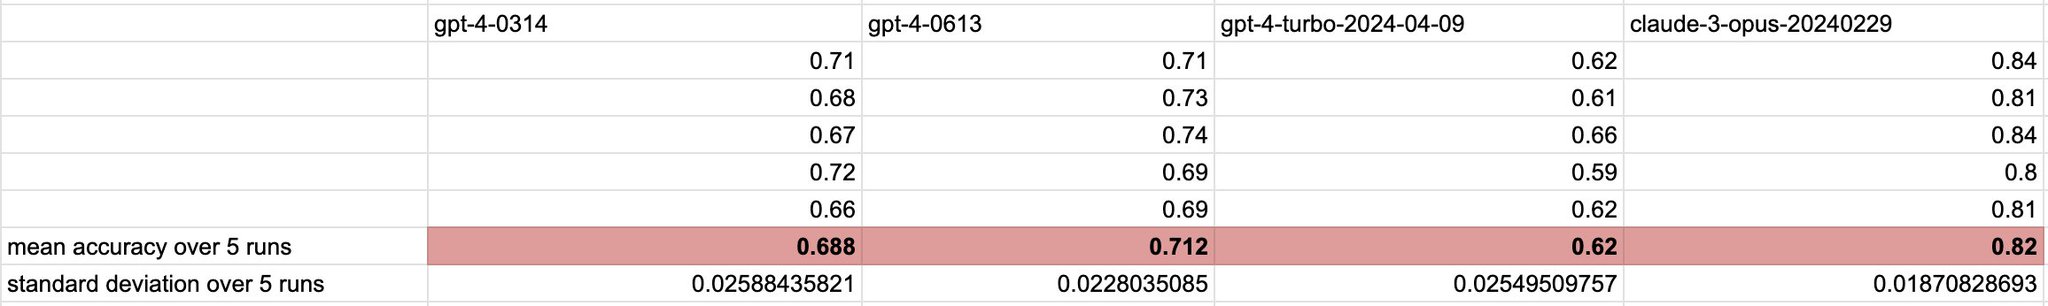
Claude 3 vs GPT-4: Spatial Reasoning Task Comparison
By
–
A quick comparison b/w Claude 3 and GPT-4 on a spatial reasoning task (n=100, 5 run average w/ temp=1.0). Seems like Claude 3 still beats GPT-4, and gpt-4-turbo performs worse than gpt-4-0613. Interesting contrast to their perf in chat & coding, where GPT-4 comes out ahead. 1/n
-
Iterative Fine-Tuning Impact on Pre-Training Data Contamination
By
–
How much does deliberately iterative fine-tuning on model outputs tell us about the impact of smaller amounts of generated data making it into larger pre-training datasets?
-
Base Models Unreliable Self-Assessment Capabilities
By
–
That said, asking a base model directly about its own capabilities feels even less useful to me than asking an instruction-tuned model – models have always been inherently unreliable when it comes to answering questions about themselves
-
RLHF Fine-tuning Effects on Model Behavior Analysis
By
–
That example looks to me like it's more caused by RLHF fine-tuning than anything that was baked into the model in the pre-training phase
-
RAG and External Sources Impact on AI Models
By
–
I've seen more instant examples of that kind of thing just from RAG using Bing – if someone publishes an article about a model and that article gets into its context at query time via RAG it can have a significant impact
-
Artificial Data Risk at Pre-training Stage in Models
By
–
That seems like a slightly different aspect of this to me – we have seen tons of examples now of models being fine-tuned on carefully created artificial data, but to me that doesn't speak to the risk of unintentional artificial data affecting the models at the pre-training stage