If you just want to try it as a user https://
meta.ai is running Llama 3 with the ability for it to execute and summarize searches
GENERATIVE AI
-
Meta AI Launches Llama 3 with Search and Summarization
By
–
-
Llama 3 API Search Capabilities vs Perplexity Sonar
By
–
I've not see a Llama 3 API with built in search capacity yet – @perplexity_ai have sonar-medium-online but I think that's Mixtral 8x7B? They might upgrade to a Llama 3 online model soon though
-
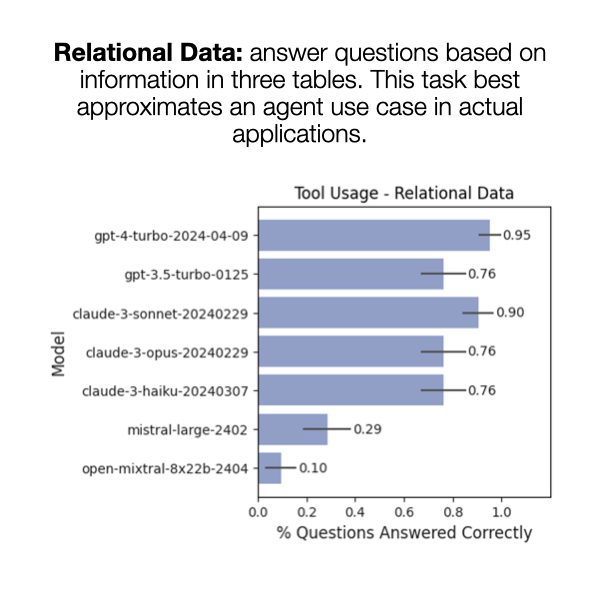
Benchmarking Results: OpenAI and Anthropic Lead Agent Performance
By
–
Benchmarking Agents We’re happy to share updated benchmarking results using `langchain-benchmarks` to evaluate agents based on different models. @OpenAI and @AnthropicAI take the lead across a variety of tasks. For more explanation about the various benchmarking
-
Free GPT-4 and Llama 3 alternatives to ChatGPT
By
–
There really is no reason anyone should be using free ChatGPT-3.5 anymore. Not only can you still get GPT-4 access for free through Microsoft Copilot (in creative mode), but if you want a GPT-3.5 class model, Llama 3 is much better & free (for now), here: https://
meta.ai -
Open Models Drive Rapid AI Capability Improvements and Speed
By
–
Because anyone can work with them, open models are likely to improve very quickly, creating a lot of capabilities focused on factors ranging from speed to costs.
— Ethan Mollick (@emollick) 19 avril 2024
Here is the new Llama 3 70B being served by Groq (with a q) at 224 tokens/second. This is real-time of me using it. pic.twitter.com/L6i6T6OBbWBecause anyone can work with them, open models are likely to improve very quickly, creating a lot of capabilities focused on factors ranging from speed to costs. Here is the new Llama 3 70B being served by Groq (with a q) at 224 tokens/second. This is real-time of me using it.
-

LangChain Weekly Release: Evaluations, Tool Calling, Monitoring
By
–
LangChain Release Notes, week of 4/15 Evaluations video series Standardized tool calling in LangChain Production monitoring and automations in LangSmith New RAG From Scratch videos
Community created content! Read it all here: https://
blog.langchain.dev/week-of-4-15-l
angchain-release-notes/
… -
RAG vs Fine-tuning for Small Document Loading
By
–
My understanding is that if you want to eg load your company employee handbook (~20 page PDF) into a model you're likely to get much better results with RAG than with fine-tuning – can you fine tune such that the model reliable answers questions about something that small?
-

Open-Source Model Beats Claude 3 Opus at 300 Tokens Per Second
By
–
We now have an open-source model that is beating Claude 3 Opus…
— Matt Shumer (@mattshumer_) 19 avril 2024
being served at nearly **300 tokens per second** on @GroqInc.
The applications built off of this tech will be nothing short of revolutionary. pic.twitter.com/v934g0rwU5We now have an open-source model that is beating Claude 3 Opus… being served at nearly **300 tokens per second** on @GroqInc
. The applications built off of this tech will be nothing short of revolutionary. -
Groq Serves LLaMA 3 at Record 800 Tokens Per Second
By
–
My mind is blown.@GroqInc is serving LLaMA 3 at over 800 tokens per second!
— Matt Shumer (@mattshumer_) 19 avril 2024
800. Tokens. Per. Second.
This unlocks so many incredible use-cases.
It's one thing to see my demo — it's another thing entirely to experience it for yourself.
Do yourself a favor and try it asap. pic.twitter.com/Rd5NW5SDlWMy mind is blown. @GroqInc is serving LLaMA 3 at over 800 tokens per second! 800. Tokens. Per. Second. This unlocks so many incredible use-cases. It's one thing to see my demo — it's another thing entirely to experience it for yourself. Do yourself a favor and try it asap.
-

Breaking Down the Wildest AI News Week
By
–
We've just experienced the craziest week in #ArtificialIntelligence in the past year. ChatGPT, GPT-4 Turbo, Mixtral 8x22b, Llama 3… I break down all the latest AI news in my newest video → https://youtu.be/fO4RwiNSeuE