Yeah — simply multiplied rope * 2, trained on long data with a MSL of 16K.
GENERATIVE AI
-
LLaMA 3 70B enables instant code refactoring on Groq
By
–
Using LLaMA 3 70B on @GroqInc to instantly refactor and document code.
— Matt Shumer (@mattshumer_) 22 avril 2024
The implications for software engineering are wild.
Gone are the days of waiting on an LLM for suggestions or code changes.
Now, it's an instant feedback loop.
Demo link in the comments: pic.twitter.com/joLJy4oJ3TUsing LLaMA 3 70B on @GroqInc to instantly refactor and document code. The implications for software engineering are wild. Gone are the days of waiting on an LLM for suggestions or code changes. Now, it's an instant feedback loop. Demo link in the comments:
-
LLaMA 3-based model deployment nearing completion
By
–
Very soon. This is one of the last things I have to get working well before we can push a LLaMA 3-based model live.
-
Extending Context Length for Base Model Development
By
–
Planning to do this for the base model, at least at first. It's more of a learning thing for me, to help me perfect the context length extension approach so I can do it for our internal HyperWrite stuff… so I don't want to do too many variations.
-
LLaMA 3 8B Extended to 16K Token Context Window
By
–
Training a LLaMA 3 8B that supports 16K tokens, twice the current context window. If successful, will open-source it.
-

DigitalOcean CEO Sees Spectacular Opportunity in Generative AI
By
–
Please enjoy my interview with DigitalOcean CEO Paddy Srinivasan DigitalOcean CEO: a ‘spectacular’ opportunity in Gen AI DigitalOcean imploded last summer as the company’s growth slowed considerably. Newly installed CEO Paddy Srinivasan believes the unique needs of generative
-
Neural Operators and Physical Grounding in AI Models
By
–
Thank you @shiringhaffary for covering my @TEDTalks in @business and neural operators for building physical understanding into #AI models. Language and multi-modal models lack physical grounding. models like Sora and some of the robotics models may get some of the physics
-
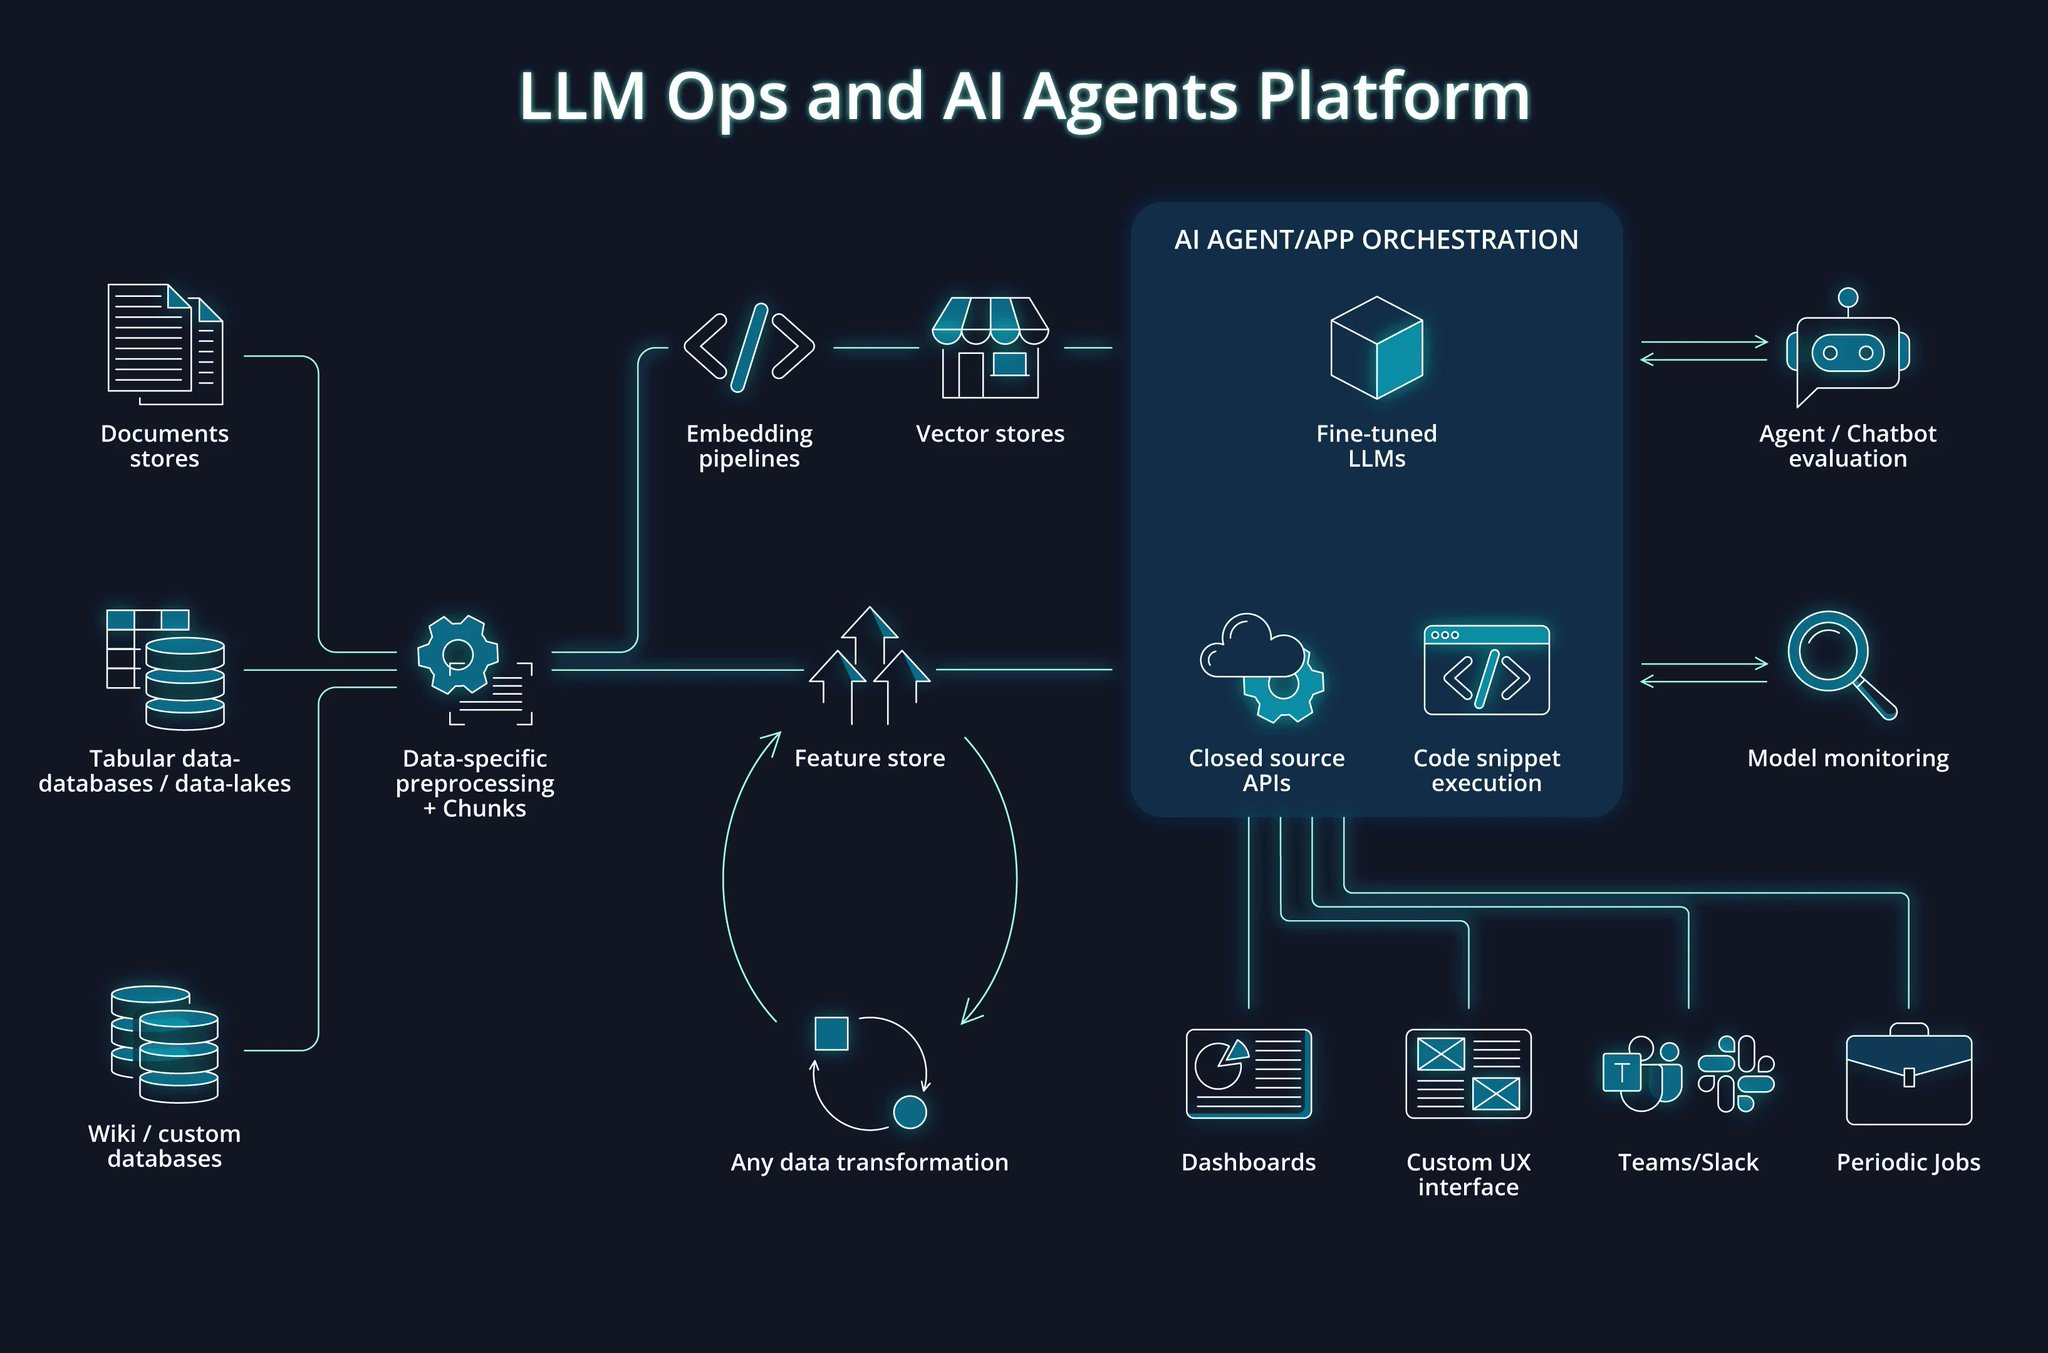
AI Agents Vertical Growing Fast with Dynamic RAG Support
By
–
Our AI Agents vertical is our fastest-growing vertical. It can help you crank out multiple bots to perform different tasks of varying complexity. Some of our customers even want to make 700+ agents! You will need support for:
•Dynamic RAG, information retrieval, and vector -
Mistral Mixtral 8x7B Mixture of Experts Architecture Course
By
–
New short course with @MistralAI !
— Andrew Ng (@AndrewYNg) 22 avril 2024
Mistral's open-source Mixtral 8x7B model uses a "mixture of experts" (MoE) architecture. Unlike a standard transformer, an MoE model has multiple expert feed-forward networks (8 in this case), with a gating network selecting two experts at… pic.twitter.com/VFOg1dDab8New short course with @MistralAI ! Mistral's open-source Mixtral 8x7B model uses a "mixture of experts" (MoE) architecture. Unlike a standard transformer, an MoE model has multiple expert feed-forward networks (8 in this case), with a gating network selecting two experts at